
What is MimicMotion
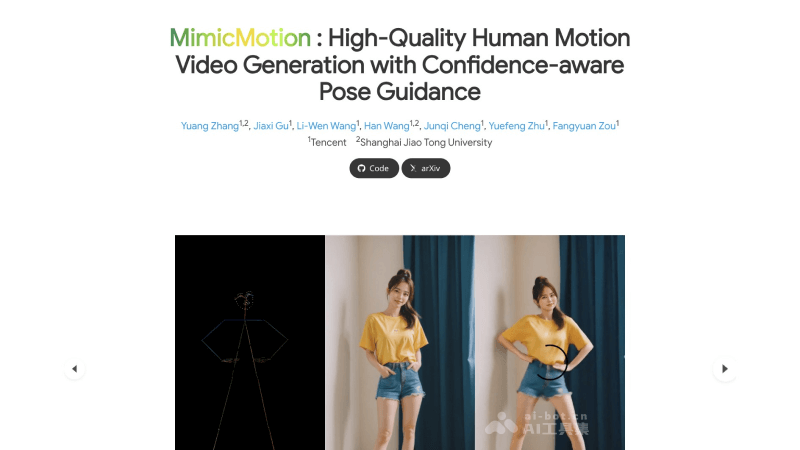
MimicMotion is a high-quality human motion video generation framework launched by Tencent researchers, utilizing confidence-aware pose guidance technology to ensure high quality of video frames and smooth temporal transitions. In addition, MimicMotion significantly reduces image distortion and improves the detail representation of hand movements in portraits through region loss amplification and hand region enhancement. The framework can also generate long videos through a progressive latent fusion strategy, capable of generating high-quality, long-duration human motion videos that conform to specific motion guidance, while significantly improving the controllability and detail richness of video generation.
Features of MimicMotion
- Generate diverse videos: MimicMotion can generate video content of various motions based on the pose guidance provided by the user. Whether it is dance, sports, or daily activities, as long as the corresponding pose sequence is provided, MimicMotion can create the corresponding dynamic video.
- Control video length: Users can specify the duration of the video according to their needs. MimicMotion can generate complete videos ranging from a few seconds of short clips to several minutes or even longer, providing flexibility to adapt to different application scenarios.
- Pose-guided control: The framework uses reference poses as conditions to ensure that the generated video content is consistent with the specified poses in terms of motion. MimicMotion allows users to precisely control the motion in the video, achieving highly customized video generation.
- Detail quality assurance: MimicMotion pays special attention to details in the video, especially areas prone to distortion such as hands. Through a confidence-aware strategy, the system can provide clearer visual effects in these areas.
- Temporal smoothness: To provide a more natural viewing experience, MimicMotion ensures smooth transitions between video frames, avoiding stuttering or incoherence, making the video look smoother and more natural.
- Reduce image distortion: Through confidence-aware pose guidance, MimicMotion can identify and reduce image distortion caused by inaccurate pose estimation, especially in the hand regions of people.
- Long video generation: MimicMotion adopts progressive latent fusion technology, allowing the system to maintain high temporal coherence when generating long videos. This technology effectively avoids flickering and incoherence by fusing latent features between video segments.
- Resource consumption control: When generating videos, MimicMotion optimizes the algorithm to ensure that resource consumption remains within a reasonable range. Even when generating longer videos, it can effectively manage computing resources and avoid excessive costs.
MimicMotion Official Website Entry
- Official project homepage:https://tencent.github.io/MimicMotion/
- GitHub source code repository:https://github.com/Tencent/MimicMotion
- arXiv technical paper:https://arxiv.org/abs/2406.19680
Technical Principles of MimicMotion
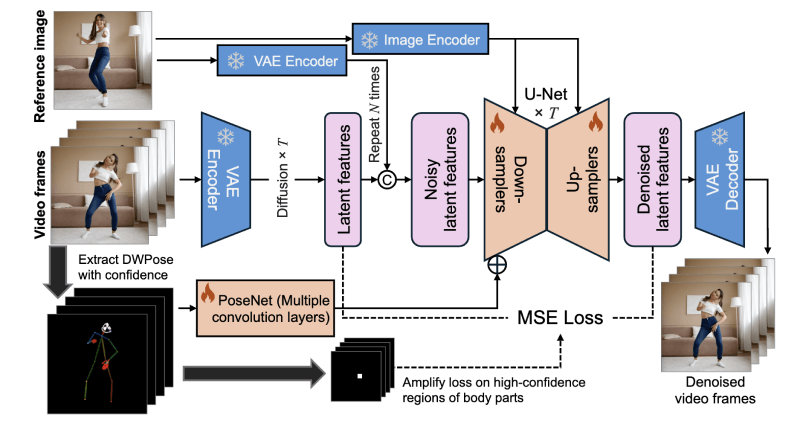
- Pose-guided video generation: MimicMotion uses the pose sequence provided by the user as input conditions to guide the generation of video content, allowing the model to synthesize corresponding motions based on changes in poses.
- Confidence-aware pose guidance: The framework introduces the concept of confidence, weighting each keypoint in the pose sequence by analyzing the confidence scores provided by the pose estimation model. In this way, the model can rely more on keypoints with high confidence, reducing the impact of inaccurate pose estimation on the generated results.
- Region Loss Amplification: Specifically targeting regions prone to distortion, such as the hands, MimicMotion enhances the model's training on these regions by increasing their weight in the loss function, thereby improving the quality of hand details in the generated video.
- Latent Diffusion Model: MimicMotion uses a latent diffusion model to improve generation efficiency and quality. The model performs the diffusion process in a low-dimensional latent space rather than operating directly in pixel space, thereby reducing computational cost.
- Progressive Latent Fusion: To generate long videos, MimicMotion adopts a progressive latent fusion strategy. Between video segments, by gradually fusing the latent features of overlapping frames, it achieves smooth transitions between video segments, avoiding flickering and incoherence that may occur when generating long videos.
- Utilization of Pretrained Models: MimicMotion is based on a pretrained video generation model (such as Stable Video Diffusion, SVD), reducing the amount of data and computational resources required to train the model from scratch.
- Structure of U-Net and PoseNet: MimicMotion's model structure includes a U-Net for spatiotemporal interaction and a PoseNet for extracting features from the pose sequence. These network structures work together to achieve high-quality video generation.
- Cross-Frame Smoothness: MimicMotion considers the temporal relationships between frames during the generation process, ensuring coherence and smoothness between video frames.