
What is Llama3.1
Llama 3.1 is Meta's latest release of an open-source AI model, including three versions: 8B, 70B, and 405B. Among them, the 405B version, with its 405 billion parameters, has become one of the largest open-source models currently available. Llama 3.1 supports a context length of 128K, can handle long texts, and possesses multilingual translation capabilities. It performs excellently in multiple AI benchmarks, especially in mathematics, reasoning, and long-text processing, rivaling top closed-source models on the market such as GPT-4o and Claude 3.5 Sonnet. In addition, Meta also provides the Llama Stack API and security tools, promoting the development of innovative AI applications.
Llama3.1's features
- Context length: Llama 3.1 supports a context length of up to 128K, can process and understand longer text information, and is very beneficial for advanced applications such as long-text summarization and multilingual dialogue.
- Multilingual capability: The model supports eight languages, including English, German, French, Italian, Portuguese, Hindi, Spanish, and Thai, and performs excellently in multilingual translation and cross-cultural communication.
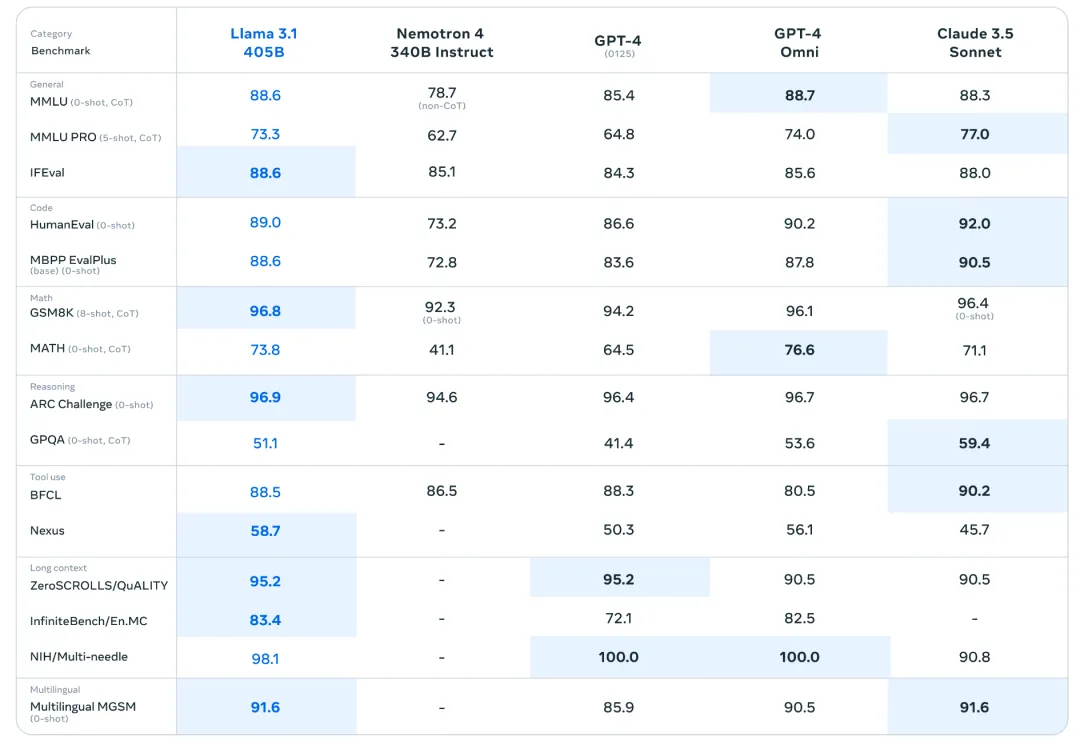
- Mathematical and reasoning capabilities: In mathematical and reasoning tests such as GSM8K and ARC Challenge, Llama 3.1 scores very high, and has very strong capabilities in solving complex mathematical problems and logical reasoning.
- Long-text processing: In the ZeroSCROLLS/QuALITY tests, Llama 3.1's score is on par with GPT-4 and better than other models, and it has very strong capabilities in long-text understanding.
- Tool use: Llama 3.1 scores relatively high in the BFCL test, and is very capable in using tools and performing programming tasks.
- Special tests: In the NIH/Multi-needle test, Llama 3.1's score is close to full marks, and its highly specialized capabilities in specific domains are very prominent.
- Quantization optimization: To support large-scale inference, Llama 3.1's models are quantized from BF16 to FP8, effectively reducing computational resource requirements and enabling the model to run on a wider range of hardware.
Llama3.1's performance
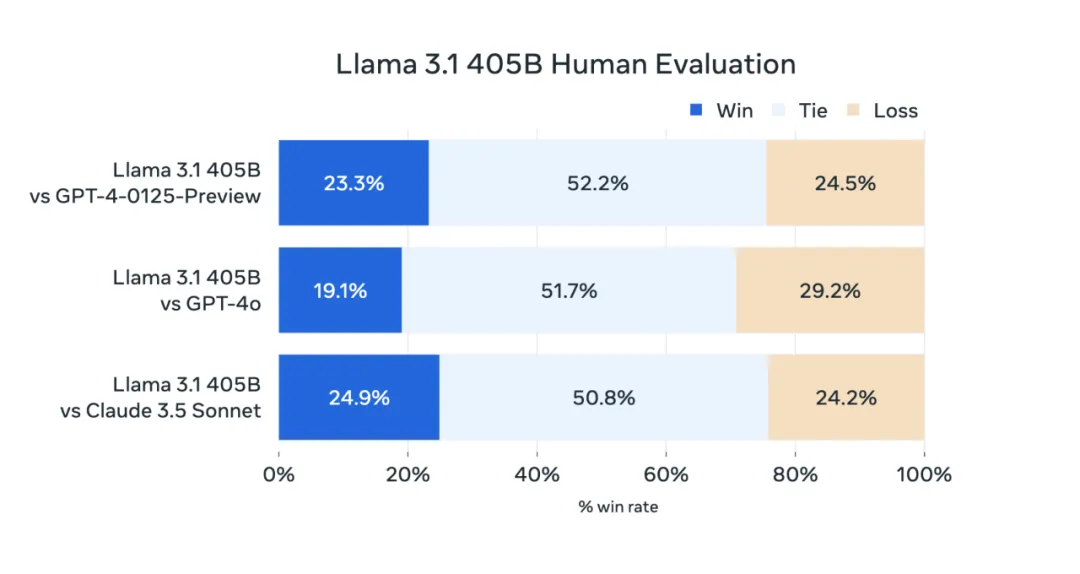
Meta evaluated performance on more than 150 benchmark datasets and compared the capabilities of Llama 3.1 with other models in real-world situations,The 405B model is competitive with leading foundation models across a range of tasks, including GPT-4, GPT-4o, and Claude 3.5 Sonnet.In addition, the smaller models are competitive with closed and open models with similar numbers of parameters.
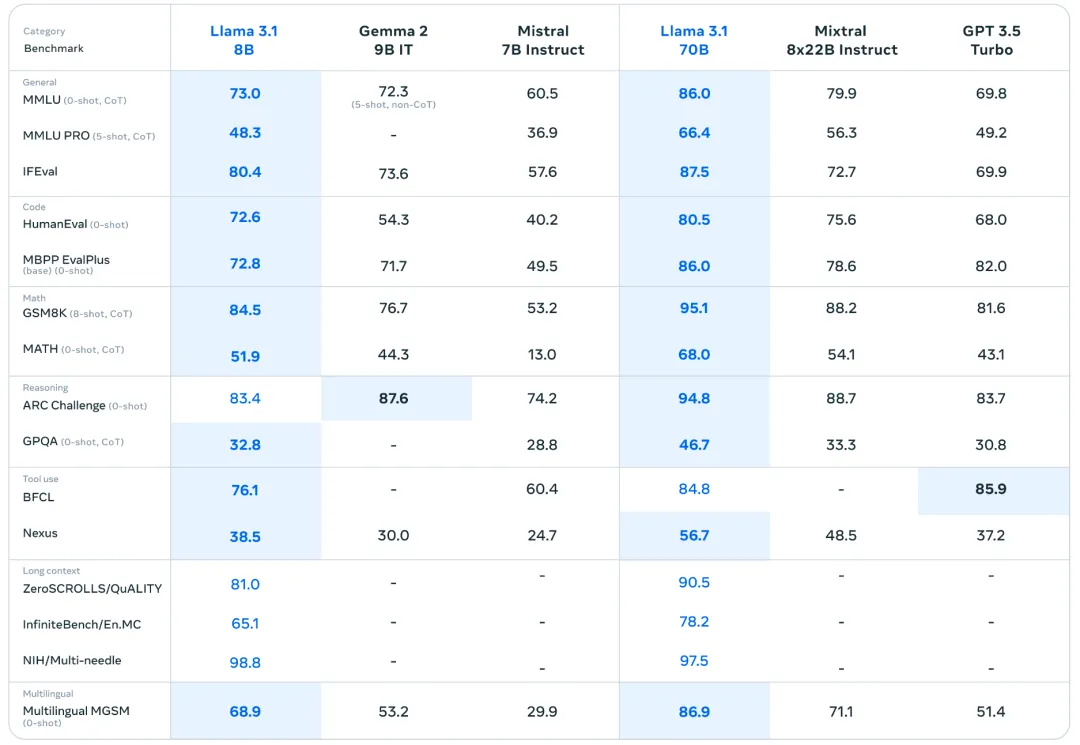
The 8B and 70B models made significant progress in benchmarks: Llama 3.1 performs excellently in benchmarks. The 8B model improved from 65 to 73 points in the MMLU test (an increase of 8 points), and the 70B model improved from 81 to 86 points (an increase of 5 points). In the MATH (mathematical problem solving) test, the 8B model's score increased significantly from 29 to 52 points (an increase of 23 points).
Llama 3.1 405B set new records in general tasks, knowledge reasoning, and reading comprehension. Especially on the MMLU and SQuAD sub-benchmarks, the improvements are the most obvious.The Llama 3.1 8B and 70B parameter versions have been slightly improved compared with Llama 3. Llama 3.1 405B is stronger than the pretrained model. On reasoning, code, mathematics, tool use, and multilingual benchmarks, it crushes the fine-tuned 8B and 70B versions.
Llama 3.1's project address
- Project official website:https://llama.meta.com/
- GitHub repository:https://github.com/meta-llama
- Hugging Face model library:https://huggingface.co/meta-llama