
What is Llama 3
Llama 3 is Meta's newly open-sourced next-generation large language model (LLM), including models with two parameter scales, 8B and 70B, marking another major advance in the field of open-source artificial intelligence. As the third-generation product in the Llama series, Llama 3 not only inherits the powerful capabilities of previous-generation models, but also provides a more efficient and reliable AI solution through a series of innovations and improvements. It aims to support a wide range of application scenarios through advanced natural language processing technology, including but not limited to programming, problem solving, translation, and dialogue generation.
Llama 3's series of models
Llama 3 currently offers two models, respectively versions with 8B (8 billion parameters) and 70B (70 billion parameters). These two models are designed to meet application needs at different levels, giving users flexibility and freedom of choice.
- Llama-3-8B: 8B parameter model, a relatively small but efficient model with 8 billion parameters. It is designed for application scenarios that require fast inference and fewer computing resources, while maintaining a high performance standard.
- Llama-3-70B: 70B parameter model, a larger-scale model with 70 billion parameters. It can handle more complex tasks and provide deeper language understanding and generation capabilities, making it suitable for applications with higher performance requirements.
Subsequently, Llama 3 will also release a model with a 400B parameter scale, which is currently still in training. Meta also stated that after completing Llama 3's training, it will also publish a detailed research paper.
Llama 3's official website entry points
- Official project homepage:https://llama.meta.com/llama3/
- GitHub model weights and code:https://github.com/meta-llama/llama3/
- Hugging Face model:https://huggingface.co/collections/meta-llama/meta-llama-3-66214712577ca38149ebb2b6
Where Llama 3 has improved
- Parameter scale: Llama 3 provides models with two parameter scales, 8B and 70B. Compared with Llama 2, the increase in the number of parameters enables the model to capture and learn more complex language patterns.
- Training dataset: Llama 3's training dataset is 7 times larger than Llama 2's, containing more than 15 trillion tokens, including 4 times the code data, which makes Llama 3 more outstanding in understanding and generating code.
- Model architecture: Llama 3 adopts a more efficient tokenizer and Grouped Query Attention (GQA) technology, improving the model's inference efficiency and ability to process long texts.
- Performance improvement: Through improved pretraining and post-training processes, Llama 3 has made progress in reducing false refusal rates, improving response alignment, and increasing the diversity of model responses.
- Safety: New trust and safety tools such as Llama Guard 2, as well as Code Shield and CyberSec Eval 2, have been introduced, enhancing the model's safety and reliability.
- Multilingual support: Llama 3 has added high-quality non-English data in more than 30 languages to its pretraining data, laying the foundation for future multilingual capabilities.
- Reasoning and code generation: Llama 3 has demonstrated greatly improved capabilities in areas such as reasoning, code generation, and instruction following, making it more precise and efficient in handling complex tasks.
Llama 3's performance evaluation
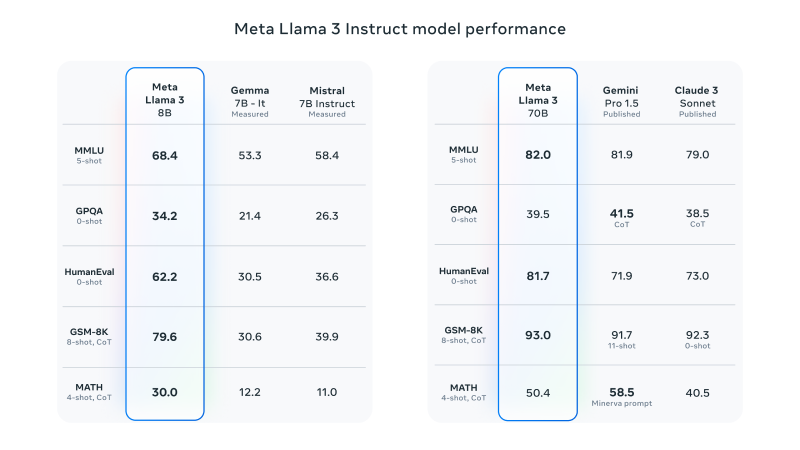
According to Meta's official blog, the instruction-tuned Llama 3 8B model outperforms models of the same parameter scale (Gemma 7B, Mistral 7B) on benchmark tests such as MMLU, GPQA, HumanEval, GSM-8K, and MATH, while the fine-tuned Llama 3 70B also outperforms models of the same scale, such as Gemini Pro 1.5 and Claude 3 Sonnet, on benchmarks including MLLU, HumanEval, and GSM-8K.
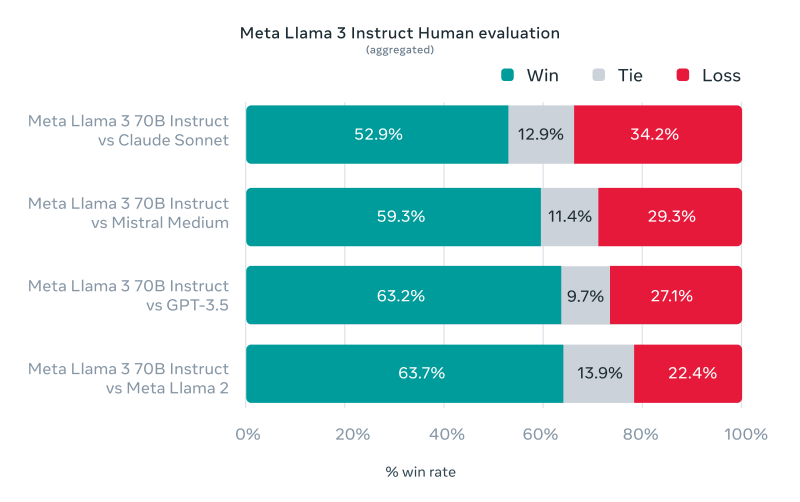
In addition, Meta also developed a new high-quality human evaluation set containing 1,800 prompts covering 12 key use cases: seeking advice, brainstorming, classification, closed question answering, coding, creative writing, extraction, inhabiting a character/persona, open question answering, reasoning, rewriting, and summarization. Through comparison with competing models such as Claude Sonnet, Mistral Medium, and GPT-3.5, human evaluators performed preference rankings based on this evaluation set, and the results show that Llama 3's performance in real-world scenarios is excellent, with a win rate of at least 52.9%.
Llama 3's technical architecture
- Decoder architecture: Llama 3 adopts a decoder-only architecture, which is a standard Transformer model architecture, mainly used for natural language generation tasks.
- Tokenizer and vocabulary size: Llama 3 uses a tokenizer with 128K tokens, which enables the model to encode language more efficiently, thereby significantly improving performance.
- Grouped Query Attention (GQA): To improve inference efficiency, Llama 3 adopts GQA technology in both the 8B and 70B models. This technology reduces the amount of computation by grouping queries in the attention mechanism while maintaining model performance.
- Long sequence processing: Llama 3 supports sequences of up to 8,192 tokens, using masking technology to ensure that self-attention does not cross document boundaries, which is especially important for processing long texts.
- Pre-training dataset: Llama 3 was pre-trained on more than 15TB of tokens. This dataset is not only huge in scale but also high in quality, providing the model with rich linguistic information.
- Multilingual data: To support multilingual capabilities, Llama 3's pre-training dataset contains more than 5% high-quality non-English data, covering more than 30 languages.
- Data filtering and quality control: The Llama 3 development team developed a series of data filtering pipelines, including heuristic filters, NSFW (not safe for work) filters, semantic deduplication methods, and text classifiers, to ensure the high quality of the training data.
- Scalability and parallelization: Llama 3's training process adopts data parallelism, model parallelism, and pipeline parallelism. The application of these technologies enables the model to be trained efficiently on a large number of GPUs.
- Instruction Fine-Tuning: On the basis of the pre-trained model, Llama 3 further improves the model's performance on specific tasks, such as dialogue and programming tasks, through instruction fine-tuning.
How to use Llama 3
Developers
Meta has open-sourced its Llama 3 model on GitHub, Hugging Face, and Replicate. Developers can use tools such as torchtune to customize and fine-tune Llama 3 to adapt to specific use cases and needs. Interested developers can check the officialgetting started guideand go to download and deploy it.
- Official model download:https://llama.meta.com/llama-downloads
- GitHub address:https://github.com/meta-llama/llama3/
- Hugging Face address:https://huggingface.co/meta-llama
- Replicate address:https://replicate.com/meta
Regular users
Regular users who are not tech-savvy and want to try Llama 3 can use it in the following ways:
- Visit the latestMeta AIchat assistant launched by Meta to try it out (Note: Meta.AI is region-locked and is only available in some countries)
- Visit Chat with Llama provided by Replicate to try it outhttps://llama3.replicate.dev/
- Use Hugging Chat (https://huggingface.co/chat/), and you can manually switch the model to Llama 3