
What is Meissonic
Meissonic is a text-to-image synthesis model launched through collaboration between Alibaba Group, Skywork AI, and multiple universities. Based on masked image modeling technology, it combines multimodal and unimodal Transformer layers, an advanced positional encoding strategy, and optimized sampling conditions to improve the efficiency and performance of image generation. The model uses 1B parameters and relies on high-quality training data, micro-conditioning, and feature compression layers to generate high-quality, high-resolution images, with performance comparable to large diffusion models. It performs excellently in multiple benchmark tests and is easy to run on ordinary computers without additional optimization, providing new possibilities for mobile text-to-image generation.
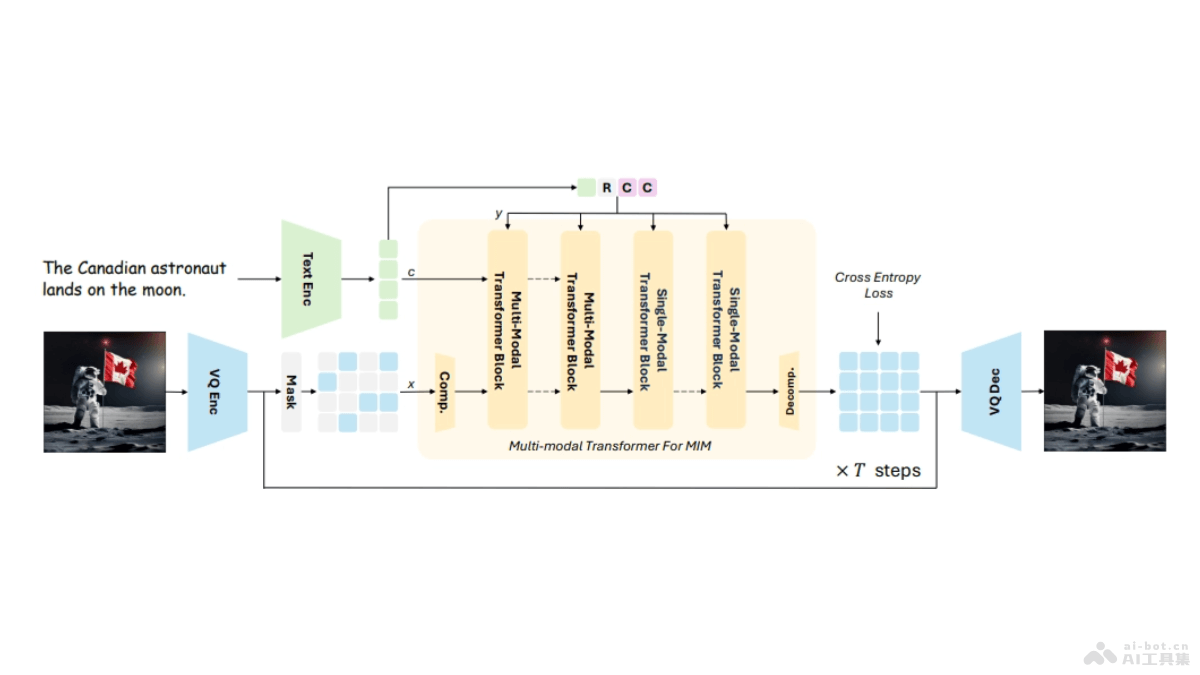
Main features of Meissonic
- High-resolution image generation: Meissonic can generate high-resolution images up to 1024x1024 pixels, meeting users' needs for detail and clarity.
- Text-to-image synthesis: Users input text prompts, and Meissonic generates images matching the prompts, achieving conversion from text descriptions to visual content.
- Zero-shot image editing: Meissonic can perform image editing without training for specific editing tasks, such as background changes, style transfer, object addition or removal, etc.
- Stylized image generation: Meissonic can generate images with specific artistic styles or themes, such as cartoon, realistic, abstract, etc.
- Efficient performance: On resource-constrained devices, Meissonic can run efficiently, thanks to its optimized model architecture and training strategy.
Technical principles of Meissonic
- Masked Generative Transformer (MIM): Meissonic adopts a non-autoregressive image generation method, randomly masking part of the image and predicting the masked part to reconstruct the complete image.
- Multimodal and unimodal Transformer layers: Combining multimodal and unimodal Transformer layers improves the model's understanding of the interaction between text and images, enhancing training efficiency and performance.
- Rotary Position Embedding (RoPE): RoPE is used to encode the positional information of queries and keys, helping the model maintain details and contextual associations when processing high-resolution images.
- Dynamic masking rate as a sampling condition: Adjusting the masking rate controls the sampling conditions during the generation process, allowing the model to adapt to different generation stages and improve image details and overall quality.
- Feature compression layer: To efficiently generate high-resolution images, Meissonic integrates a feature compression layer, which helps process a large number of discrete tokens while maintaining computational efficiency.
Meissonic project addresses
- GitHub repository:https://github.com/viiika/Meissonic
- HuggingFace model library:https://huggingface.co/MeissonFlow/Meissonic
- arXiv technical paper:https://arxiv.org/pdf/2410.08261
- Online experience Demo:https://huggingface.co/spaces/MeissonFlow/meissonic
Application scenarios of Meissonic
- Artistic creation: Artists and designers generate unique artworks or design sketches, quickly turning ideas into visual content.
- Media and entertainment: In film, game, and animation production, Meissonic is used in the creation of concept art, generating preliminary visual representations of scenes and characters.
- Advertising and marketing: Marketers quickly generate attractive advertising images and social media posts, improving the appeal of promotional materials.
- Education: In the field of education, help students and teachers create teaching materials, such as recreations of historical scenes or visualizations of scientific concepts.
- E-commerce: Online retailers create visual displays of products, for example, showing how clothing looks in different environments or on different models.