
What is MatAnyone
MatAnyone is an advanced framework introduced by the S-Lab at Nanyang Technological University and SenseTime for portrait video matting against complex backgrounds, focusing on target-specified video matting tasks. MatAnyone is based on a consistent memory propagation module and region-adaptive memory fusion technology to ensure semantic stability of core regions and the fineness of boundary details in video sequences. MatAnyone introduces a new training strategy that directly supervises the matting head with large-scale segmentation data, significantly improving the model's stability and generalization ability in real-world scenarios. MatAnyone is equipped with the high-quality, diverse training dataset VM800 and the more challenging test dataset YoutubeMatte, providing a solid foundation for model training and evaluation.
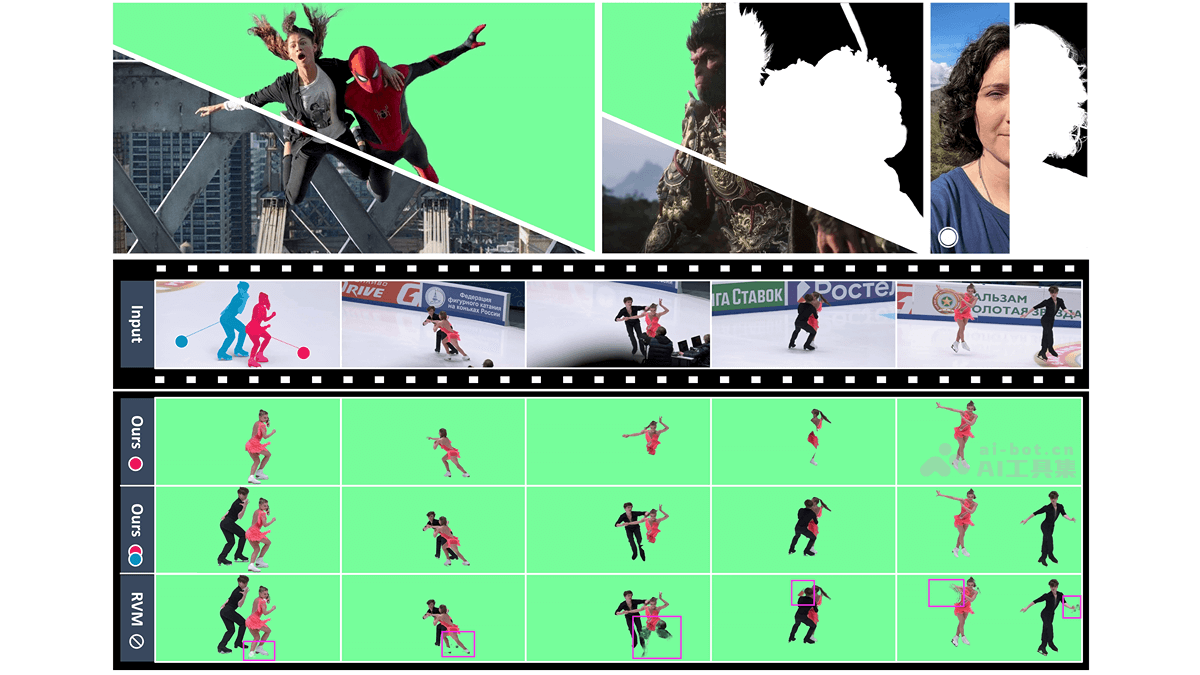
Main Features of MatAnyone
- Stable Target Tracking: Stably tracks the target object throughout the entire video, maintaining the integrity of the target in complex or blurred backgrounds.
- Fine Boundary Detail Extraction: Supports the generation of high-quality alpha mattes, especially performing excellently in boundary regions (such as hair, edges, etc.), providing image-level detail precision.
- Adapts to Multiple Video Types: MatAnyone can handle different types of videos, including movies, games, smartphone videos, etc., adapting to multiple frame sizes and media formats.
- Enhanced Interactivity: Users can specify the target segmentation mask in the first frame to guide the matting process for the entire video, achieving more precise interactive video editing.
Technical Principles of MatAnyone
- Consistent Memory Propagation:
- Memory Fusion: The CMP module adaptively fuses information from the previous frame based on the estimated alpha value change between the current frame and the previous frame. For 'large change' regions (usually located at boundaries), more reliance is placed on the information of the current frame; for 'small change' regions (usually located in core areas), the memory of the previous frame is retained.
- Region Adaptation: Based on a lightweight boundary region prediction module, it estimates the change probability of each query token, achieving region-adaptive memory fusion and significantly improving the semantic stability of core regions and the detail precision of boundary regions.
- Core Region Supervision:
- Direct Supervision with Segmentation Data: To overcome the scarcity of real video matting data, MatAnyone directly supervises the matting head with large-scale real segmentation data. Based on using pixel-level loss (Lcore) in core regions and an improved DDC loss (Lboundary) in boundary regions, it ensures semantic stability and detail precision.
- Improved DDC Loss: Based on adjusting the calculation method of the DDC loss to make it more suitable for video matting tasks, avoiding the jagged and staircase-like edges produced by the traditional DDC loss in boundary regions.
- New Datasets and Training Strategy:
- High-Quality Training Dataset: Introduces a new training dataset VM800, which is twice the size of the existing dataset VideoMatte240K and has higher quality in core and boundary regions, significantly improving the model's training effectiveness.
- Multi-Stage Training: Adopts a multi-stage training strategy, first initializing the model on video matting data, supervising core regions based on segmentation data, and finally further optimizing boundary details with image matting data.
- Network Architecture:
- Encoder: Uses ResNet-50 as the encoder to extract features and generate queries and keys.
- Object Transformer: Based on the Object Transformer module, it groups pixel-level memory by object semantics, reducing the noise caused by low-level pixel matching.
- Decoder: The decoder generates high-precision alpha masks based on multi-level upsampling and skip connections.
- Value Encoder: Encodes the predicted alpha mask and image features into values, which are used to update the memory bank.
MatAnyone's project address
- Project Website:https://pq-yang.github.io/projects/MatAnyone/
- GitHub Repository:https://github.com/pq-yang/MatAnyone
- arXiv Technical Paper:https://arxiv.org/pdf/2501.14677
MatAnyone's application scenarios
- Film and Television Post-Production: Used for background replacement and visual effects compositing, it precisely extracts actors from the original background and replaces it with a virtual or visual effects background, enhancing the visual effect and creative space of the footage.
- Video Conferencing and Live Streaming: In video conferencing and live streaming, it separates people from complex backgrounds in real time and replaces them with a virtual background or blurred background, enhancing privacy protection and visual effects.
- Advertising and Marketing: In advertising video production, it extracts products or people from the shooting background and replaces it with a more attractive background, enhancing the visual impact and appeal of the advertisement.
- Game Development: Used in the production of video content in games, such as character animations, cutscenes, etc., it precisely extracts characters from the shooting background and replaces it with game scenes, enhancing the game's sense of immersion.
- Virtual Reality and Augmented Reality: In VR and AR applications, it extracts users or objects from the real scene and integrates them into the virtual environment, enhancing the user experience and interaction effects.