
What is MarDini
MarDini is a novel video diffusion model that combines the advantages of Masked Autoregressive (MAR) and Diffusion Models (DM), used for large-scale video generation. The model can handle any number and position of masked frames, supporting various tasks such as video interpolation, image-to-video generation, and video extension. MarDini allocates most of its computational resources to a low-resolution planning model, enabling large-scale application of spatial-temporal attention mechanisms, improving the efficiency and flexibility of video generation. MarDini can be trained from scratch on unlabeled data without relying on image generation pretraining, demonstrating excellent scalability and efficiency.
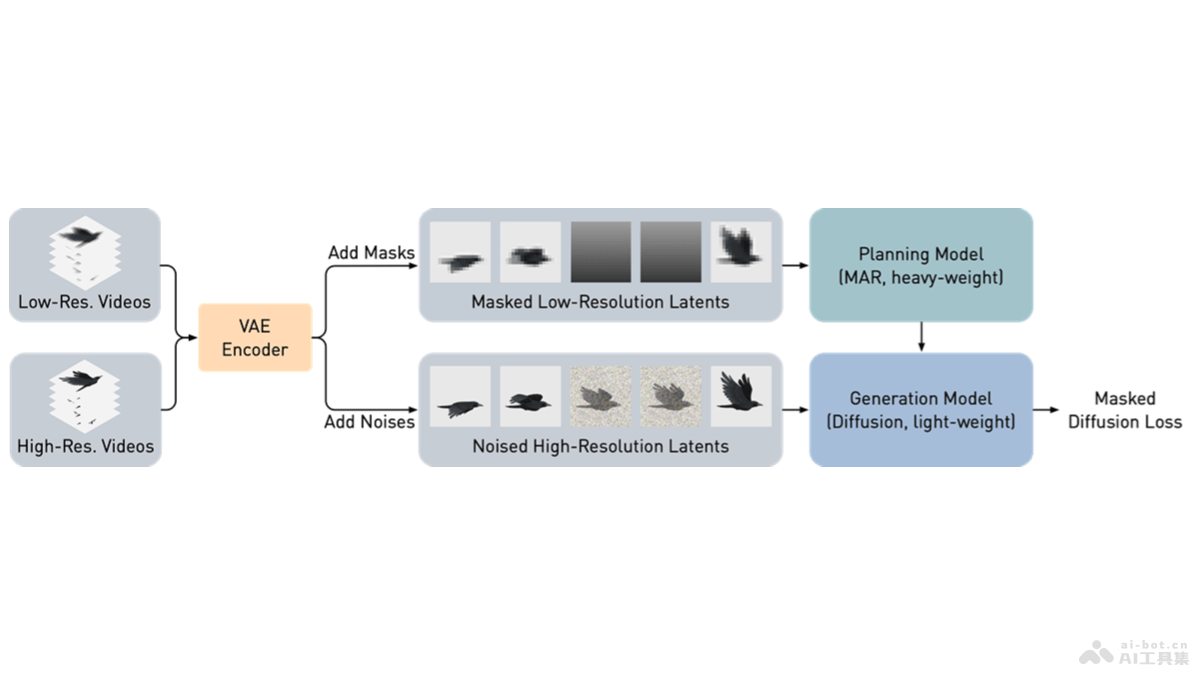
MarDini's Main Features
- Video Interpolation: Generates intermediate frames between two given frames, allowing smooth video transitions.
- Image-to-Video Generation: Starting from a single image, generates continuous video content.
- Video Extension: Adds new frames to an existing video, extending the video length.
- Slow-Motion Video Generation: Based on autoregressive inference, generates additional frames beyond those defined during training, creating slow-motion effect videos.
- Zero-Shot 3D View Synthesis: Even without 3D data training, can generate new viewpoint images with 3D consistency.
MarDini's Technical Principles
- Combination of Masked Autoregressive (MAR) and Diffusion Models (DM): MarDini uses MAR to handle long-term dependencies in time series, while DM focuses on generating spatial details.
- Asymmetric Network Design: MAR operates at low resolution with more parameters, while DM operates at high resolution with fewer parameters. This allows the model to handle more computational tasks at the low-resolution stage and focus on detail generation at the high-resolution stage.
- End-to-End Training: Based on masked frame-level diffusion loss, MarDini is trained end-to-end from unlabeled video data.
- Flexible Masking Strategy: MarDini changes the number and position of masked frames according to different task requirements, flexibly adapting to different video generation tasks.
- Progressive Training Strategy: The model gradually adjusts the masking ratio and the difficulty of training tasks, smoothly transitioning from video interpolation to full video generation.
MarDini's Project Links
- Project Website:mardini-vidgen.github.io
- arXiv Technical Paper:https://arxiv.org/pdf/2410.20280v1
MarDini's Application Scenarios
- Entertainment and Social Media: MarDini is used to generate short video content shared on social media, such as automatically generated dance videos, special effect videos, or user-defined short story clips.
- Film and Video Production: In film post-production, MarDini generates or enhances special effect scenes, or is used to create certain shots in movie trailers.
- Game Development: In game development, it generates dynamic background videos within games or serves as a prototyping tool for game character animations.
- Virtual Reality (VR) and Augmented Reality (AR): MarDini is used to generate dynamic environments and scenes in VR or AR applications, enhancing user immersion.
- Advertising and Marketing: MarDini is used to create attractive advertising videos, capturing potential customers' attention based on dynamic content.