
What is MagicPose
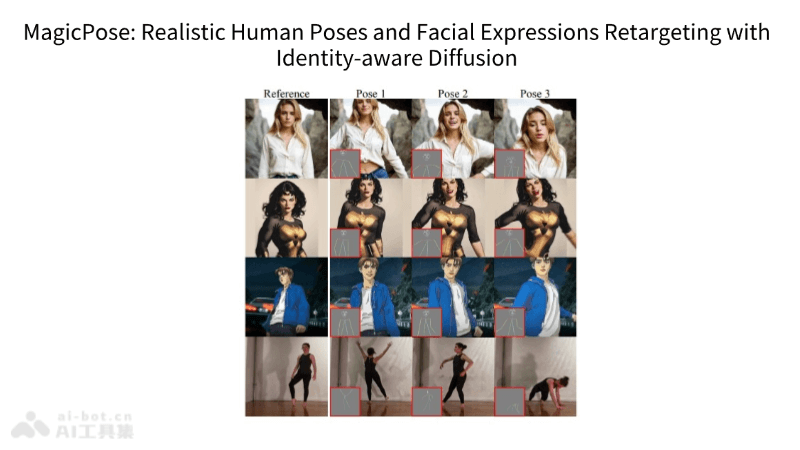
MagicPose is an AI video generation model jointly developed by the University of Southern California and ByteDance. Without any fine-tuning, it directly generates realistic videos of human motion and facial expressions. Through a novel two-stage training strategy, MagicPose separates human motion and appearance features, achieving precise transfer of motion and expressions across different identities. Another major advantage of MagicPose is its ease of use; it can be used as a plug-in for text-to-image models such as Stable Diffusion, and it demonstrates good generalization ability in various complex scenarios.
MagicPose's features
- Realistic video generation: It can generate realistic human videos with vivid motion and facial expressions.
- No fine-tuning required: MagicPose can directly generate highly consistent videos on in-the-wild data without fine-tuning for specific data.
- Appearance consistency: When generating videos, it can maintain the person's appearance features, such as facial features, skin tone, and clothing style.
- Motion and expression transfer: It can transfer one person's motion and expressions to another person while preserving the target person's identity information.
MagicPose's technical principles
- Diffusion-based model: MagicPose adopts a diffusion-based model that can handle the transfer of 2D human motion and facial expressions.
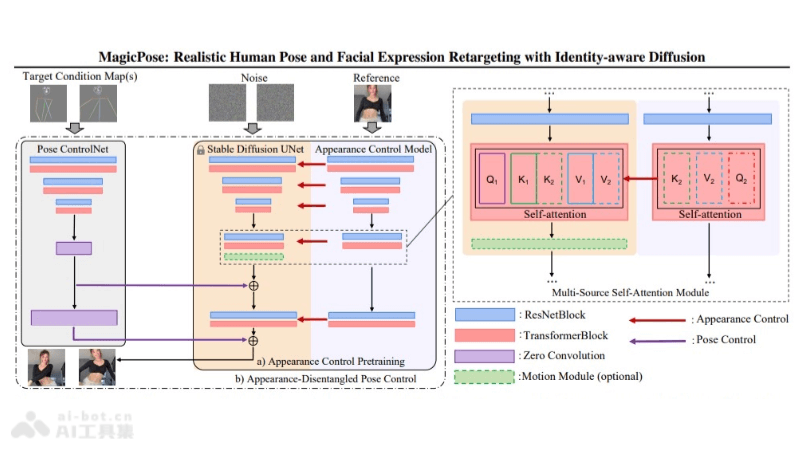
- Two-stage training strategy: It includes two stages. The first stage is pre-training the appearance control block, and the second stage is fine-tuning the appearance-pose-joint control block.
- Appearance control model: MagicPose uses an appearance control model to separate human motion and appearance features, such as facial expressions, skin tone, and clothing.
- Multi-source self-attention module: In the appearance control pre-training stage, the appearance control model and its multi-source self-attention module are trained to maintain consistent appearance under different poses.
- Appearance disentangled pose control: In the second stage, the appearance control model and pose control network are jointly fine-tuned to achieve precise control of appearance and motion.
- Freezing training modules: During training, once certain modules have finished training, their weights are frozen to maintain stability.
- AnimateDiff initialization: AnimateDiff is used to initialize the motion module and perform fine-tuning to generate realistic human motion.
- Generalization ability: After training, MagicPose can generalize to unseen human identities and complex motion sequences without additional fine-tuning.
MagicPose's project address
-
GitHubRepository:https://github.com/Boese0601/MagicDance
-
arXivTechnical paper:https://arxiv.org/pdf/2311.12052
MagicPose's application scenarios
- Virtual character production: MagicPose can be used to generate realistic virtual character motions and expressions, improving production efficiency and reducing costs.
- Animation production: Animators can use MagicPose to quickly generate animated characters' motions and expressions, accelerating the animation creation process.
- Social media content creation: Social media users can use MagicPose to generate personalized dynamic expressions or motions for social media sharing.
- Virtual reality and augmented reality: In VR and AR applications, MagicPose can provide realistic movements and expressions for virtual characters, enhancing the user experience.
- Education and training: MagicPose can be used to simulate human movements, such as human anatomy demonstrations in medical education or standard movement demonstrations in sports training.