
What is Loong
Loong is a new long video generation model jointly launched by the University of Hong Kong and ByteDance. It can generate minute-level long videos with consistent appearance, rich dynamics, and natural scene transitions. The model is based on an autoregressive large language model (LLM), integrating text and video information into a unified sequence. It uses a progressive short-to-long training scheme and a loss reweighting strategy to overcome the challenges in long video training. Loong's design supports the model in learning to generate videos from text prompts during training and extends to generating videos beyond the training length. Loong's research includes inference strategies such as video token re-encoding and sampling strategies to reduce error accumulation during inference.
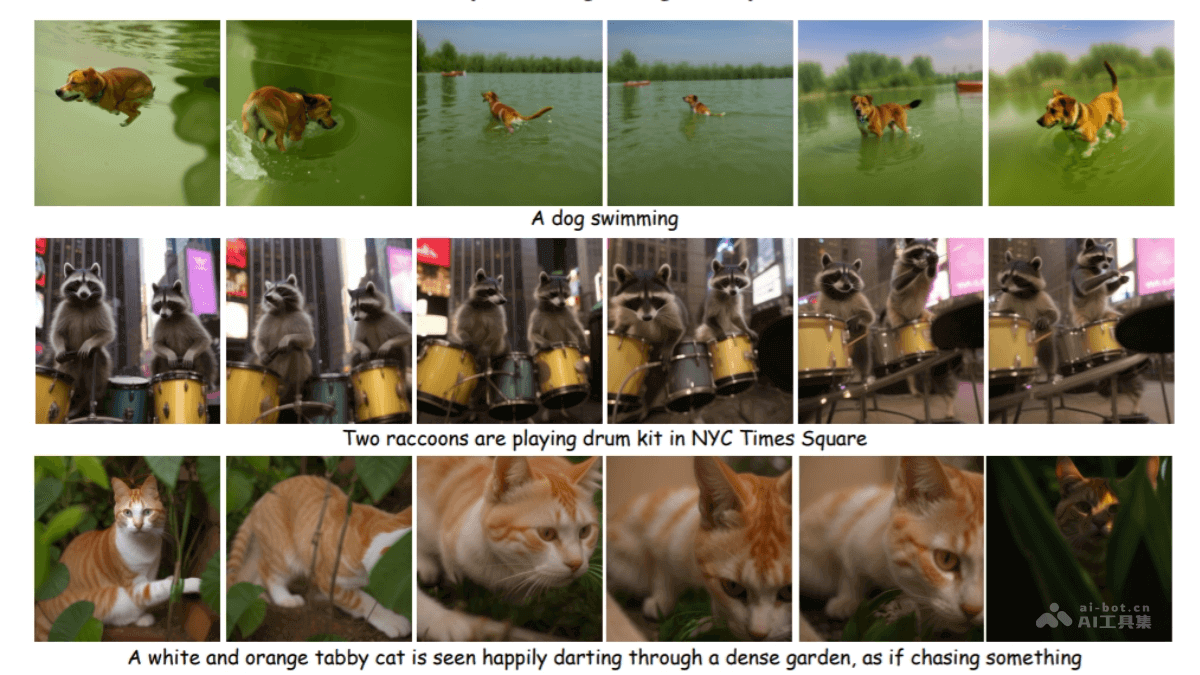
Loong's main features
- Long video generation: Generate video content up to one minute or longer.
- Text-to-video conversion: Generate video content that matches a given text prompt.
- Content coherence: Ensure that the generated video has a high degree of coherence in appearance, dynamic changes, and scene transitions.
- Dynamic richness: Capture and express complex dynamics and action changes in the video.
- Natural scene transitions: Achieve smooth transitions between different scenes in the video and maintain visual coherence.
Loong's technical principles
- Unified sequence modeling: Loong models text tokens and video tokens as a unified sequence, allowing an autoregressive large language model (LLM) to predict video tokens based on text prompts.
- Progressive short-to-long training: Based on a phased training strategy, the length of training videos is gradually increased, enabling the model to learn and generate more complex and more coherent video content.
- Loss reweighting: To address the loss imbalance problem in long video training, the loss of early frames is weighted to strengthen the model's learning of early frames.
- Video token re-encoding: During video inference, based on decoding the predicted video tokens into video frames in pixel space, re-encode them to maintain the coherence and consistency of the video content.
- Sampling strategy:Based on the Top-k sampling strategy, select from the most likely tokens to reduce the impact of potential errors on subsequent token generation and alleviate the problem of error accumulation.
Loong's project address
- Project official website:epiphqny.github.io/Loong-video
- arXiv technical paper:https://arxiv.org/pdf/2410.02757v1
Loong's application scenarios
- Entertainment and social media: Users generate personalized long video content and share it on social media platforms, such as music videos, travel logs, interesting stories, etc.
- Film and video production: In the preliminary creative stage of movie trailers, special effects production, or long video content, Loong quickly generates video sketches to help directors and producers explore different storylines and visual effects.
- Advertising and marketing: Enterprises generate attractive advertising videos to display products or services in a more vivid way, improving the appeal and memorability of advertisements.
- Education and training: In the field of education, L creates educational content, such as historical reenactments and scientific experiment simulations, providing a more intuitive and interactive learning experience.
- News and reporting: News organizations can quickly generate video summaries of news stories, improving the efficiency and appeal of reporting.