
What is LongReward
LongReward is a method jointly launched by Tsinghua University, the Chinese Academy of Sciences, and Zhipu AI to improve the performance of long-context large language models (LLMs) based on AI feedback. LongReward scores model responses across four dimensions: helpfulness, logicality, faithfulness, and completeness, provides reward signals, and optimizes the model through reinforcement learning, making the model more accurate and consistent when processing long texts and better able to follow instructions. It improves the model's long-text processing capability and enhances the efficiency of following brief instructions.
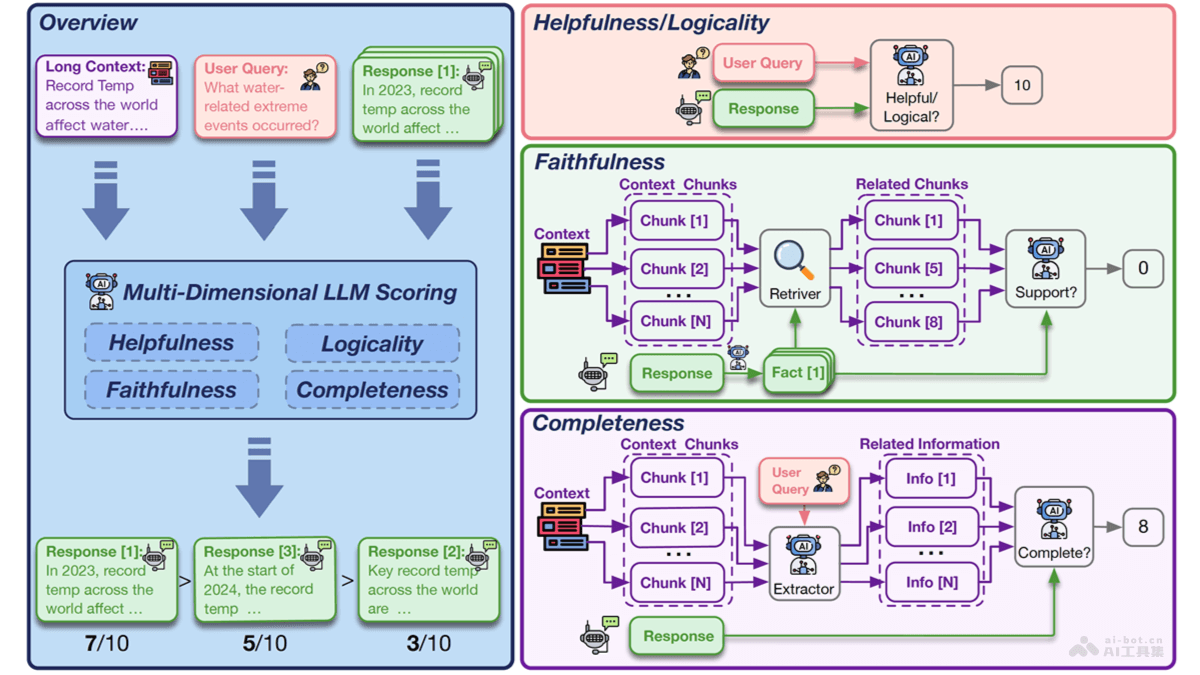
Main features of LongReward
- Multi-dimensional scoring: Scores the responses of long-context models across four dimensions: helpfulness, logicality, faithfulness, and completeness.
- Reward signal provision: Uses an off-the-shelf large language model (LLM) as a scoring tool to provide reward signals for the responses of long-context models, and the signals are used in reinforcement learning (RL).
- Reinforcement learning integration: Combines the offline reinforcement learning algorithm DPO (Direct Preference Optimization), based on which the optimized model outputs meet preference requirements and improve model performance.
- Performance improvement: Significantly improves the model's performance on long-text tasks, including better understanding and use of contextual information, and reduces hallucination phenomena.
- Enhanced instruction-following capability: Enhances the model's ability to follow brief instructions and improves the model's practicality and flexibility.
Technical principles of LongReward
- Multi-dimensional evaluation:
- Helpfulness: Evaluates whether the model's response is relevant to the user's query, whether it provides useful information, and whether it meets the user's needs.
- Logicality: Checks the logical consistency of the model's response, including consistency of viewpoints and correctness of reasoning.
- Faithfulness: Measures whether the factual information in the model's response is consistent with the context, ensuring the authenticity of the information.
- Completeness: Evaluates whether the model's response covers all key points related to the question in the context and provides sufficient information and details.
- Using off-the-shelf large language models (LLMs): Uses off-the-shelf high-performance LLMs as scoring tools to score the model's generated content.
- Few-shot learning and Chain-of-Thought (CoT): For helpfulness and logicality scoring, uses few-shot learning and CoT to let the LLM score directly based on the query and response content.
- Factual statement decomposition and retrieval: For faithfulness scoring, decomposes the model's response into factual statements, retrieves the most relevant parts of the context, and judges whether each statement is supported.
- Coarse-grained context decomposition: For completeness scoring, decomposes the context into coarse-grained chunks, extracts information relevant to the question, and then evaluates whether the model's response contains all important information.
Project address of LongReward
- GitHub repository:https://github.com/THUDM/LongReward
- HuggingFace model library:https://huggingface.co/datasets/THUDM/LongReward-10k
- arXiv technical paper:https://arxiv.org/pdf/2410.21252
Application scenarios of LongReward
- Long document understanding and question answering (QA): Used to evaluate and improve the model's question-answering performance when processing documents such as long articles, reports, or books.
- Text summarization: Helps the model better understand and summarize the main content of long articles or multi-document collections.
- Education and academic research: In academic research, LongReward is used to evaluate and improve the model's ability to process large amounts of literature and data, supporting research and learning.
- Legal and financial analysis: In the legal and financial fields, LongReward is used to analyze and understand large amounts of legal documents, contracts, or financial reports.
- Medical record analysis: In the medical field, LongReward assists models in understanding and analyzing patients' detailed medical records, supporting diagnosis and treatment decisions.