
What is LlamaV-o1
LlamaV-o1 is a new multimodal visual reasoning model proposed by institutions such as Mohamed bin Zayed University of Artificial Intelligence in the UAE, enhancing the step-by-step visual reasoning capabilities of large language models. It introduces the Visual Reasoning Chain benchmark VRC-Bench, containing over 4,000 reasoning steps, to comprehensively evaluate model reasoning capabilities; proposes a new evaluation metric to measure reasoning quality at single-step granularity; and adopts a multi-step curriculum learning method for training, with tasks organized in sequence to gradually master skills. Experiments show that its performance is superior to open-source models, and it performs excellently in comparisons with closed-source models, achieving a reasoning step score of 68.93, providing step-by-step explanations, and performing outstandingly in complex visual tasks.
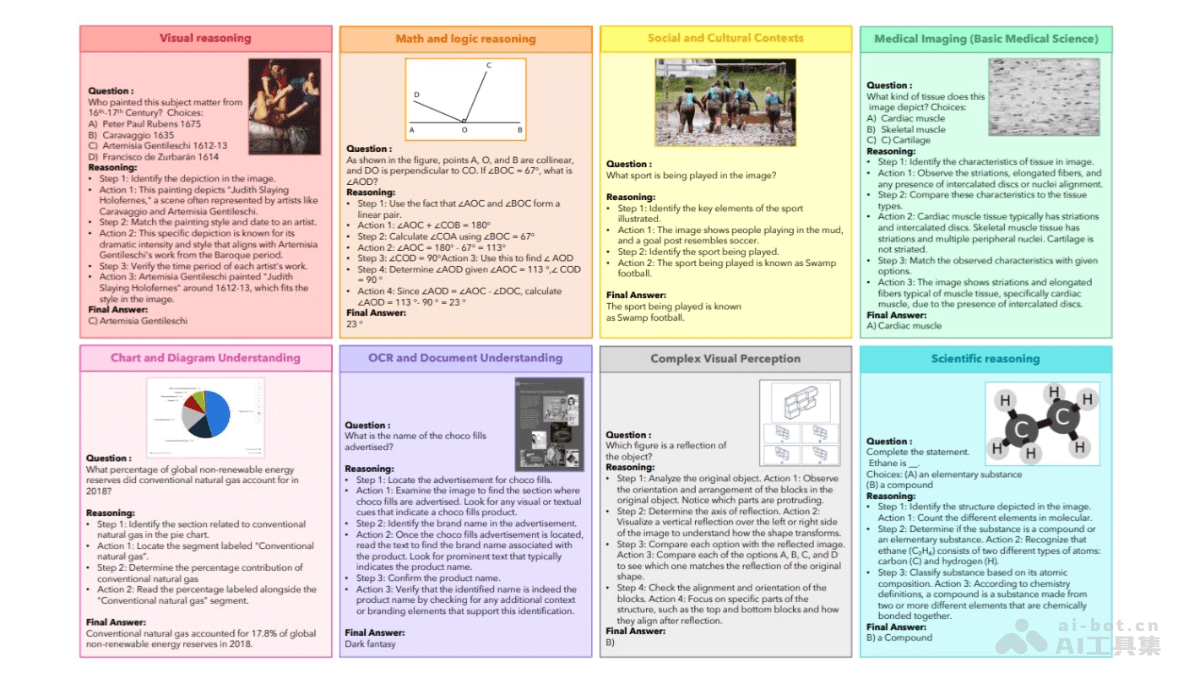
Main features of LlamaV-o1
- Multimodal visual reasoning: It can combine information from multiple modalities such as text, images, and videos to handle complex visual reasoning tasks, such as analyzing financial charts and medical images.
- Step-by-step reasoning and transparency: Through a structured training paradigm, it learns step by step and can demonstrate its problem-solving process step by step, allowing users to track each stage of its logic and providing a transparent reasoning process. It is especially suitable for applications where trust and interpretability are crucial, such as medical diagnosis and finance.
- Strong evaluation benchmark: The research team launched the VRC-Bench benchmark, specifically designed to evaluate multi-step reasoning tasks. It covers more than 1,000 tasks in 8 categories, including visual reasoning, medical imaging, and cultural background analysis, and contains more than 4,000 manually verified reasoning steps, enabling comprehensive evaluation of model reasoning capabilities.
- High performance: On the VRC-Bench benchmark, LlamaV-o1 achieves a reasoning score of 68.93, surpassing other open-source models such as LLava-CoT (66.21) and narrowing the gap with the proprietary model GPT-4o (score 71.8). Its reasoning speed is five times faster than similar products, and its average score across six multimodal benchmarks is 67.33%, demonstrating its ability to handle different reasoning tasks while maintaining logical coherence and transparency.
Technical principles of LlamaV-o1
- Curriculum learning method: LlamaV-o1 is trained using a multi-step curriculum learning method. Tasks are organized in sequence, starting from simpler tasks and gradually progressing to more complex tasks. The model can build foundational reasoning skills before tackling advanced challenges, promoting incremental skill acquisition and problem-solving.
- Beam search optimization: Combined with beam search technology, it improves the model's accuracy and efficiency by generating multiple reasoning paths in parallel and selecting the most logical path.
- Visual Reasoning Chain Benchmark (VRC-Bench): The research team introduced the VRC-Bench benchmark, specifically designed to evaluate multi-step reasoning tasks. The benchmark covers challenges in eight different categories, from complex visual perception to scientific reasoning, with more than 4,000 reasoning steps in total, and can comprehensively evaluate the model's ability to perform accurate and interpretable visual reasoning in multiple steps.
- New evaluation metric: A new metric was proposed to evaluate the quality of visual reasoning at single-step granularity, emphasizing correctness and logical coherence. Compared with traditional final task accuracy metrics, it can provide deeper insight into reasoning performance.
- Pretraining dataset: It is trained using the LLaVA-CoT-100k dataset optimized for reasoning tasks. The dataset contains a large number of reasoning steps and related annotations, helping the model learn a more accurate and coherent reasoning process.
Project address of LlamaV-o1
- Project Website:https://mbzuai-oryx.github.io/LlamaV-o1
- Github Repository:https://github.com/mbzuai-oryx/LlamaV-o1
- HuggingFace Model Library:https://huggingface.co/omkarthawakar/LlamaV-o1
- arXiv Technical Paper:https://arxiv.org/pdf/2501.06186
Application Scenarios of LlamaV-o1
- Medical Imaging Analysis: In medical imaging, LlamaV-o1 can analyze and diagnose medical images such as X-rays, CT scans, and MRI images. It can provide diagnostic results and explain in detail the logical steps leading to the conclusion.
- Financial Sector: LlamaV-o1 excels at interpreting complex financial charts and data, providing financial analysts with step-by-step breakdowns and actionable insights to help them better understand market trends, financial conditions, and more, and make wiser investment decisions.
- Education and Teaching: In educational software, LlamaV-o1 can be used to provide step-by-step problem-solving guidance based on visual materials, helping students understand complex scientific concepts, mathematical problems, and more, and promoting students' learning and understanding through step-by-step reasoning.
- Industrial Inspection: The model helps develop intelligent inspection systems by combining visual and language information to improve inspection efficiency and accuracy, and can be used to inspect product quality, equipment failures, and other aspects.