
What is Lingshu
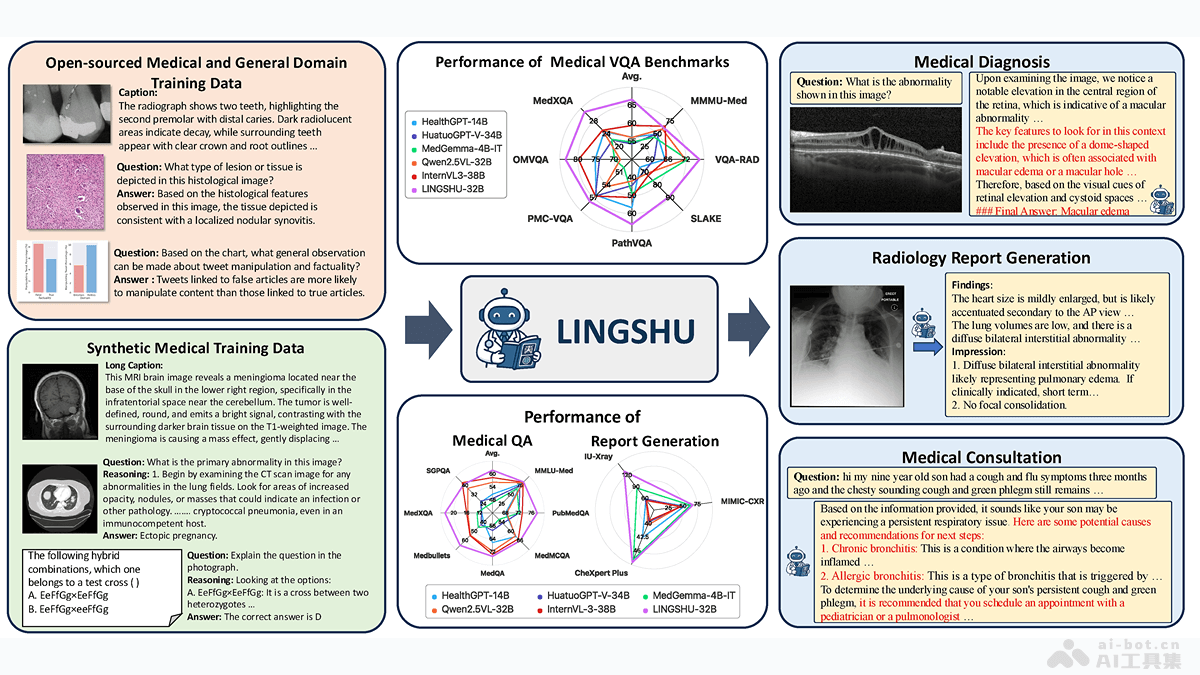
Lingshu is a multimodal large language model focused on the medical field, launched by Alibaba DAMO Academy. The model supports over 12 medical imaging modalities, including X-ray, CT scans, MRI, etc., and demonstrates excellent performance on tasks such as multimodal question answering, text question answering, and medical report generation. Lingshu is based on multi-stage training, gradually embedding medical professional knowledge, significantly improving reasoning and problem-solving capabilities in the medical field. Two parameter versions, 7B and 32B, have been released, among which the 32B version surpasses in multiple medical multimodal question answering tasksGPT-4.1and other proprietary models. The Lingshu project has launched the MedEvalKit evaluation framework, integrating mainstream medical benchmarks to promote standardized evaluation and development of medical AI models.
Lingshu's Main Features
- Multimodal Medical Question Answering: Supports visual question answering tasks involving multiple medical imaging modalities (such as X-ray, CT, MRI, etc.). Generates accurate answers based on input medical images and related questions.
- Medical Report Generation: Lingshu can generate high-quality medical reports, such as radiology reports, producing detailed 'Findings' and 'Impression' sections based on input medical images, providing valuable references for clinicians.
- Medical Knowledge Question Answering: Lingshu can answer text-only medical questions, covering a wide range of medical knowledge, providing accurate information for medical students, clinicians, and researchers.
- Medical Reasoning and Diagnostic Support: Lingshu possesses strong medical reasoning capabilities, performing complex reasoning and diagnostic support based on input medical images and text information.
- Medical Image Understanding and Annotation: Lingshu can understand and annotate key features in medical images, such as lesion location, type, and severity, and supports generating detailed image descriptions to help doctors better understand image content.
Lingshu's Technical Principles
- Data Preparation:
- Data Collection: Collects medical imaging data, medical text data, and general-domain data from multiple sources.
- Data Cleaning: Ensures data quality and relevance through image filtering, deduplication, and text cleaning.
- Data Synthesis: Generates high-quality medical captions, visual question answering (VQA) samples, and reasoning traces to enrich the training data.
- Model Architecture: Lingshu is based on theQwen2.5-VLmodel architecture and includes three key components: a large language model (LLM) that processes text input and generates text output, a vision encoder that extracts visual features from medical images, and a projector that maps visual features into the representation space of the language model.
- Multi-Stage Training:
- Medical Shallow Alignment: Fine-tunes with a small number of medical image-text pairs, enabling the model to accurately encode medical images and generate corresponding descriptions.
- Medical Deep Alignment: Introduces larger-scale, higher-quality, and semantically richer medical image-text pair datasets to further integrate medical knowledge.
- Medical Instruction Tuning: Optimizes the model based on large-scale medical instruction data to improve its ability to execute specific task instructions.
- Medical-Oriented Reinforcement Learning: Uses the reinforcement learning with verifiable rewards (RLVR) paradigm to enhance the model's medical reasoning capabilities.
- Evaluation Framework: Introduces the MedEvalKit evaluation framework, which integrates multiple multimodal and textual medical benchmarks and supports a variety of question formats, including multiple-choice questions, closed-ended questions, open-ended questions, and medical report generation. The framework provides standardized data preprocessing formats and post-processing protocols, as well as consistent model deployment and inference interfaces, supporting rapid integration and one-click evaluation.
Lingshu's project address
- Project official website:https://alibaba-damo-academy.github.io/lingshu/
- HuggingFace model repository:https://huggingface.co/collections/lingshu-medical-mllm/lingshu-mllms-6847974ca5b5df750f017dad
- arXiv technical paper:https://arxiv.org/pdf/2506.07044
Lingshu's application scenarios
- Medical image diagnosis: Handles visual question answering tasks across multiple medical imaging modalities, analyzes abnormalities in images and provides diagnostic suggestions, generates detailed image descriptions and annotates key features, assisting doctors in making accurate diagnoses.
- Medical report generation: Generates high-quality radiology reports and pathology reports based on medical images, covering the "Findings" and "Impression" sections, providing important reference for clinicians and improving the efficiency and quality of report writing.
- Medical knowledge question answering: Provides accurate medical knowledge, helping medical students, professionals, and clinicians obtain the information they need and make more informed decisions.
- Medical research: In medical research, assists in organizing and analyzing medical image and text data.
- Public health: Lingshu can process public health data, support epidemiological research, calculate attributable risk, etc.