
What Is Kyutai TTS
Kyutai TTS is a streamingtext-to-speech(TTS) technology launched by the French AI research institute Kyutai Labs. It is an innovative speech synthesis system that can convert text into natural and fluent speech in real time, starting to generate audio without waiting for the complete text input, with extremely low latency (only 220 milliseconds). It supports streaming text transmission and performs excellently in real-time interactive scenarios, such as intelligent customer service, real-time translation, and live streaming. It supports English and French, and features voice cloning, able to match a speaker's timbre and intonation through a 10-second audio sample. Kyutai TTS supports long-form text generation, breaking through the duration limits of traditional TTS systems, making it suitable for scenarios such as news broadcasting and audiobooks.
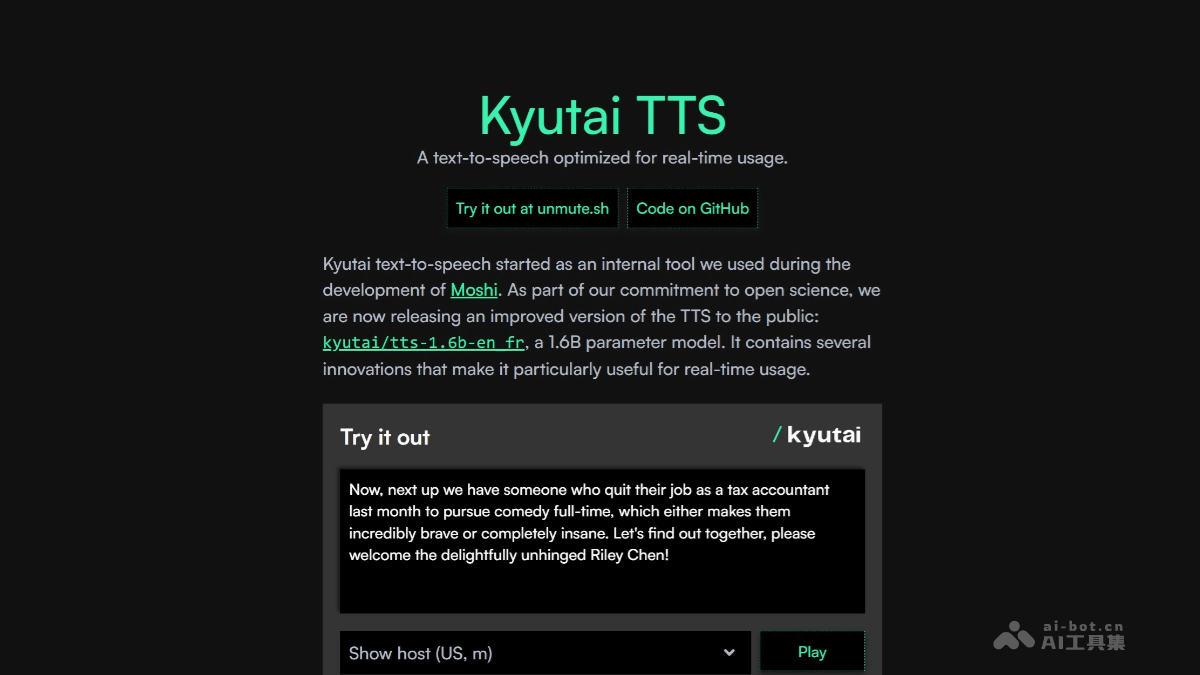
Main Features of Kyutai TTS
-
Streaming Text Transmission: Supports streaming text transmission, allowing audio generation to begin without complete text, suitable for real-time interactive scenarios such as intelligent customer service, real-time translation, and live streaming.
-
Low Latency: On a single NVIDIA L40S GPU, Kyutai TTS can process 32 requests simultaneously with a latency of only 350 milliseconds, quickly responding to the needs of a large number of users.
-
High-Fidelity Voice: Supports voice cloning through a 10-second audio sample, with generated speech being natural and fluent, achieving speaker similarity of 77.1% (English) and 78.7% (French), and word error rates (WER) of 2.82% and 3.29%, respectively.
-
Long-Form Text Generation: Breaks through the 30-second limit of traditional TTS systems, able to process long articles, suitable for scenarios such as news broadcasting and audiobooks.
-
Multilingual Support: Currently supports English and French.
Technical Principles of Kyutai TTS
-
Delayed Streams Modeling (DSM): DSM is the core architecture of Kyutai TTS, treating speech and text as two time-aligned data streams. The text stream is delayed by several time frames relative to the audio stream, enabling the model to "see a little into the future speech," improving the accuracy and naturalness of generated speech. During inference, the model advances by time steps without waiting for complete audio input, making streaming generation possible.
-
Audio Codec: The model uses a custom causal audio codec (such as Mimi) to encode speech into low-frame-rate discrete tokens, supporting real-time streaming processing. This enables the model to achieve efficient real-time generation while maintaining high-quality speech output.
-
High Concurrency and Low Latency: Kyutai TTS can process 32 requests simultaneously on a single NVIDIA L40S GPU, with a latency of only 350 milliseconds.
-
Voice Cloning and Personalization: The model supports voice cloning through a 10-second audio sample, able to match the pitch, intonation, tone, and recording quality of the original audio.
-
Word Timestamps: Each word in the speech generated by Kyutai TTS comes with precise timestamps, making real-time subtitle generation and interactive applications possible.
Kyutai TTS Project Address
- Project Official Website:https://kyutai.org/next/tts
Application Scenarios of Kyutai TTS
- Intelligent Customer Service: The low-latency feature of Kyutai TTS in intelligent customer service scenarios allows the system to instantly generate voice responses when users ask questions, without waiting for users to finish speaking, greatly improving interaction efficiency and user experience.
- Real-Time Translation: In scenarios such as cross-border business negotiations and international academic exchanges, Kyutai TTS can quickly convert translated text into speech, enabling seamless communication.
- Video Conferencing and Live Streaming: Kyutai TTS can provide real-time subtitle generation for video conferencing and live streaming. It can quickly and accurately generate synchronized subtitles, making it easier for viewers to better understand the content.
- Education: Kyutai TTS can provide high-quality text reading services for visually impaired people, helping them better access information. It can be used on online education platforms to provide students with vivid teaching content and enhance the learning experience.
- Media Production: Kyutai TTS can handle speech generation for long articles, making it suitable for scenarios such as news broadcasting and audiobook production.
- Voice Navigation: Kyutai TTS's high-concurrency processing capability can support scenarios such as in-car navigation and public transportation voice prompts, providing users with clear and timely voice announcements.