
What is KTransformers
KTransformers is an open-source project launched by the KVCache.AI team at Tsinghua University in collaboration with Qujing Technology. It optimizes the inference performance of large language models and lowers the hardware threshold. KTransformers is based on a GPU/CPU heterogeneous computing strategy and uses the sparsity of the MoE architecture to support running the full 671B versions of DeepSeek-R1 and V3 on a single graphics card with only 24GB of VRAM. The preprocessing speed reaches up to 286 tokens/s, and the inference generation speed reaches up to 14 tokens/s. The project uses technologies such as a compute-intensity-based offload strategy, high-performance operators, and CUDA Graph optimization to significantly improve inference speed.
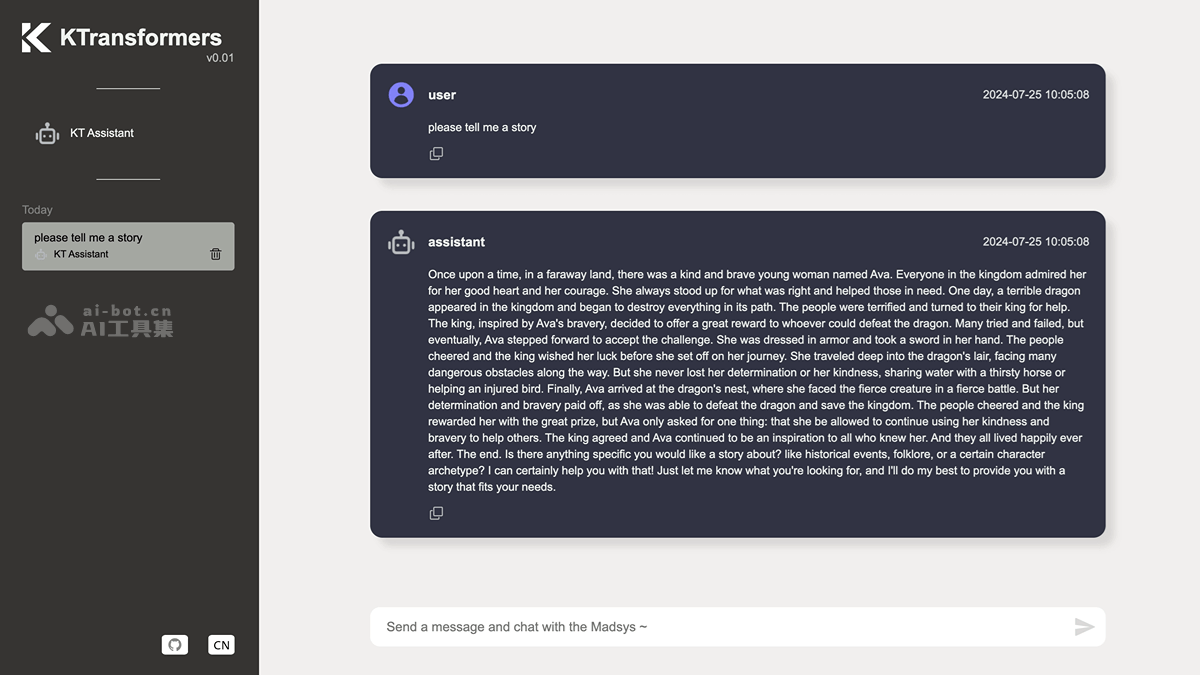
KTransformers' Main Features
- Supports local inference of ultra-large models: Supports running full-parameter large models such as DeepSeek-R1 with 671B parameters on a single graphics card with only 24GB of VRAM, breaking traditional hardware limitations.
- Improves inference speed: The preprocessing speed can reach up to 286 tokens/s, and the inference generation speed reaches 14 tokens/s.
- Compatible with multiple models and operators: Supports the DeepSeek series and other MoE architecture models, provides a flexible template injection framework, and supports users in switching quantization strategies and replacing kernels to adapt to different optimization needs.
- Lowers the hardware threshold: Greatly reduces the VRAM requirements of large models, allowing ordinary users and small to medium-sized teams to run hundred-billion-parameter models on consumer-grade hardware, enabling “home-based” deployment.
- Supports long-sequence tasks: Integrates the Intel AMX instruction set, enabling CPU prefill speeds of up to 286 tokens/s, 28 times faster than traditional solutions, shortening the processing time of long-sequence tasks from “minutes” to “seconds.”
KTransformers' Technical Principles
- MoE architecture: Offloads sparse MoE matrices to the CPU/DRAM for processing, while keeping the dense parts on the GPU, greatly reducing VRAM requirements.
- Offload strategy: Allocates tasks to the GPU and CPU according to computational intensity: tasks with high computational intensity (such as MLA operators) are preferentially assigned to the GPU, while tasks with low computational intensity are assigned to the CPU.
- High-performance operator optimization:
- CPU side: Uses llamafile as the CPU kernel, combined with optimizations such as multithreading, task scheduling, and load balancing to improve CPU inference efficiency.
- GPU side: Introduces the Marlin operator, specifically optimizing quantized matrix computation, achieving a 3.87x speedup compared with traditional libraries such as Torch.
- CUDA Graph optimization: Based on CUDA Graph, reduces Python call overhead and lowers CPU/GPU communication breakpoints, enabling efficient heterogeneous computing collaboration. Each decode requires only one complete CUDA Graph call, significantly improving inference performance.
- Quantization and storage optimization: Uses 4-bit quantization technology to further compress model storage requirements, requiring only 24GB of VRAM to run a 671B-parameter model. It also optimizes the KV cache size to reduce storage overhead.
- Template injection framework: Provides a YAML-based template injection framework that supports users in flexibly switching quantization strategies, kernel replacement, and other optimization methods to adapt to the needs of different scenarios.
KTransformers' Project Address
- GitHub repository:https://github.com/kvcache-ai/ktransformers
KTransformers' Application Scenarios
- Individual development and small to medium-sized teams: Run large models on consumer-grade hardware for development such as text generation and question-answering systems, reducing costs.
- Long-sequence tasks: Efficiently handle tasks such as long text processing and code analysis, reducing processing time from minutes to seconds.
- Enterprise Applications: Locally deploy large models for intelligent customer service, content recommendation, etc., saving on cloud service costs.
- Academic Research: Explore and optimize MoE architecture models on ordinary hardware to accelerate research progress.
- Education and Training: As a teaching tool, help students practice large model applications and understand optimization techniques.