
What is Kimi-k2 Thinking
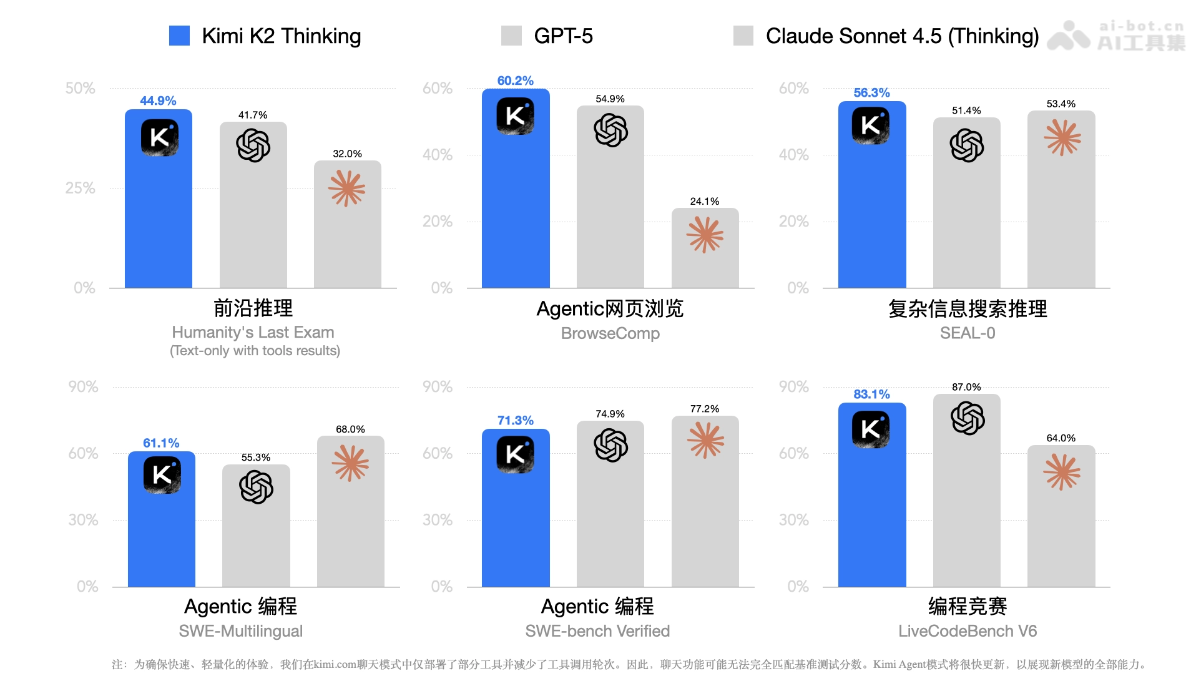
Kimi-k2 Thinking is an artificial intelligence model launched by Moonshot AI with general Agentic capabilities and deep reasoning abilities. The model possesses powerful multi-turn thinking and tool-calling capabilities, enabling it to autonomously complete complex tasks without human intervention, making it suitable for step-by-step reasoning and planning of complex tasks. In multiple benchmark tests such as "Humanity's Last Exam," "BrowseComp" (autonomous web browsing capability), and "SEAL-0" (complex information gathering and reasoning), Kimi K2 Thinking's performance reaches the industry's top level (SOTA), while also achieving comprehensive upgrades in Agentic search, Agentic programming, writing, and general reasoning capabilities. Kimi-k2 Thinking includes a high-speed version, Kimi-k2 Thinking-turbo, with inference speeds of up to 100 tokens/s, suitable for scenarios with high efficiency requirements.
The Kimi K2 Thinking model is now available in kimi.com and the latest version of Kimi APPregular conversation mode. Kimi's Agent mode will soon be upgraded to the Kimi K2 Thinking model, providing users with more powerful multi-turn thinking and tool-calling capabilities. The Kimi K2 Thinking API is now available on the Kimi Open Platform, and developers can access it through that platform.
Main features of Kimi-k2 Thinking
- Deep reasoning: Capable of complex logical reasoning and multi-step thinking, solving problems step by step, suitable for tasks requiring in-depth analysis.
-
Autonomous tool calling: Without human intervention, it can autonomously call tools (such as search, programming, web browsing) to solve complex tasks.
- Long-horizon planning and multi-turn interaction: Supports up to 300 rounds of tool calling and continuous, stable multi-turn thinking, suitable for solving complex problems.
-
Long context processing: Supports context lengths of up to 256k, capable of handling complex long-text tasks such as lengthy analysis and multi-step task planning.
-
Visualization of the reasoning process: Through the
reasoning_contentfield, it displays the reasoning process, helping users understand the model's thinking logic and enhancing interpretability. -
Efficient inference: Provides a high-speed version (Kimi-k2 Thinking-turbo), with inference speeds of up to 100 tokens/s, suitable for scenarios with high efficiency requirements.
-
Cost optimization: Strikes a balance between inference efficiency and cost, suitable for complex task processing requiring high cost-effectiveness.
Performance of Kimi-k2 Thinking
-
Reasoning ability: In "Humanity's Last Exam," covering more than 100 professional fields, Kimi K2 Thinking achieved a SOTA (State-of-the-Art) score of 44.9%, demonstrating powerful reasoning and problem-solving capabilities.
-
Autonomous search and browsing ability: In the BrowseComp benchmark released by OpenAI, Kimi K2 Thinking became the new SOTA model with a score of 60.2%, far exceeding the human average of 29.2%, demonstrating extremely strong information retrieval and research capabilities.
-
Complex information gathering and reasoning: In the SEAL-0 benchmark, Kimi K2 Thinking demonstrated outstanding complex information gathering and reasoning capabilities, efficiently processing and analyzing large amounts of information.
-
Agentic programming ability: In benchmarks such as the multilingual software engineering benchmark SWE-Multilingual, the SWE-bench validation set, and Terminal terminal usage, Kimi K2 Thinking's performance has further improved, and it performs excellently when handling front-end tasks such as HTML and React.
API Usage Notes for Kimi-k2 Thinking
-
Input the full context: When calling the model, all thinking content must be included (the
reasoning_contentfield), so that the model can analyze based on the complete reasoning logic. -
Set a sufficiently large
max_tokens: It is recommended to setmax_tokens≥16000, to ensure that the model can fully output the reasoning process and results. -
Set the temperature parameter to 1.0: Set
temperatureto 1.0 to obtain the best performance and reasoning stability. -
Enable streaming output: Use streaming output (
stream=True) to improve the user experience and avoid network timeout issues caused by excessive output content.
Kimi-k2 Thinking Usage Pricing
-
Standard API:
-
Input: 4 yuan per million tokens for input.
-
Output: 16 yuan per million tokens for output.
-
Cache-hit input: 1 yuan.
-
-
Turbo API(speed up to 100 Token/s):
-
Input: 8 yuan per million tokens for input.
-
Output: 58 yuan per million tokens for output.
-
Cache-hit input: 1 yuan.
-
Kimi-k2 Thinking Project Address
- HuggingFace Model Repository:https://huggingface.co/moonshotai/Kimi-K2-Thinking
- Technical Paper:https://mp.weixinbridge.com/mp/wapredirect?url=https%3A%2F%2Fmoonshotai.github.io%2FKimi-K2%2Fthinking.html&action=appmsg_redirect&uin=MTE0MzM2NDMwMA==&biz=Mzk0NDU1MDkyNg==&mid=2247487508&idx=1&type=1&scene=0
Application Scenarios of Kimi-k2 Thinking
-
Complex problem solving: Used for complex problems that require multi-step reasoning and logical analysis, such as scientific experiment design, engineering optimization, etc.
-
Automated task planning: In tasks that require dynamic adjustment and multi-round decision-making, such as automated process design, resource allocation, etc.
-
Data analysis and reporting: Handle analysis tasks involving large amounts of data and complex logic, and generate in-depth reports, such as market trend analysis, financial forecasting, etc.
-
Intelligent search and information integration: Through multi-round tool calls, integrate information from different sources to provide users with comprehensive answers.
-
Education and learning assistance: Help students solve complex academic problems step by step, providing problem-solving ideas and logical reasoning processes.