
What is JoyVASA
JoyVASA is an audio-driven digital human head project open-sourced by JD Health International. Based on diffusion model technology, it generates facial dynamics and head movements synchronized with audio signals. JoyVASA can achieve lip synchronization and expression control for characters, and has also been extended to animation generation for animal heads, with broad application potential in multilingual support and cross-species animation.
Main Features of JoyVASA
- Audio-Driven Facial Animation: Generates facial animation synchronized with the input audio signal, including lip movements and expression changes.
- Lip Synchronization: Based on precise matching of audio and lip movements, it achieves realistic dialogue effects.
- Expression Control: Controls and generates specific facial expressions, enhancing the expressiveness of the animation.
- Animal Facial Animation: JoyVASA can generate facial dynamics for animals, expanding the scope of application.
- Multilingual Support: Based on training on a mixed dataset containing Chinese and English data, JoyVASA supports multilingual animation generation.
- High-Quality Video Generation: The project can generate high-resolution and high-quality animation videos, improving the viewing experience.
Technical Principles of JoyVASA
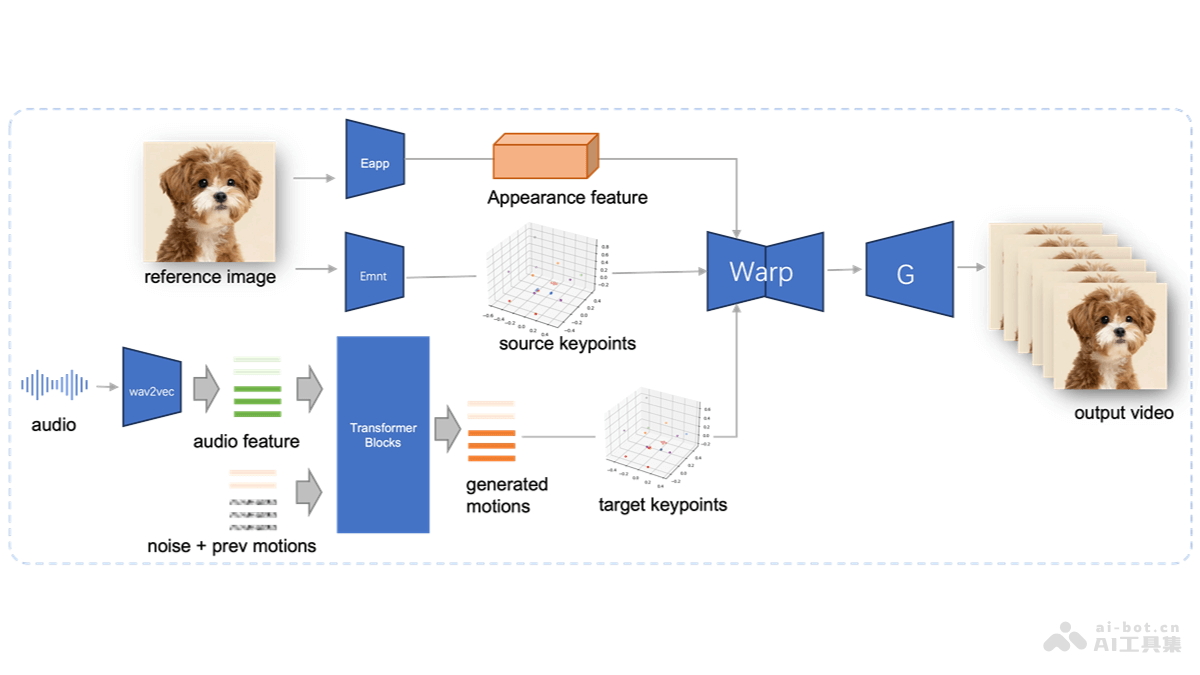
- Disentangled Facial Representation: JoyVASA uses a disentangled facial representation framework to separate dynamic facial expressions from static 3D facial representations, generating longer videos.
- Diffusion Model: The project uses a diffusion model to directly generate motion sequences from audio prompts, and the motion sequences are independent of character identity.
- Two-Stage Training:
- First Stage: Separates static facial features and dynamic motion features; static features capture the identity features of the face, while dynamic features encode dynamic elements such as facial expressions, scaling, rotation, and translation.
- Second Stage: Trains a diffusion transformer to generate motion features from audio features.
- Audio Feature Extraction: Uses the wav2vec2 encoder to extract audio features from the input speech as conditions for generating motion sequences.
- Motion Sequence Generation: Based on the diffusion model, samples audio-driven motion sequences in a sliding window; the motion sequences include facial expressions and head movements.
Project Addresses of JoyVASA
- Project Official Website:jdh-algo.github.io/JoyVASA
- GitHub Repository:https://github.com/jdh-algo/JoyVASA
- HuggingFace Model Library:https://huggingface.co/jdh-algo/JoyVASA
- arXiv Technical Paper:https://arxiv.org/pdf/2411.09209
Application Scenarios of JoyVASA
- Virtual Assistants: In smart homes, customer service, and technical support, it provides realistic facial animation and expressions for virtual assistants, improving the user interaction experience.
- Entertainment and Media: Used to generate or enhance characters' facial expressions and movements, reducing the need for traditional motion capture. It provides more natural facial expressions and animations for game characters, enhancing the immersion of games.
- Social Media: Users can use JoyVASA to generate their own virtual avatars for video chats or content creation on social media platforms.
- Education and Training: In online education platforms, create virtual teachers to provide a more engaging teaching experience. In fields such as healthcare and military, simulate character reactions and expressions for professional training.
- Advertising and Marketing: Create attractive virtual spokespersons for advertising and promotion, enhancing the appeal of brand image.