
What is JoyHallo
JoyHallo is an open-sourceAI digital humanmodel from JD.com, designed specifically for Mandarin, capable of generating realistic talking videos from audio. It is especially suitable for handling the complex lip movements and intonation of Mandarin, and has the ability to generate videos across languages. JoyHallo provides an open-source dataset and model training method, enabling users to generate Mandarin and English speaker videos. The project uses the Chinese wav2vec2 model for audio feature embedding and adopts a semi-decoupled structure to improve inference speed, increasing it by 14.3%.
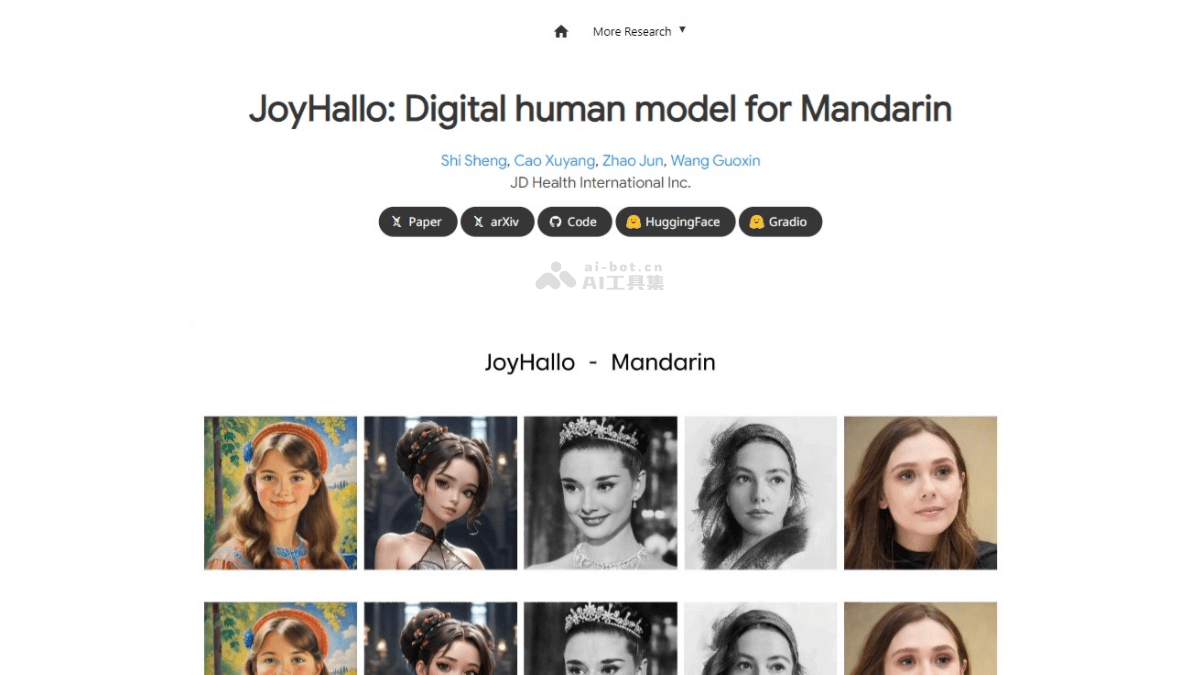
Main Features of JoyHallo
- Audio-driven video generation: JoyHallo can generate corresponding videos based on audio input, especially Mandarin videos.
- Cross-language generation capability: In addition to Mandarin, JoyHallo can generate English videos, demonstrating cross-language video generation capability.
- Lip synchronization: The model can accurately synchronize lip movements in audio and video, improving the realism of the video.
- Facial expression generation: Generate corresponding facial expressions based on the emotion and intonation in the audio.
Technical Principles of JoyHallo
- Semi-decoupled structure: Used to improve the accuracy of lip movement prediction in audio-driven video generation. By integrating and then separating key facial animation components, such as lips, expressions, and head pose, more precise modeling is achieved.
- Feature embedding: Uses the Chinese wav2vec2 model to embed audio features, helping the model better understand and generate facial movements synchronized with audio.
- Cross-attention mechanism: In the semi-decoupled structure, the cross-attention module processes the integrated features and captures correlations.
- Convolutional network: In the decoupling stage, a convolutional network is used to separate different features, allowing the model to focus on the specific details of each feature.
- Dataset: JoyHallo training is based on the jdh-Hallo dataset, a Mandarin video dataset containing multiple ages and speaking styles, covering daily conversations and professional medical topics.
JoyHallo Project Address
- Project official website:jdh-algo.github.io/JoyHallo
- GitHub repository:https://github.com/jdh-algo/JoyHallo
- HuggingFace model library:https://huggingface.co/jdh-algo/JoyHallo-v1
- arXiv technical paper:https://arxiv.org/pdf/2409.13268
Application Scenarios of JoyHallo
- Virtual anchors: In fields such as news broadcasting, weather forecasts, and sports event commentary, JoyHallo generates videos of virtual anchors, providing 24-hour uninterrupted program production.
- Online education: In fields such as language learning and online courses, JoyHallo generates virtual teacher avatars, providing a more vivid teaching experience.
- Customer service: In the customer service field, JoyHallo generates virtual customer service representatives, providing more friendly and professional customer service.
- Entertainment industry: In fields such as film, games, and animation production, JoyHallo generates facial animations for characters, improving production efficiency and reducing costs.
- Social media: Users use JoyHallo to generate their own virtual avatars and post video content on social media, increasing interactivity and fun.
- Advertising production: In the advertising industry, JoyHallo generates customized advertising videos, improving the appeal and personalization of advertisements.