
What is InternVL-U
InternVL-U is a 4B-parameter lightweight unified multimodal model open-sourced by Shanghai Artificial Intelligence Laboratory in collaboration with multiple top universities. It is the first to achieve an end-to-end closed loop of "understanding—reasoning—generation—editing". The model adopts three core designs: "unified context modeling + modality-specific modularization + decoupled visual representation", breaking through the bottlenecks of high training costs and imbalanced capabilities in traditional models. The model surpasses 14B-level models in complex scenarios such as text rendering, scientific reasoning, and spatial modeling. It scores 22.9 on the GenExam scientific image generation benchmark, leading all open-source unified models, and provides an efficient and flexible multimodal solution for scenarios such as scientific research and education, intelligent office work, and creative content.
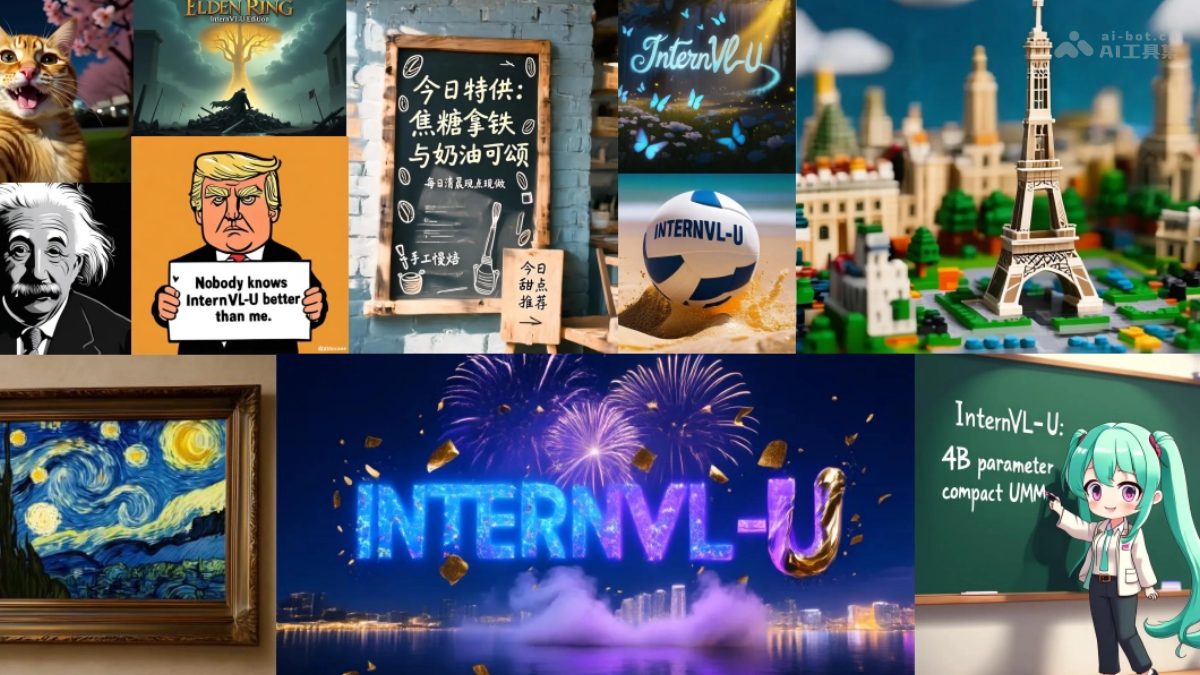
Main Features of InternVL-U
-
Multimodal Understanding: Supports precise parsing of visual information in images and answering various complex questions posed by users.
-
Logical Reasoning: The model uses chain-of-thought technology to decompose abstract natural language instructions into executable specific operation steps.
-
Image Generation: Generates high-fidelity, semantically accurate visual images that meet aesthetic standards based on text descriptions.
-
Image Editing: Precisely modifies the content of specified regions in an image while preserving the original background texture and lighting effects.
-
Text Rendering: The model can accurately generate Chinese and English text, numbers, and mathematical symbols, completely eliminating glyph distortion and spelling errors.
-
Scientific Visualization: Supports drawing professional scientific illustrations that conform to disciplinary standards, such as molecular structures and algorithm flowcharts.
-
Spatial Modeling: The model can perform solid geometry operations, CAD multi-view conversion, and arbitrary-angle rotation operations of three-dimensional objects.
-
Fun Creation: InternVL-U can quickly generate fun creative content adapted to online communication scenarios, such as emojis and memes.
Technical Principles of InternVL-U
- Decoupled Visual Representation: InternVL-U adopts an asymmetric visual representation strategy. In understanding tasks, it uses a pre-trained ViT to extract high-semantic features to ensure the accuracy of complex scene understanding. In generation tasks, it uses an independent VAE to compress images into latent space to preserve pixel-level details. The model avoids the optimization conflict between semantic understanding and image reconstruction, enabling the model to maintain leading performance in both understanding and generation benchmarks simultaneously.
- Dual-Stream MMDiT Generation Head: The visual generation head adopts a dual-stream structure to separately process multimodal context features and image latent features, adjusts weights through a sigmoid gated attention mechanism to alleviate performance degradation in long-context scenarios, and uses a unified MSRoPE three-dimensional position encoding to ensure precise preservation of spatial structure. It supports multi-resolution generation from 512 to 1024 pixels to avoid stitching artifacts at high resolutions.
- Three-Stage Progressive Training: The model adopts a three-stage strategy of pre-training, continued pre-training, and fine-tuning. In the first stage, the backbone network is frozen and the generation head is trained to activate multimodal context conditional understanding capabilities. In the second stage, the backbone network is fixed and multi-resolution generation capabilities are trained, with high-aesthetic samples selected. In the third stage, the entire model is unfrozen and chain-of-thought data is incorporated to achieve deep synergy among understanding, reasoning, and generation.
InternVL-U Project Address
- GitHub Repository:https://github.com/OpenGVLab/InternVL-U
- HuggingFace Model Library:https://huggingface.co/InternVL-U/InternVL-U
- arXiv Technical Paper:https://arxiv.org/pdf/2603.09877
Application Scenarios of InternVL-U
- Scientific Research and Education: Provides professional visual content such as molecular structures, algorithm flowcharts, and force analysis diagrams for researchers and students, assisting teaching demonstrations and paper figure creation.
- Smart Office: Enables automated document generation, batch poster editing, and synchronized modification of text across multiple regions, improving the efficiency of producing business documents and marketing materials.
- Creative Design: Supports designers in quickly generating high-fidelity concept images, stylized images, and multi-resolution visual assets, lowering the barrier to professional design.
- Content Operations: Helps new media operators generate fun content such as emoji packs and meme images with one click, adapting to social media dissemination scenarios.
- Industrial Manufacturing: The model can perform CAD multi-view conversion, solid geometry operations, and 3D object rotation, assisting engineering design and product prototype visualization.