
What is InternVL 2.5
InternVL 2.5 is an open-source multimodal large language model (MLLM) series launched by the OpenGVLab team at Shanghai AI Lab. This series significantly enhances InternVL 2.0, particularly in training and testing strategies and data quality. InternVL 2.5 includes models of various scales from 1B to 78B, accommodating different use cases and hardware requirements. InternVL2_5-78B is the first open-source model to score over 70 on the Multimodal Understanding Benchmark (MMMU), surpassing commercial models such as ChatGPT-4o and Claude-3.5-Sonnet. InternVL 2.5 achieves performance improvements based on Chain-of-Thought (CoT) reasoning technology, demonstrating strong multimodal capabilities in multiple benchmarks, including multidisciplinary reasoning, document understanding, and multi-image/video understanding.
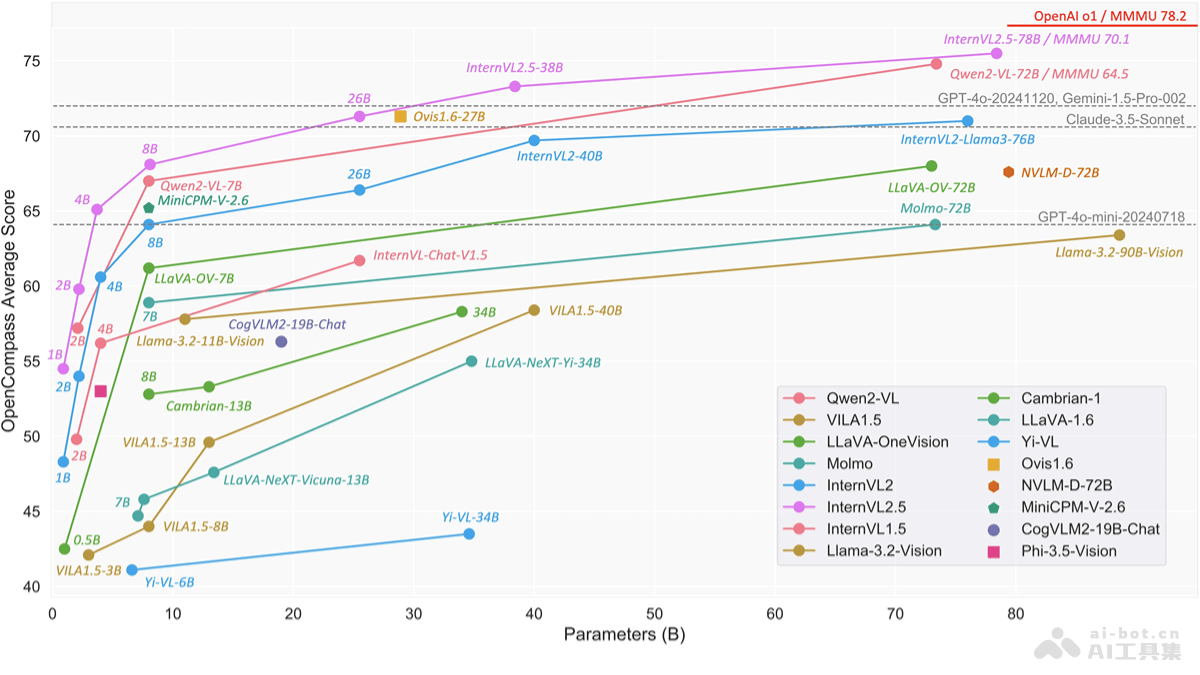
Main Features of InternVL 2.5
- Multimodal Understanding: Processes and understands information from different modalities (text, images, video).
- Multidisciplinary Reasoning: Performs complex reasoning and problem-solving across multiple subject areas.
- Real-World Understanding: Understands and analyzes real-world scenarios and events.
- Multimodal Hallucination Detection: Identifies and distinguishes real from fictional visual information.
- Visual Grounding: Matches textual descriptions to actual objects in images.
- Multilingual Processing: Supports understanding and generation capabilities in multiple languages.
- Pure Language Processing: Performs language tasks such as text analysis, generation, and understanding.
Technical Principles of InternVL 2.5
- ViT-MLP-LLM Architecture: Combines Vision Transformer (ViT) and Large Language Model (LLM) based on an MLP projector.
- Dynamic High-Resolution Training: Adapts to inputs of different resolutions, optimizing the processing of multi-image and video data.
- Pixel Unshuffle Operation: Reduces the number of visual tokens and improves model efficiency.
- Progressive Scaling Strategy: Starts training from a small-scale LLM and gradually expands to larger-scale models.
- Random JPEG Compression: Simulates internet image degradation to enhance the model's robustness to noisy images.
- Loss Reweighting: Balances the NTP loss of responses of different lengths to optimize model training.
Project Addresses of InternVL 2.5
- GitHub Repository:https://github.com/OpenGVLab/InternVL
- HuggingFace Model Library:https://huggingface.co/OpenGVLab/InternVL2_5
- arXiv Technical Paper:https://arxiv.org/pdf/2412.05271
- Online Experience Demo:https://huggingface.co/spaces/OpenGVLab/InternVL
Application Scenarios of InternVL 2.5
- Image and Video Analysis: Used for automatic annotation, classification, and understanding of image and video content, suitable for fields such as security surveillance, content moderation, and media entertainment.
- Visual Question Answering (VQA): Answers questions related to image or video content in fields such as education, e-commerce, and customer service, providing a richer user experience.
- Document Understanding and Information Retrieval: Extracts key information from large volumes of documents in fields such as law, healthcare, and academic research, supporting complex queries and research work.
- Multilingual Translation and Understanding: InternVL 2.5 supports multilingual processing and plays a role in cross-language communication, international business, and globalized content creation.
- Assisted design and creative work: In the design and creative industries, I help understand and realize complex visual ideas, such as architectural design, advertising creativity, and more.