
What is Insert Anything
Insert Anything is a context-editing-based image insertion framework jointly launched by researchers from Zhejiang University, Harvard University, and Nanyang Technological University. The framework is based on seamlessly inserting objects from a reference image into a target scene, and supports a variety of practical application scenarios, such as artistic creation, real face replacement, movie scene synthesis, virtual try-on, accessory customization, and digital prop replacement. Insert Anything is trained on the AnyInsertion dataset containing 120K prompt-image pairs, can flexibly adapt to a variety of insertion scenarios, and provides strong technical support for fields such as creative content generation and virtual try-on.
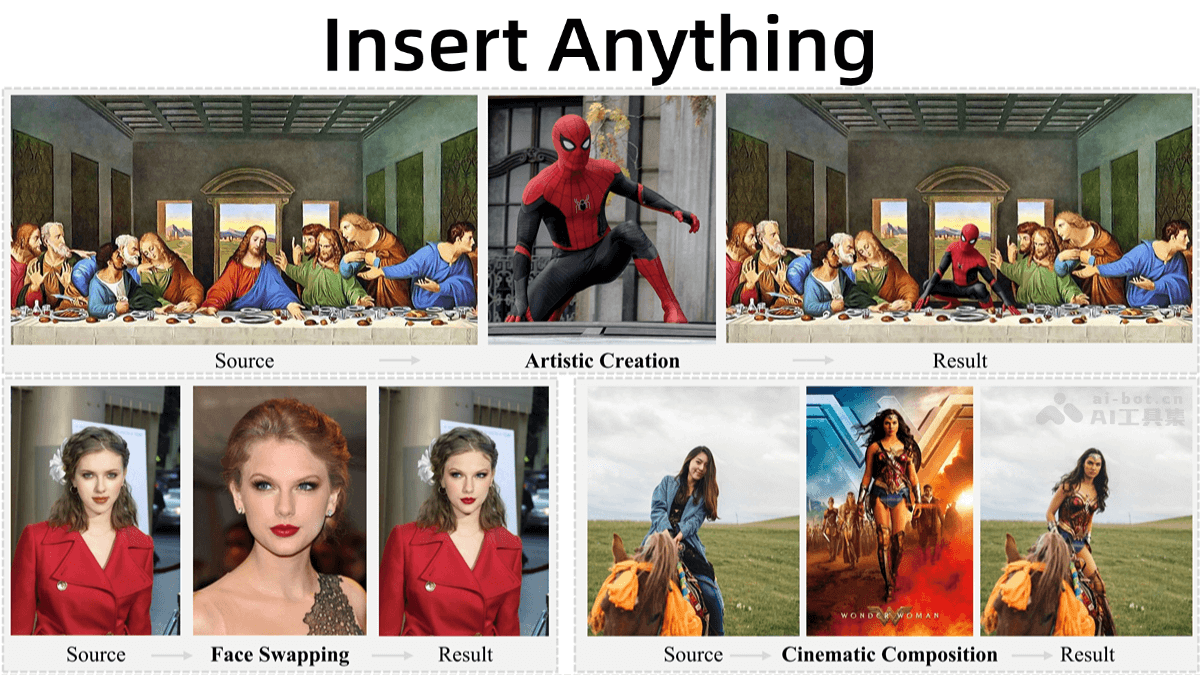
Main Features of Insert Anything
- Multi-scenario support: Supports handling a variety of image insertion tasks, such as person insertion, object insertion, and clothing insertion.
- Flexible user control: Supports mask-guided and text-guided control modes. Users specify the insertion region and content based on manually drawn masks or input text descriptions.
- High-quality output: Supports generating high-quality, high-resolution images while maintaining the detail and style consistency of the inserted elements.
Technical Principles of Insert Anything
- AnyInsertion dataset: The framework is trained using the large-scale dataset AnyInsertion, which contains 120K prompt-image pairs and covers a variety of insertion tasks (such as person, object, and clothing insertion).
- Diffusion Transformer (DiT): A DiT-based multimodal attention mechanism that simultaneously processes text and image inputs. DiT can jointly model the relationships among text, masks, and image patches, supporting flexible editing control.
- Context editing mechanism: Based on a polyptych format (such as mask-guided diptychs and text-guided triptychs), it combines the reference image with the target scene, allowing the model to capture contextual information and achieve natural insertion effects.
- Semantic guidance: Combines image encoders (such as CLIP) and text encoders to extract semantic information, providing high-level guidance for the editing process and ensuring style and semantic consistency between the inserted elements and the target scene.
- Adaptive cropping strategy: When processing small targets, it dynamically adjusts the cropping region to ensure that the editing area receives sufficient attention, preserves enough contextual information, and achieves high-quality detail retention.
Project Address of Insert Anything
- Project official website:https://song-wensong.github.io/insert-anything/
- GitHub repository:https://github.com/song-wensong/insert-anything
- arXiv technical paper:https://arxiv.org/pdf/2504.15009
Application Scenarios of Insert Anything
- Artistic creation: Quickly combine different elements to inspire creative ideas.
- Virtual try-on: Allow consumers to preview clothing effects and improve the shopping experience.
- Film and television special effects: Seamlessly insert virtual elements and reduce filming costs.
- Advertising design: Quickly generate a variety of creative advertisements and enhance appeal.
- Cultural heritage restoration: Virtually restore details of cultural relics or buildings, aiding research and display.