
What is Ingredients
Ingredients is a powerful framework based on combining multiple specific identity (ID) photos with a video diffusion Transformer, used for customized video creation. Ingredients achieves highly customized video generation based on three core modules: a face extractor, a multi-scale projector, and an ID router. The face extractor captures the facial features of each identity from global and local perspectives; the multi-scale projector maps these features into the context of the video diffusion model; the ID router dynamically allocates and combines multiple identity features into the corresponding temporal-spatial regions. Based on a carefully designed multi-stage training protocol, Ingredients can generate personalized videos with high identity fidelity and content flexibility without the need for prompt constraints.
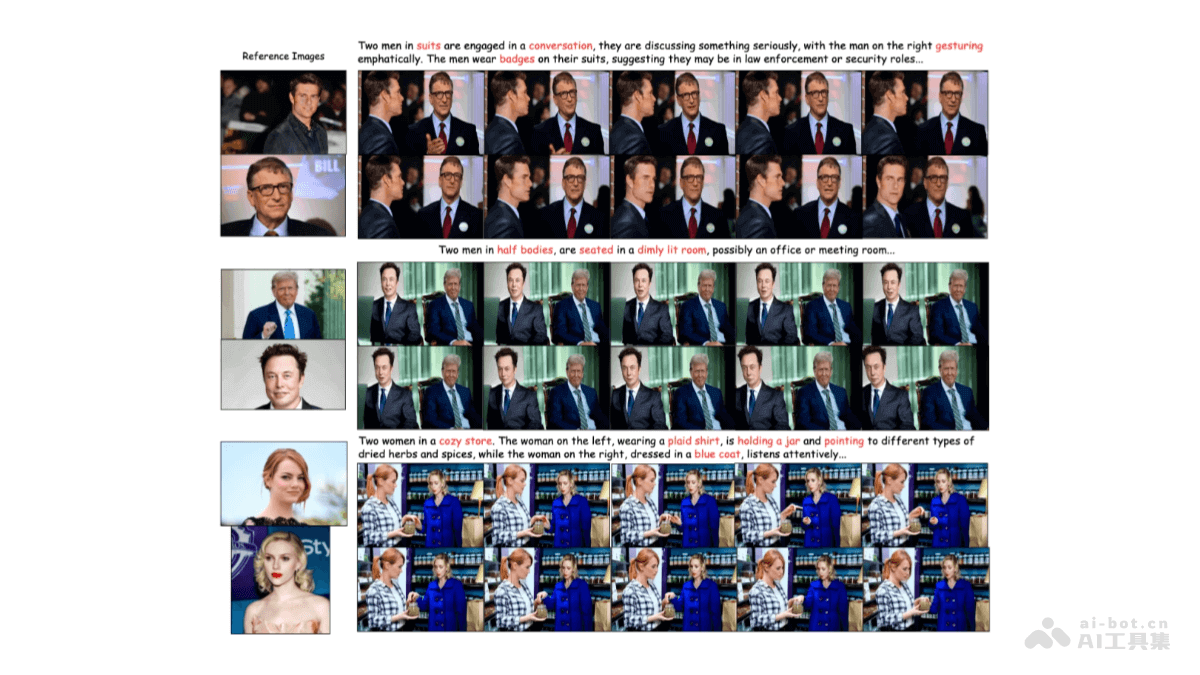
Main Features of Ingredients
- Maintain identity consistency: Maintain the consistency of the identities of people in multiple reference images in the generated video.
- Flexible content control: Supports users in precisely controlling video content with text prompts.
- High-quality video generation: Generate video content with high visual quality and natural transitions.
- Training-free customization: Enables customized video generation without the need for model training or fine-tuning for each new identity.
Technical Principles of Ingredients
- Face extractor: Responsible for extracting the facial features of each identity from the input reference images. Based on a combined global and local method, it extracts overall facial information from a global perspective and detailed features from a local perspective, ensuring the diversity and accuracy of the faces of people in the generated video.
- Multi-scale projector: Maps the extracted facial feature embeddings into the image query context of the video diffusion Transformer. Using multi-scale feature fusion and cross-attention mechanisms, it enables facial features to effectively interact with the visual tokens in the video diffusion model, accurately reflecting the identity information of people during the generation process.
- ID router: Responsible for dynamically allocating and combining multiple identity features within the temporal-spatial regions of video generation. Based on a location-aware routing network, it assigns each potential facial region to a unique identity feature, avoiding mixing and confusion of identity features, and ensuring clear distinction and consistent expression of different people's identities in the generated video.
Project Address of Ingredients
- GitHub repository:https://github.com/feizc/Ingredients
- HuggingFace model library:https://huggingface.co/feizhengcong/Ingredients
- arXiv technical paper:https://arxiv.org/pdf/2501.01790
Application Scenarios of Ingredients
- Entertainment creation: Produce a multi-scene music video for a virtual idol, maintaining consistent facial features and style, and enhancing fan interaction.
- Advertising industry: Customize advertisements in different styles for fashion brands, showcasing the fashion looks of the target audience in scenes such as campuses and streets, and improving brand appeal.
- Education and teaching: In language learning applications, create videos of international conference scenes, where learners watch exchanges among representatives from different countries and learn business English and cross-cultural communication.
- Social media: Users create family history videos, combining old photos and oral stories to show the life scenes of family members in different eras, and share them on social media to resonate with others.
- Virtual reality: In virtual reality tourism applications, generate a video of the user and a virtual tour guide touring a scenic spot, with the guide providing detailed introductions to the history and culture of the scenic spot, enhancing the realism of the tourism experience.