
What is InfiMM-WebMath-40B
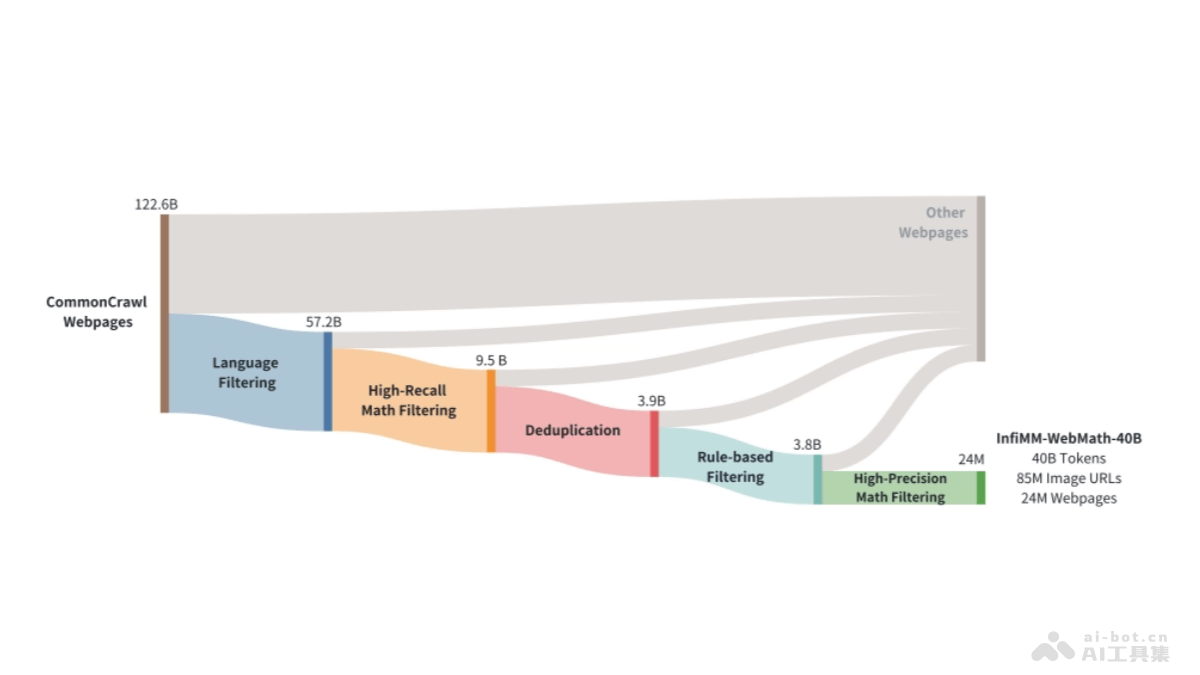
InfiMM-WebMath-40B is a super-large-scale multimodal dataset jointly open-sourced by ByteDance and the Chinese Academy of Sciences, aimed at enhancing the image-text mixed reasoning capabilities of multimodal models, in the field of mathematics. The dataset is extracted from Common Crawl, and after rigorous screening, cleaning, and annotation, it contains 24 million web pages, 85 million image URLs, and 40 billion text tokens, covering a rich amount of mathematics- and science-related content. InfiMM-WebMath-40B can significantly improve a model's capability in mathematical reasoning, achieving excellent results on benchmarks such as MathVerse and We-Math.
Main Features of InfiMM-WebMath-40B
- Enhancing Mathematical Reasoning Ability: InfiMM-WebMath-40B contains a large amount of mathematics- and science-related content, including text, formulas, symbols, and images, helping MLLMs learn mathematical knowledge and improve their capability in mathematical reasoning.
- Understanding Multimodal Information: This dataset is multimodal, containing text and image data, helping MLLMs learn how to combine text and image information for reasoning and better understand complex mathematical concepts and problems.
- P2 Promoting Model Applications: MLLMs pretrained based on InfiMM-WebMath-40B can be better applied to mathematics-related applications, such as math question banks, math learning tools, and reading and understanding mathematics papers.
Technical Principles of InfiMM-WebMath-40B
- Data Source: Based on Common Crawl, a large database containing publicly available web content from the internet.
- Data Screening: Based on keyword matching, retain pages containing specific terms such as mathematics and formulas. Set threshold conditions, for example, each document must contain at least a certain number of LaTeX symbols. Use fastText for language filtering, retaining only Chinese and English content.
- Data Extraction: Use the Trafilatura library to extract text content. Analyze image URLs in web pages and extract images related to mathematical content.
- Data Cleaning: Use techniques such as MinHash for deduplication. Adopt rule-based filtering methods, such as removing short documents containing "lorem ipsum," filtering out documents containing inappropriate content, and excluding documents containing Unicode errors.
- Data Annotation: Use the LLaMA3-70B-Instruct model to score mathematical content, and use a fastText classifier for high-precision filtering.
Project Address of InfiMM-WebMath-40B
- HuggingFace Model Library:https://huggingface.co/datasets/Infi-MM/InfiMM-WebMath-40B
- arXiv Technical Paper:https://arxiv.org/pdf/2409.12568
Application Scenarios of InfiMM-WebMath-40B
- Math Question Banks and Assessment Tools: Developers train MLLMs so that they can automatically generate math problems, evaluate student answers, and provide feedback, building intelligent math question banks and assessment tools.
- Math Learning Tools and Platforms: Help MLLMs better understand mathematical concepts and formulas, and develop more intelligent math learning tools and platforms, such as providing personalized learning suggestions, answering students' questions, and assisting with solving math problems.
- Reading and Understanding Mathematics Papers: MLLMs improve their ability to understand mathematics papers and develop tools that can automatically summarize, translate, and explain mathematics papers.
- Mathematical Research: Provide data support for mathematical research, for example, for training mathematical models, conducting mathematical experiments, and analyzing mathematical data.
- Other scientific fields: InfiMM-WebMath-40B contains science-related content, such as physics, chemistry, biology, etc., to train MLLMs to understand scientific concepts, formulas, and images, and to assist scientific research and applications.