
What is IndexTTS
IndexTTS is an industrial-grade controllabletext-to-speech(TTS) system launched by Bilibili. Developed based on the XTTS and Tortoise models, it combines GPT-style generation technology and can efficiently convert text into natural and fluent speech. IndexTTS's advantage is its ability to process Chinese text, supporting pinyin correction of Chinese character pronunciation and precise pause control through punctuation, effectively solving the pronunciation problems of polyphonic characters and long-tail characters. It adopts a hybrid modeling method, combining Chinese characters and pinyin, to optimize speech generation. In terms of performance, IndexTTS has a word error rate (WER) of only 1.3%, a speaker similarity (SS) of 0.776, and a subjective mean opinion score (MOS) of 4.01, demonstrating excellent performance. It is trained with a large amount of data, including 25,000 hours of Chinese audio and 9,000 hours of English audio, ensuring high-quality sound and timbre.
The latest self-developed IndexTTS2, a new-generation speech synthesis model, can achieve precise duration control and emotional reproduction, support independent adjustment of timbre and emotion, and generate natural and fluent speech in multiple languages and styles. It is widely used in fields such as video dubbing and language learning. The model has reached industry-leading levels in both emotional expression and text accuracy.
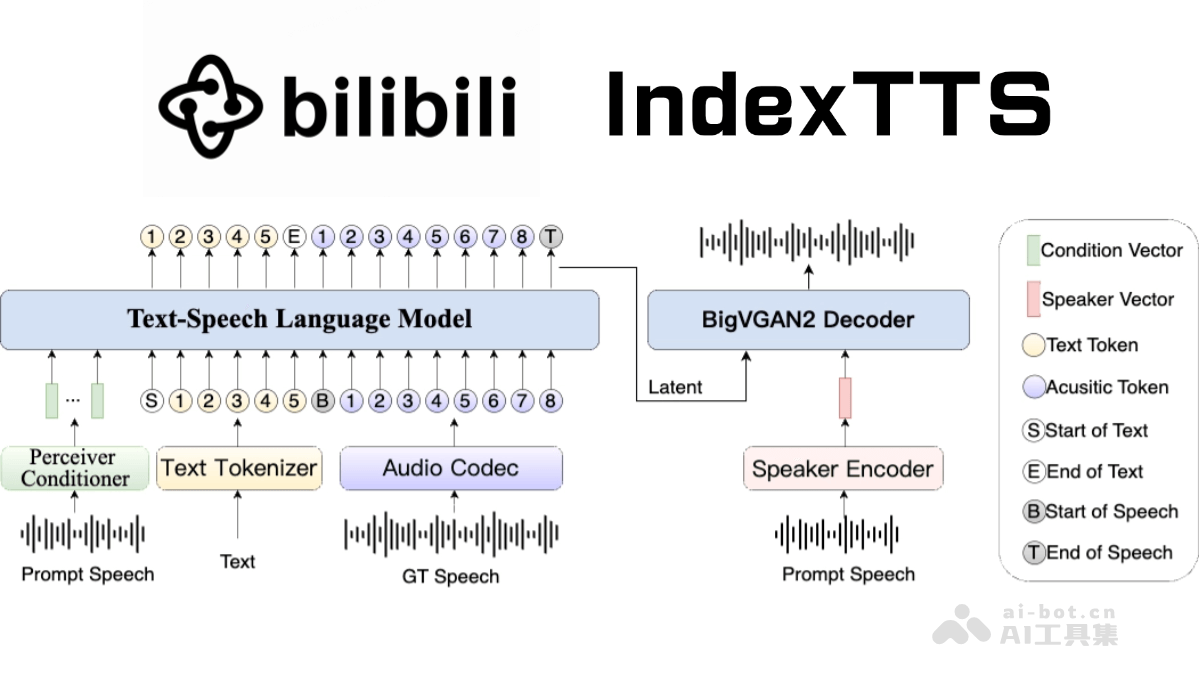
Main features of IndexTTS
- Pinyin correction and pause control: When processing Chinese text, IndexTTS can correct the pronunciation of Chinese characters through pinyin and precisely control pauses at any position using punctuation, making speech output more natural and fluent.
- Audio quality optimization: It introduces a Conformer-based conditional encoder and BigVGAN2 speech decoder, significantly improving audio quality and timbre similarity, with a MOS score of 4.01.
- Multilingual support: It currently supports Chinese and English, with plans to expand to more languages in the future.
Technical principles of IndexTTS
- Hybrid modeling method: In Chinese scenarios, IndexTTS adopts a hybrid modeling approach of characters and pinyin. By combining Chinese characters and pinyin, the system can quickly correct pronunciation errors of polyphonic characters and long-tail characters, improving the accuracy and controllability of speech synthesis.
- Speech encoding and decoding optimization: IndexTTS introduces a Conformer-based conditional encoder and BigVGAN2 speech decoder. The Conformer encoder can better capture timbre features of speech, while the BigVGAN2 decoder improves audio quality and timbre similarity.
- Zero-shot voice cloning: IndexTTS performs excellently in zero-shot voice cloning and can generate high-quality speech without target speech samples. Speaker similarity (SS) is as high as 0.776, and the MOS score reaches 4.01, far exceeding existing systems.
- Efficient training and inference: The system is trained on tens of thousands of hours of data. The training process is simple and stable, and inference is fast. Compared with systems such as XTTS, CosyVoice2, Fish-Speech, and F5-TTS, IndexTTS performs excellently in naturalness, content consistency, and zero-shot voice cloning.
IndexTTS project address
- IndexTTS:
- Github repository:https://github.com/index-tts/index-tts
- arXiv technical paper:https://arxiv.org/pdf/2502.05512
- IndexTTS2:
- Project official website:https://index-tts.github.io/index-tts2.github.io/
- HuggingFace model library:https://huggingface.co/IndexTeam/IndexTTS-2
- arXiv technical paper:https://arxiv.org/pdf/2506.21619
Application scenarios of IndexTTS
- Content creation and video dubbing: IndexTTS can quickly generate natural and fluent speech content, helping video creators save recording time and quickly complete video dubbing.
- Audiobooks and Online Education: Supports high-quality speech synthesis in Chinese and English, and can provide natural voice reading services for audiobooks and online education platforms, enhancing the user experience.
- Intelligent Customer Service and Voice Assistants: IndexTTS's zero-shot voice cloning capability and high naturalness make it suitable for intelligent customer service and voice assistant scenarios, and it can quickly adapt to different voice styles and speaking rates.
- Multimedia and Entertainment: In the multimedia and entertainment fields, IndexTTS can be used to generate personalized voice content, such as game dubbing, virtual character dialogue, etc., providing users with a more immersive experience.
- Accessibility Assistive Technology: With efficient speech synthesis capability and a low error rate, IndexTTS can provide voice assistance for visually impaired people, helping them better obtain information.