
What is IFAdapter
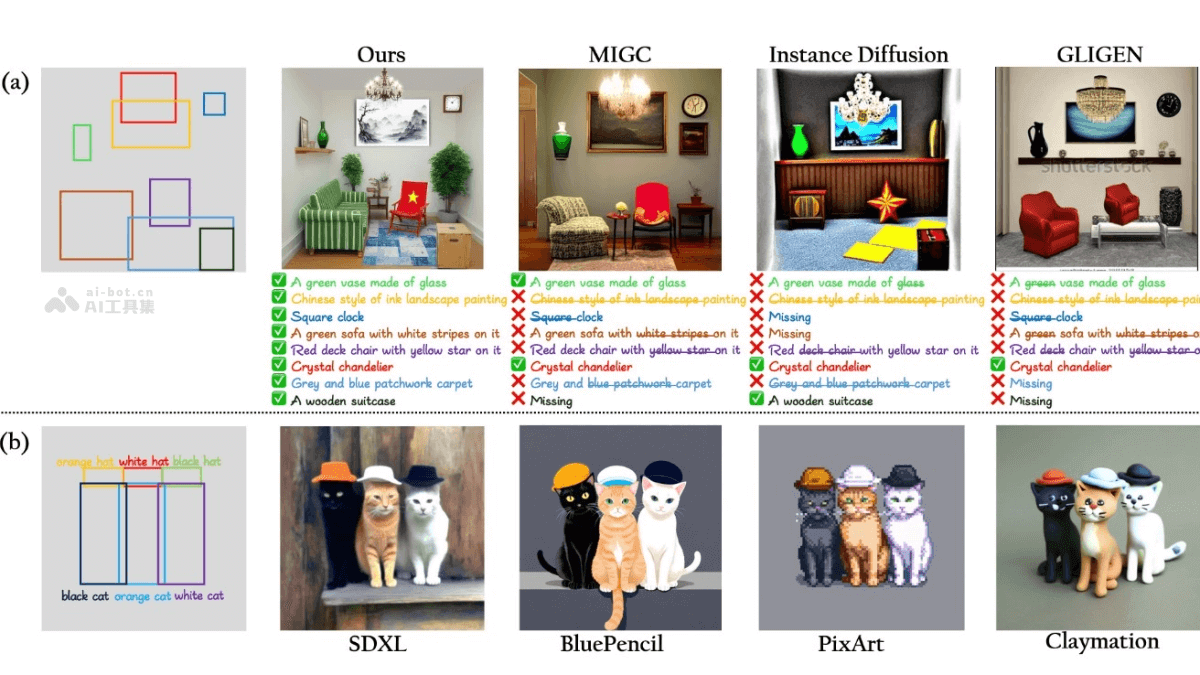
IFAdapter is a new type of text-to-image generation model jointly launched by Tencent and the National University of Singapore. It improves positional and feature accuracy when generating images containing multiple instances. Traditional models often face challenges in positioning and feature accuracy when handling multi-instance images. IFAdapter solves the problem by introducing two key components: Appearance Tokens and Instance Semantic Map. Appearance Tokens are used to capture detailed feature information in the description, while the Instance Semantic Map aligns features with specific spatial positions, enhancing the model's ability to control instance features. IFAdapter is designed to support being used as a plug-and-play module that can be easily integrated into various pre-trained diffusion models without retraining, providing flexible spatial control capabilities for different community models.
IFAdapter's Main Features
- Instance Feature Generation: Ensures that each instance in the generated image is accurately positioned in space and has high-fidelity feature details.
- Plug-and-Play Module: As an independent module, it can be easily integrated into various pre-trained diffusion models without retraining the main model.
- Spatial Control: Provides precise spatial control signals and improves instance positioning.
IFAdapter's Technical Principles
- Appearance Tokens: Based on cross-attention interaction between learnable appearance queries and descriptions, it extracts instance-specific high-frequency feature information to form appearance tokens, which help generate more refined instance features.
- Instance Semantic Map (ISM): Constructs a 2D semantic map that associates instance features with specified positions in the image, providing stronger spatial priors and preventing feature confusion and leakage.
- Gated Semantic Fusion: In areas where instances overlap, a feature fusion mechanism is used to resolve feature conflicts, ensuring that visual features are dominated by the frontmost instance.
- Plug-and-Play Design: As an independent module, IFAdapter is integrated into different diffusion models through cross-attention layers to achieve fine-grained control over the generation process.
- Training Strategy: During training, IFAdapter's parameters are trained to adapt to specific tasks, while the base model's parameters remain frozen, enhancing the model's control capability without damaging the original model's performance.
IFAdapter's Project Address
- Project Official Website:ifadapter.github.io
- GitHub Repository:https://github.com/WUyinwei-hah/IFAdapter(Coming Soon)
- arXiv Technical Paper:https://arxiv.org/pdf/2409.08240v1
IFAdapter's Application Scenarios
- Graphic Design: When designing logos, posters, invitations, and more, designers can use IFAdapter to generate images with specific style and layout requirements.
- Fashion Design: Designers use IFAdapter to create realistic renderings of clothing or accessories, displaying different colors, textures, and styles.
- Game Development: In game design, IFAdapter helps artists generate game elements or backgrounds with specific features.
- Virtual Reality and Augmented Reality: In VR/AR environments, IFAdapter generates virtual scenes that meet specific spatial layout and style requirements.