
What is Hyper-SD
Hyper-SD is an efficient image synthesis framework launched by researchers at ByteDance, aiming to solve the problem of high computational cost in the multi-step inference process of existing diffusion models. Hyper-SD maintains data consistency across different time periods through Trajectory Segmented Consistency Distillation (TSCD) technology, thereby effectively preserving the original ODE (ordinary differential equation) trajectory. In addition, it incorporates human feedback learning, optimizes model performance under low-step inference, and uses score distillation to further improve the image quality of single-step inference. This framework can greatly reduce the necessary inference steps while maintaining high image quality, achieving rapid generation of high-resolution images, and further promoting the development of the generative AI field.
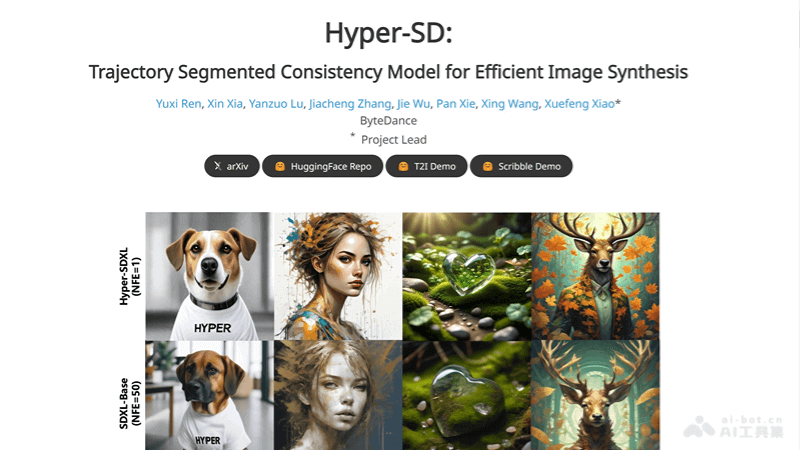
Hyper-SD official website entry
- Official project homepage:https://hyper-sd.github.io/
- Hugging Face model address:https://huggingface.co/ByteDance/Hyper-SD
- arXiv research paper:https://arxiv.org/abs/2404.13686
- Hyper-SD T2I version Demo:https://huggingface.co/spaces/ByteDance/Hyper-SDXL-1Step-T2I
- Hyper-SD scribble version Demo:https://huggingface.co/spaces/ByteDance/Hyper-SD15-Scribble
How Hyper-SD works
- Trajectory Segmented Consistency Distillation (TSCD):Divide the training timestep range [0, T] into k uniform time periods.Perform consistency distillation within each time period, using the original model as the teacher, and the student model gradually learns the behavior of the teacher model.By gradually reducing the number of time periods (such as 8 → 4 → 2 → 1), train the student model to approximate the global behavior of the teacher model.
- Human Feedback Learning (ReFL):Use human preference feedback on images to optimize the model.Train a reward model so that it can identify and reward images that better match human aesthetics.Through iterative denoising and direct prediction, combined with feedback from the reward model, fine-tune the student model.
- Score Distillation:Use the score functions of the real distribution and the fake distribution to guide the single-step inference process.By minimizing the KL divergence between the two distributions, optimize the student's single-step generation performance.
- Low-Rank Adaptation (LoRA):Use LoRA technology to adapt and train the student model, making it a lightweight plugin that can be quickly deployed and used.
- Training and loss function optimization:Define the loss function, combining consistency loss, human feedback loss, and score distillation loss.Use optimization algorithms such as gradient descent to train the student model, while updating the LoRA plugin.
- Inference and image generation:After training is completed, use the student model for the inference process of image generation.According to the needs of the application scenario, choose the appropriate number of inference steps to balance generation quality and efficiency.
- Performance evaluation:Use quantitative metrics (such as CLIP score, aesthetic score) and qualitative metrics (such as user studies) to evaluate the quality of generated images.Based on the evaluation results, further adjust and optimize model parameters.