
What is HyOCR-1.5
HyOCR-1.5 is Tencent Hunyuan's open-source lightweight end-to-end OCR expert large model. With only 1B parameters, it can achieve full-stack capabilities including document parsing, text recognition, information extraction, photo translation, chart parsing, ancient script recognition, video subtitle extraction, and multi-page document question answering. The model is based on DFlash speculative decoding, achieving up to 6.37x speedup for long structured output inference; OmniDocBench v1.6 ranks first end-to-end with 94.74 points.
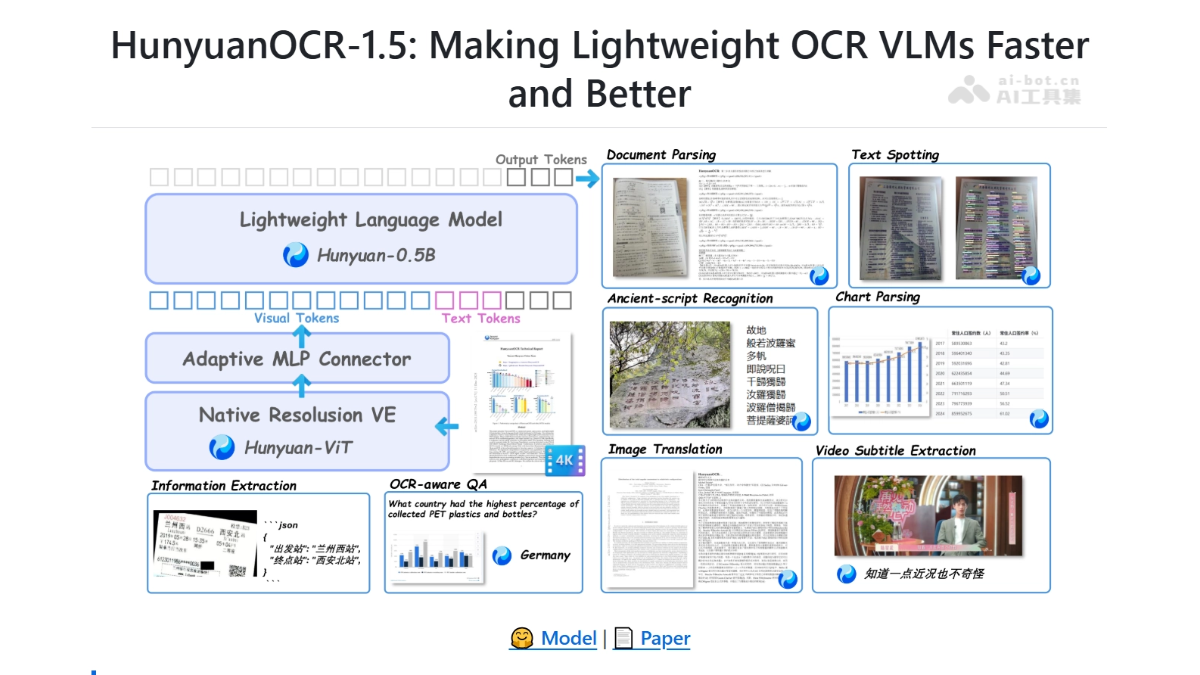
HyOCR-1.5's Main Features
-
Document Parsing: Convert dense documents, multi-column layouts, tables, and formulas into structured text (Markdown/HTML/LaTeX) with one click.
-
Text Detection and Recognition: Output all text content in images and their corresponding coordinates, covering scenarios such as documents, street scenes, handwriting, advertisements, games, and videos.
-
Information Extraction: Extract specified fields from receipts, certificates, and invoices and return them in JSON format.
-
Photo Translation: Extract text from images and translate it into multiple languages, preserving document layout and formula formatting.
-
Chart Parsing: Parse flowcharts and statistical charts into Mermaid or Markdown format.
-
Ancient Script Recognition: Supports recognition of the seven forms of Chinese characters (oracle bone, bronze, seal, clerical, regular, running, cursive).
-
Video Subtitle Extraction: Accurately extract subtitle text from video frames.
-
Multi-Page Document Question Answering: Perform cross-page retrieval, comparison, and evidence aggregation question answering based on multi-page PDFs.
HyOCR-1.5's Technical Principles
- Lightweight End-to-End Architecture: Following the compact design validated by HyOCR-1.0, it consists of the native-resolution vision encoder Hunyuan-ViT, an adaptive MLP connector, and the lightweight language model Hunyuan-0.5B. It directly maps multimodal inputs into structured outputs such as Markdown, HTML, and LaTeX, without any task-level post-processing modules.
- 4K Native Resolution Vision Encoding: The vision encoder is built on Hunyuan-ViT, with the maximum input resolution expanded from 2K to 4K, preserving the original aspect ratio and spatial layout, enabling the model to capture fine-grained structural details of high-density documents, oversized tables, and complex layouts.
- DFlash Speculative Decoding: Introduces a block-diffusion draft model with approximately 90.7M parameters. A single parallel forward pass predicts an entire block of candidate tokens, which are then verified in a single pass by the target model, accepting the longest correct prefix. While strictly preserving the target model's output distribution, it greatly reduces the decoding latency of long structured OCR generation.
- Agentic Data Flow: An agent-driven data production closed loop that transforms model weaknesses into executable data requirements, autonomously completing material search, tool-assisted cleaning, hard example mining, and data pipeline development, and continuously iterating with algorithm engineers.
- Three-Stage Training Recipe: In the pre-training stage, Stage 3 is re-planned, injecting new capability data and expanding to 4K resolution and 128K context; in the SFT stage, data is thoroughly cleaned and the prompt interface is unified; in the RL stage, IcePop (GRPO-style) optimization is adopted, improving output quality through three complementary rewards: factuality, consistency evaluation, and degeneration suppression.

Follow WeChat and reply "Open Source" to join theAI Open Source Project Exchange Group
How to Use HyOCR-1.5
-
Environment Preparation: Install Python 3.12+, CUDA 12.9, PyTorch 2.7.1, and vLLM (≥0.12.0).
-
Model startup: Run
vllm serve tencent/HunyuanOCRto start the service, or load Hugging Face weights. -
Image input: Use PIL to read images and build a messages conversation structure containing image and text.
-
Task instructions: Select a Prompt based on the scenario, such as document parsing, text detection, information extraction, translation, etc.
-
Invoke inference: Generate results via vLLM or Transformers, setting temperature=0 and max_tokens=16384.
-
Result cleanup: Use the built-in deduplication function to clean up possible repeated substrings and obtain the final structured output.
-
Local deployment: Run on CPU or consumer-grade GPUs via llama.cpp, with no server required.
Core advantages of HyOCR-1.5
-
Ultra-fast inference: DFlash speculative decoding speeds up long document generation by 6.37x under Transformers and 2.14x under vLLM, with only 1.4 seconds per page end-to-end.
-
Lightweight and deployable: The 1B parameters can run locally on CPUs, consumer-grade graphics cards, and laptops via llama.cpp.
-
SOTA accuracy: Ranked first end-to-end on OmniDocBench v1.6 (94.74), table TEDS 93.67, with outstanding performance on complex tables and reading order.
-
Full-stack open source: Training recipes, inference frameworks, and model weights are fully public, reproducible, fine-tunable, and extensible.
-
Long-tail capabilities: Agentic Data Flow fills in scarce capabilities such as 331 low-resource languages, ancient scripts, and multi-image question answering.
-
High-resolution long context: Supports 4K image resolution and 128K context, suitable for high-density long documents.
-
Hallucination suppression: CHAOS-Bench average recall per page is 14.15, outperforming existing models and keeping output more faithful to what is seen.
Project address of HyOCR-1.5
- GitHub repository:https://github.com/Tencent-Hunyuan/HunyuanOCR
- HuggingFace model library:https://huggingface.co/tencent/HunyuanOCR
- arXiv technical paper:https://arxiv.org/pdf/2607.04884
Comparison of HyOCR-1.5 with similar competitors
| Dimension | HyOCR-1.5 | DeepSeek-OCR-2 |
|---|---|---|
| Parameter scale | 1B (lightweight) | 3B (3x larger) |
| OmniDocBench | 94.74 | 87.01 |
| End-to-end latency | 1.408s / page | 5.460s / page (3.9x slower) |
| Table parsing TEDS | 93.67 | About 84.97 |
| Inference acceleration | DFlash speculative decoding, 6.37x speedup with Transformers | No dedicated acceleration, pure autoregressive decoding |
| Deployment cost | Can run on CPU / laptop | Requires server-grade GPU |
Application scenarios of HyOCR-1.5
- Dense document digitization: One-click conversion of high-density multi-column layouts such as contracts, papers, and reports into Markdown / HTML / LaTeX structured text, preserving reading order and layout.
- Complex table and formula parsing: Accurately restores very large tables and mathematical formulas in financial reports and academic papers, supporting HTML table and LaTeX formula output.
- Multilingual cross-border document processing: Covers 331 languages, automatically identifies and parses mixed-language documents, suitable for global business scenarios such as foreign trade, legal affairs, and publishing.
- Ancient Script Research and Preservation: Recognizes the seven styles of Chinese characters, including oracle bone script, bronze script, seal script, and clerical script, assisting museums and archaeological institutions in digitally archiving and researching historical documents.