
What is HybridRAG
HybridRAG is a hybrid retrieval-augmented generation architecture introduced by Blackstone and NVIDIA, combining a machine learning architecture with a Retrieval-Augmented Generation model. The model uses a retrieval system to find information relevant to the input, then feeds this information together with the input into the generation model to produce more accurate and richer output. HybridRAG performs excellently in natural language processing tasks such as question answering, summarization, and dialogue generation, and can leverage a large amount of external knowledge to improve the quality and relevance of generated content.
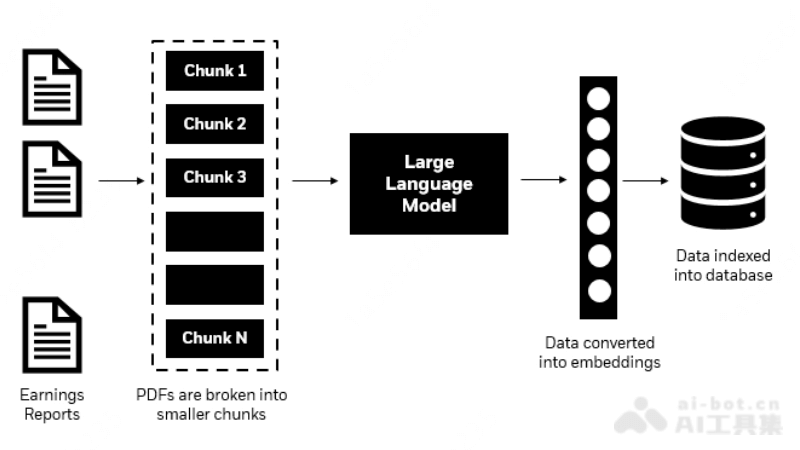
Main Features of HybridRAG
- Information Retrieval: HybridRAG uses a retrieval system to quickly locate documents or information snippets relevant to the user's query, helping the model obtain broader background knowledge.
- Context Understanding: Through the retrieved information, HybridRAG can better understand the context of the user's query, thereby generating more accurate and relevant responses.
- Knowledge Fusion: By combining retrieved knowledge with user input, HybridRAG can generate answers containing rich information and deep understanding.
- Generation Capability: Based on the retrieved information and user input, HybridRAG uses a generation model (such as Transformer) to construct answers or complete other language generation tasks.
- Multi-Task Learning: The design of HybridRAG allows it to be applied to a variety of natural language processing tasks, such as question answering systems, text summarization, and dialogue systems.
Project Address of HybridRAG
- GitHub Repository:https://github.com/IGoodHandI/HyrbridRAG
- NVIDIA:https://github.com/nvidia/workbench-example-hybrid-rag
- arXiv Technical Paper:https://arxiv.org/pdf/2408.04948
How to Use HybridRAG
- Environment Configuration: Ensure that the necessary libraries and frameworks are installed in the computing environment, such as PyTorch or TensorFlow, as well as HybridRAG's dependency libraries.
- Data Preparation: Collect and preprocess data, including steps such as cleaning, tokenization, and vectorization of text data.
- Model Selection: Select the appropriate HybridRAG model architecture according to the task requirements. This involves choosing different retrieval components and generation components.
- Model Training: Use the prepared data to train the HybridRAG model. This includes setting training parameters such as learning rate, batch size, and training epochs.
- Retrieval System Integration: Integrate the retrieval system with the HybridRAG model to ensure that the model can access the relevant knowledge base or document collection.
Application Scenarios of HybridRAG
- Question Answering Systems: HybridRAG can be used to build question answering systems that can understand user queries, retrieve information from documents, and generate accurate and detailed answers.
- Text Summarization: In text summarization tasks, HybridRAG can analyze long articles or documents and generate short summaries containing key information.
- Dialogue Systems: HybridRAG can be used to build chatbots, providing a more natural and information-rich dialogue experience through retrieval and generation techniques.
- Content Recommendation: HybridRAG can analyze user interests and preferences, retrieve and generate recommended content, and improve the personalization and accuracy of recommendations.