
What is HunyuanWorld-Voyager
HunyuanWorld-Voyager(abbreviated as HunyuanVoyager)It is the industry's first ultra-long roaming world model launched by Tencent that supports native 3D reconstruction. It is a novel video diffusion framework that can generate 3D point cloud sequences with user-defined camera paths from a single image, support 3D-consistent scene video generation along custom camera trajectories for world exploration, and generate aligned depth and RGB videos for efficient and direct 3D reconstruction. The model contains two key components: world-consistent video diffusion and long-distance world exploration, achieving iterative scene expansion through efficient point culling and autoregressive inference. A scalable data engine is proposed for generating scalable data for RGB-D video training. In the WorldScore benchmark, Voyager achieved excellent results across multiple metrics, demonstrating its strong performance.
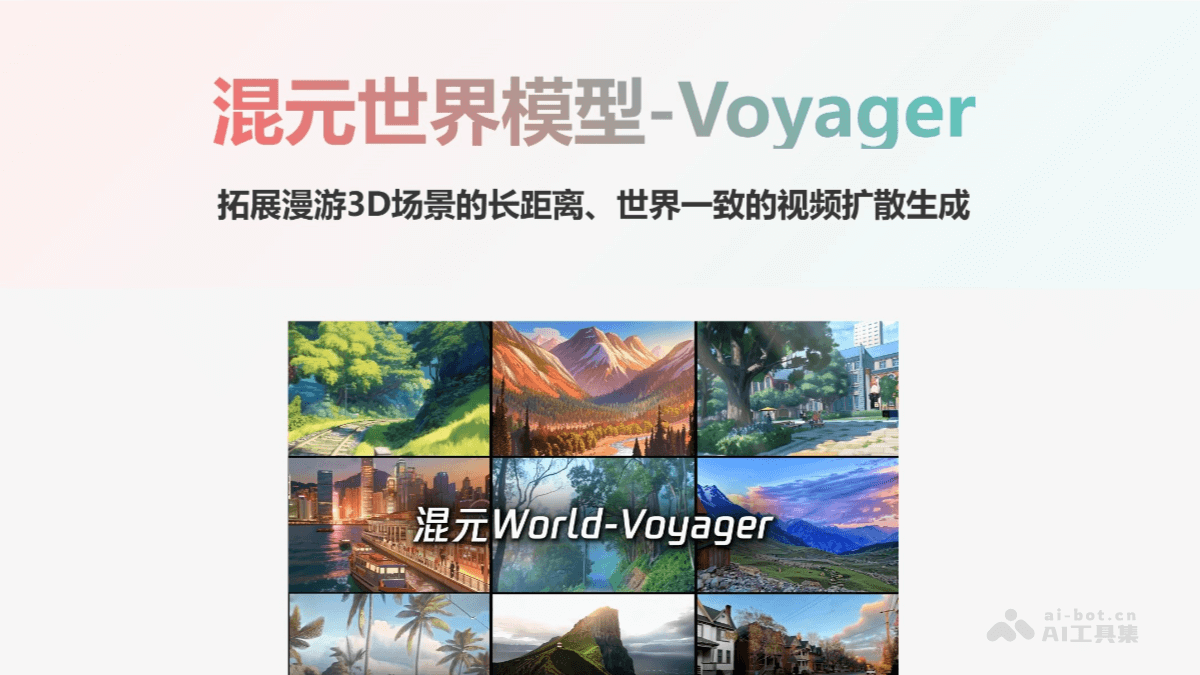
Main Features of HunyuanWorld-Voyager
-
Generate 3D point cloud sequences from a single image: It can generate 3D-consistent point cloud sequences from a single image according to user-defined camera paths, supporting long-distance world exploration.
-
Generate 3D-consistent scene videos: It can generate 3D-consistent scene videos along user-defined camera trajectories, providing users with an immersive 3D scene roaming experience.
-
Support real-time 3D reconstruction: The generated RGB and depth videos can be directly used for efficient 3D reconstruction without additional reconstruction tools, achieving rapid conversion from video to 3D models.
-
Support for multiple application scenarios: It is suitable for various 3D understanding and generation tasks such as video reconstruction, image-to-3D generation, and video depth estimation, with broad application prospects.
-
Strong performance: In the WorldScore benchmark released by Stanford University, HunyuanWorld-Voyager achieved excellent results across multiple key metrics, demonstrating its strong capabilities in 3D scene generation and video diffusion.
Technical Principles of HunyuanWorld-Voyager
-
World-consistent video diffusion: The model adopts a unified architecture to jointly generate aligned RGB and depth video sequences, ensuring global consistency by conditioning on existing world observations.
-
Long-distance world exploration: It utilizes efficient point culling techniques and autoregressive inference, combined with smooth video sampling, to achieve iterative scene expansion while maintaining context-aware consistency.
-
Scalable data engine: A video reconstruction pipeline is proposed that automatically performs camera pose estimation and metric depth prediction, capable of generating large-scale, diverse training data for arbitrary videos without manual 3D annotation.
-
Autoregressive inference and world caching mechanism: Through efficient point culling and autoregressive inference, combined with a world caching mechanism, it achieves iterative scene expansion, maintains geometric consistency, and supports arbitrary camera trajectories.
-
Efficient 3D reconstruction: The generated RGB and depth videos can be directly used for efficient 3D reconstruction without additional reconstruction tools, achieving rapid conversion from video to 3D models.
Project Address of HunyuanWorld-Voyager
-
Project official website:https://3d-models.hunyuan.tencent.com/world/
-
Github repository:https://github.com/Tencent-Hunyuan/HunyuanWorld-Voyager
-
Hugging Face model library:https://huggingface.co/tencent/HunyuanWorld-Voyager
-
Technical report:https://3d-models.hunyuan.tencent.com/voyager/voyager_en/assets/HYWorld_Voyager.pdf
Application Scenarios of HunyuanWorld-Voyager
-
Video reconstruction: By generating aligned RGB and depth videos, it enables efficient and direct 3D reconstruction without the need for additional reconstruction tools.
-
Image-to-3D Generation: Generates 3D-consistent point cloud sequences from a single image, supporting the conversion from 2D images to 3D scenes, and can be used for the rapid construction of virtual scenes.
-
Video Depth Estimation: Generates depth information aligned with RGB videos, and can be used for video analysis and 3D understanding tasks.
-
Virtual Reality (VR) and Augmented Reality (AR): The generated 3D scenes and videos can be used to create immersive VR experiences or augmented reality applications.
-
Game Development: The generated 3D scene assets can be seamlessly integrated into mainstream game engines, providing rich creativity and content support for game development.
-
3D Modeling and Animation: The generated 3D point clouds and videos can serve as input for 3D modeling and animation production, improving creative efficiency.