
What is HunyuanVideo 1.5
HunyuanVideo 1.5 is a lightweight model open-sourced by the Tencent Hunyuan teamvideo generationmodel with a parameter scale of 8.3B. The model is based on the Diffusion Transformer architecture and supports generating 5-10 second high-definition videos from text descriptions or images. It has strong instruction understanding capabilities and can accurately achieve diverse scene generation, including realistic, animation, and other styles. The model innovatively adopts the SSTA sparse attention mechanism, significantly improving inference efficiency and enabling smooth operation on consumer-grade GPUs with 14G VRAM, lowering the barrier to use. The model generates high-quality videos and supports super-resolution from 480p to 1080p, making it suitable for content creation, education, entertainment, and many other fields. The model is already available onYuanbao, where users can experience the model's powerful video generation capabilities.
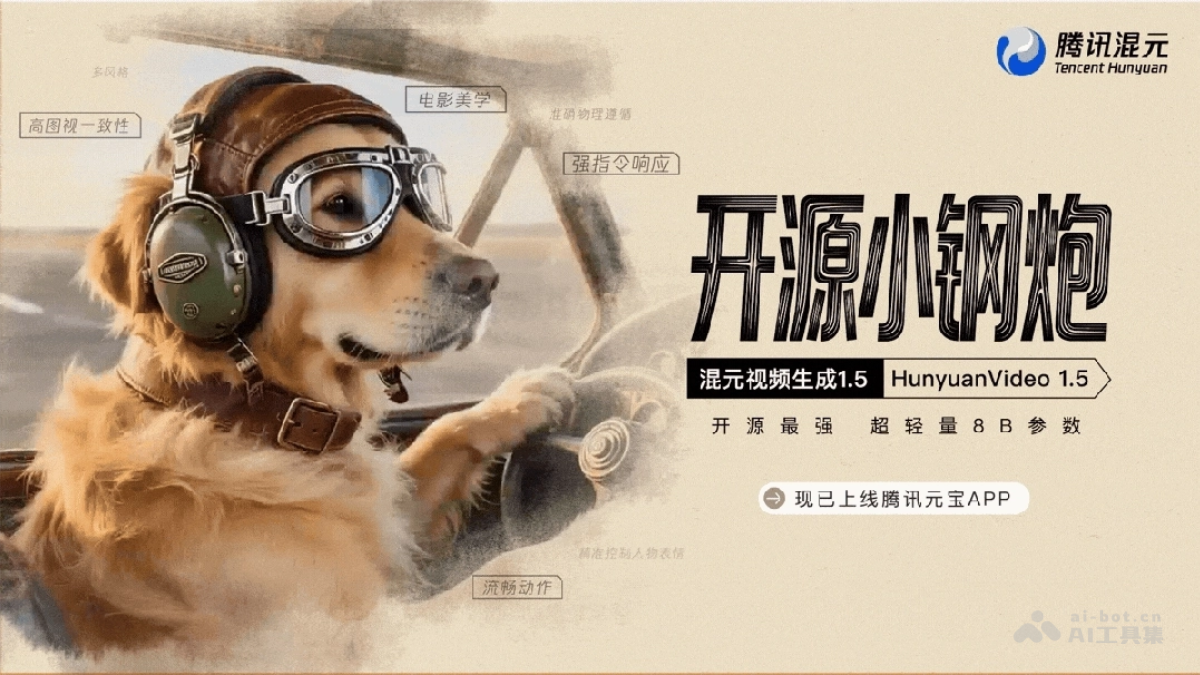
Main Features of HunyuanVideo 1.5
-
Text-to-Video: By inputting Chinese or English text descriptions, it directly generates high-definition videos matching the description, supporting precise parsing of complex semantics (such as lighting, composition, etc.).
-
Image-to-Video: Converts static images into dynamic videos, and the generated videos highly match the original image in color tone, lighting, scene, and details.
-
Diverse Styles: Supports multiple visual styles such as realistic, animation, and building blocks, and can generate Chinese and English text within videos to meet different creative needs.
-
High-Quality Visuals: Natively supports 480p and 720p high-definition video generation, and can be enhanced to 1080p cinematic quality through a super-resolution model.
-
Smooth Motion Generation: The generated people and objects move naturally and smoothly, following physical laws, and support various camera movements (such as push-pull, pan-tilt, orbit, etc.).
-
Strong Instruction Following: The model can accurately understand and follow complex instructions, generating diverse scenes that meet requirements, including camera movements, action combinations, etc.
-
Low Barrier to Use: The model's lightweight design enables smooth operation on consumer-grade GPUs with 14G VRAM, significantly lowering the hardware barrier.
Technical Principles of HunyuanVideo 1.5
- Architecture Design: The model is based on the Diffusion Transformer (DiT) architecture, integrating the advantages of Diffusion Models and the Transformer architecture. It adopts a 3D causal VAE codec to achieve efficient compression of 16x in space and 4x in time, stimulating strong performance with the minimum number of parameters.
- Attention Mechanism: It innovatively adopts the SSTA (Selective Sliding Tile Attention) mechanism, significantly reducing the computational overhead of long-sequence generation by dynamically pruning redundant spatiotemporal data, improving inference efficiency.
- Multimodal Understanding: It combines an enhanced multimodal large model and a dedicated text encoder to accurately parse Chinese and English instructions and strengthen the generation accuracy of text elements in videos.
- Training Strategy: It adopts a multi-stage progressive training strategy covering the entire process from pre-training to post-training, combined with the Moun optimizer to accelerate model convergence and optimize motion coherence, aesthetic quality, and human preference alignment.
- Super-Resolution Enhancement: It introduces a video super-resolution enhancement system that efficiently upsamples low-resolution videos to 1080p high-definition quality through a dedicated upsampling module in latent space, avoiding grid artifacts caused by traditional interpolation and improving image sharpness and texture.
- Inference Acceleration: Integrating key technologies such as model distillation and cache optimization, it greatly improves inference efficiency, significantly reduces inference resource consumption, and ensures smooth operation of the model on consumer-grade hardware.
HunyuanVideo 1.5 Project Address
- Project Website:https://hunyuan.tencent.com/video/
- GitHub Repository:https://github.com/Tencent-Hunyuan/HunyuanVideo-1.5
- HuggingFace Model Library:https://huggingface.co/tencent/HunyuanVideo-1.5
- Technical Paper:https://github.com/Tencent-Hunyuan/HunyuanVideo-1.5/blob/main/assets/HunyuanVideo_1_5.pdf
Application Scenarios of HunyuanVideo 1.5
- Film and Television Production: Quickly generate creative shots and scenes, assist screenwriters and directors in early-stage creative ideation, reduce filming costs, and improve creative efficiency.
- Advertising and Marketing: Generate attractive advertising videos, quickly produce product promotional short films, and enhance brand influence.
- Short Video Creation: Provide self-media creators with an efficient content generation tool to quickly generate interesting and novel short videos, meeting the content needs of social media platforms.
- Instructional Video Production: The model can generate vivid instructional animations or experimental demonstration videos, helping students understand complex concepts more intuitively and improving learning outcomes.