
What is HunyuanCustom
HunyuanCustom is a multimodal-driven customized video generation framework launched by the Tencent Hunyuan team. HunyuanCustom supports multiple input conditions such as images, audio, video, and text, and supports generating high-quality videos with specific subjects and scenes. By introducing a LLaVA-based text-image fusion module and an image ID enhancement module, HunyuanCustom significantly outperforms existing methods in identity consistency, realism, and text-video alignment. The framework supports audio-driven and video-driven video generation and is widely used in fields such as virtual human advertising, virtual try-on, and video editing, demonstrating strong controllability and flexibility.
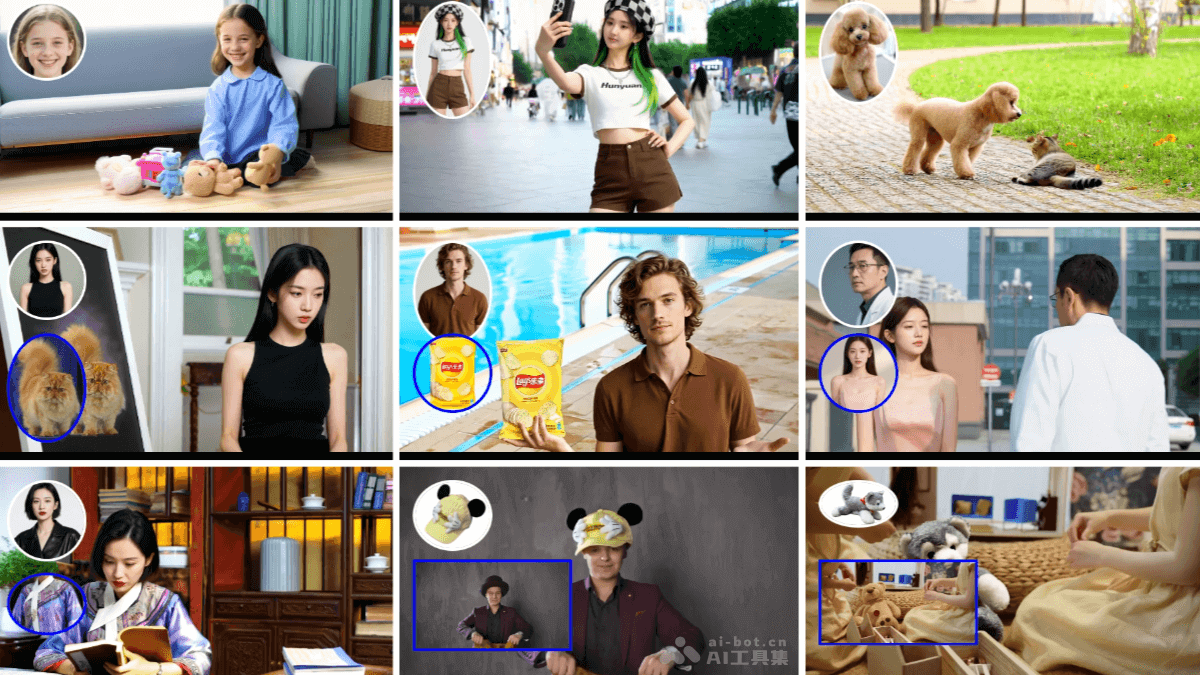
Main Features of HunyuanCustom
- Single-subject video customization: Generates videos based on input images and text descriptions, ensuring subject identity consistency.
- Multi-subject video customization: Supports interactive generation of multiple subjects, handling complex multi-subject scenarios.
- Audio-driven video customization: Generates videos based on audio and text descriptions, supporting flexible audio-driven animation.
- Video-driven video customization: Supports object replacement or addition based on video input, used in video editing and object replacement.
- Virtual human advertising and virtual try-on: Generates advertising videos of virtual humans interacting with products, or conducts virtual try-on displays.
- Flexible scene generation: Generates videos in different scenes based on text descriptions, supporting diverse content creation.
Technical Principles of HunyuanCustom
- Multimodal fusion module:
- Text-image fusion module: Based on LLaVA, fuses identity information in images with text descriptions to enhance multimodal understanding capabilities.
- Image ID enhancement module: Based on information concatenation along the timeline, uses the temporal modeling capability of the video model to strengthen subject identity features and ensure identity consistency in video generation.
- Audio-driven mechanism: The AudioNet module is based on a spatial cross-attention mechanism, injecting audio features into video features to achieve hierarchical alignment between audio and video, supporting audio-driven video generation.
- Video-driven mechanism: The video feature alignment module compresses the input video into latent space through VAE, and performs feature alignment based on the patchify module to ensure feature consistency with the noise latent variables.
- Identity decoupling module: Based on an identity-decoupled video conditioning module, efficiently injects video features into latent space, supporting video-driven video generation.
- Data processing and enhancement: Based on a strict preprocessing pipeline, including video segmentation, text filtering, subject extraction, and data augmentation, ensuring the high quality of input data and improving model performance.
Project Address of HunyuanCustom
- Project official website:https://hunyuancustom.github.io/
- GitHub repository:https://github.com/Tencent/HunyuanCustom
- HuggingFace model library:https://huggingface.co/tencent/HunyuanCustom
- arXiv technical paper:https://arxiv.org/pdf/2505.04512v1
Application Scenarios of HunyuanCustom
- Virtual human advertising: Generates advertising videos of virtual humans interacting with products, enhancing attractiveness.
- Virtual try-on: Upload photos to generate videos of trying on different clothing, improving the shopping experience.
- Video editing: Replace or add objects in a video to enhance editing flexibility.
- Audio-driven animation: Generate synchronized video animation based on audio, used in virtual live streaming or animation production.
- Educational videos: Combine text and images to generate instructional videos, improving learning outcomes.