
What is HunyuanDiT
HunyuanDiT (Hunyuan-DiT) is a high-performance text-to-image diffusion Transformer model open-sourced by the Tencent Hunyuan team. It possesses fine-grained Chinese and English understanding capabilities and can generate multi-resolution high-quality images based on text prompts. HunyuanDiT adopts an innovative network architecture, combining a bilingual CLIP and a multilingual T5 encoder, and is trained and optimized through a carefully designed data pipeline. It supports multi-turn dialogue and can generate and refine images based on context. In the field of Chinese-to-image generation, HunyuanDiT has reached a leading level among open-source models.
Main Features of HunyuanDiT
- Bilingual Text-to-Image Generation: HunyuanDiT can generate images based on Chinese or English text prompts, which gives it broad application potential in cross-lingual image generation tasks.
- Fine-Grained Understanding of Chinese Elements: The model is specially optimized for Chinese and can better understand and generate elements related to traditional Chinese culture, such as ancient Chinese poetry, traditional Chinese clothing, and Chinese festivals.
- Long Text Processing Capability: It supports text input of up to 256 tokens, enabling DiT to understand and generate images that match complex long-text descriptions.
- Multi-Size Image Generation: Hunyuan-DiT can generate high-quality images in various size ratios, meeting the needs of different uses from social media posts to large-size prints.
- Multi-Turn Dialogue and Context Understanding: Through multi-turn dialogue with users, HunyuanDiT can generate and iterate images based on dialogue history and contextual information, which enhances interactivity and creativity.
- High Consistency Between Images and Text: The images generated by Hunyuan-DiT are highly consistent in content with the input text prompts, ensuring that the images accurately reflect the intent and details of the text.
- Artistry and Creativity: HunyuanDiT can not only generate common images, but also capture creative descriptions in text and generate artistic and creative image works.
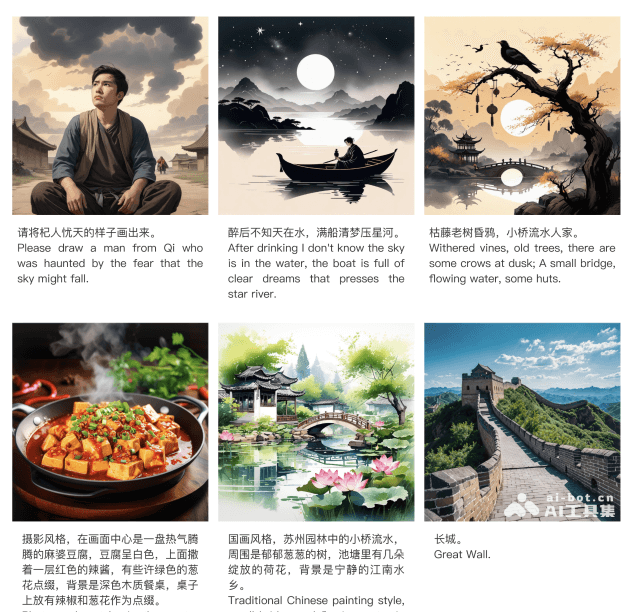
HunyuanDiT Official Website Entry
- Official Project Homepage:https://dit.hunyuan.tencent.com/
- Hugging Face Model:https://huggingface.co/Tencent-Hunyuan/HunyuanDiT
- GitHub Source Code:https://github.com/Tencent/HunyuanDiT
- Technical Report:https://tencent.github.io/HunyuanDiT/asset/Hunyuan_DiT_Tech_Report_05140553.pdf
Technical Architecture of HunyuanDiT
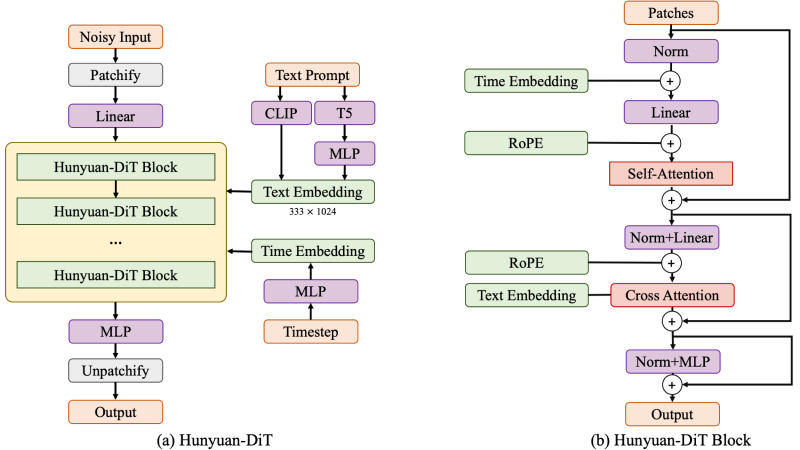
- Dual Text Encoders: HunyuanDiT combines a bilingual CLIP and a multilingual T5 encoder to enhance the understanding and encoding of input text. The CLIP model was chosen for its strong ability to associate images and text, while the T5 model was chosen for its capabilities in multilingual and text understanding.
- Variational Autoencoder (VAE): A pretrained VAE is used to compress images into a low-dimensional latent space, which helps the diffusion model learn the data distribution. The latent space of the VAE has an important impact on generation quality.
- Diffusion Model: Based on a diffusion Transformer, HunyuanDiT uses a diffusion model to learn the data distribution. The model combines text conditions with the diffusion model through a cross-attention mechanism.
- Improved Generator: The diffusion Transformer has several improvements over the baseline DiT, such as using adaptive layer normalization (AdaNorm) to strengthen the enforcement of fine-grained text conditions.
- Positional Encoding: HunyuanDiT uses Rotary Position Embedding (RoPE) to simultaneously encode absolute and relative position dependencies, supporting multi-resolution training and inference.
- Multimodal Large Language Model (MLLM): Used for the reconstruction of original captions for image-text pairs to improve data quality. The MLLM is fine-tuned to generate structured captions that include world knowledge.
- Data Pipeline: Includes data acquisition, interpretation, stratification, and application. The validity of new data is checked through an iterative process called "data fleet".
- Post-training Optimization: Optimization is performed during the inference stage to reduce deployment costs, including ONNX graph optimization, kernel optimization, operator fusion, etc.
Comparison of HunyuanDiT with Other Text-to-Image Models
To comprehensively compare the generation capabilities of HunyuanDiT with other models, the Hunyuan team constructed test sets across 4 dimensions, with more than 50 professional evaluators conducting the evaluation, including text-image consistency, exclusion of AI artifacts, subject clarity, and aesthetics.
| Model | Open Source | Text-Image Consistency (%) | Exclusion of AI Artifacts (%) | Subject Clarity (%) | Aesthetics (%) | Overall Score (%) |
|---|---|---|---|---|---|---|
| SDXL | ✔ | 64.3 | 60.6 | 91.1 | 76.3 | 42.7 |
| PixArt-α | ✔ | 68.3 | 60.9 | 93.2 | 77.5 | 45.5 |
| Playground 2.5 | ✔ | 71.9 | 70.8 | 94.9 | 83.3 | 54.3 |
| SD 3 | ✘ | 77.1 | 69.3 | 94.6 | 82.5 | 56.7 |
| Midjourney v6 | ✘ | 73.5 | 80.2 | 93.5 | 87.2 | 63.3 |
| DALL-E 3 | ✘ | 83.9 | 80.3 | 96.5 | 89.4 | 71.0 |
| Hunyuan-DiT | ✔ | 74.2 | 74.3 | 95.4 | 86.6 | 59.0 |