
What is HumanDiT
HumanDiT is a pose-guided high-fidelity humanvideo generationframework jointly proposed by Zhejiang University and ByteDance. Based on the Diffusion Transformer (DiT), it can be trained on large-scale datasets to generate long-sequence human motion videos with fine body rendering. The core advantage of HumanDiT lies in its pose guidance mechanism, which generates subsequent pose sequences through the Keypoint-DiT, ensuring the coherence and naturalness of human movements in the video. It introduces a prefix latent reference strategy to maintain personalized features in long sequences. HumanDiT supports multiple video resolutions and variable sequence lengths, making it suitable for long-sequence video generation. It achieves pose transfer for a given sequence based on a pose adapter, further improving the accuracy of pose alignment.
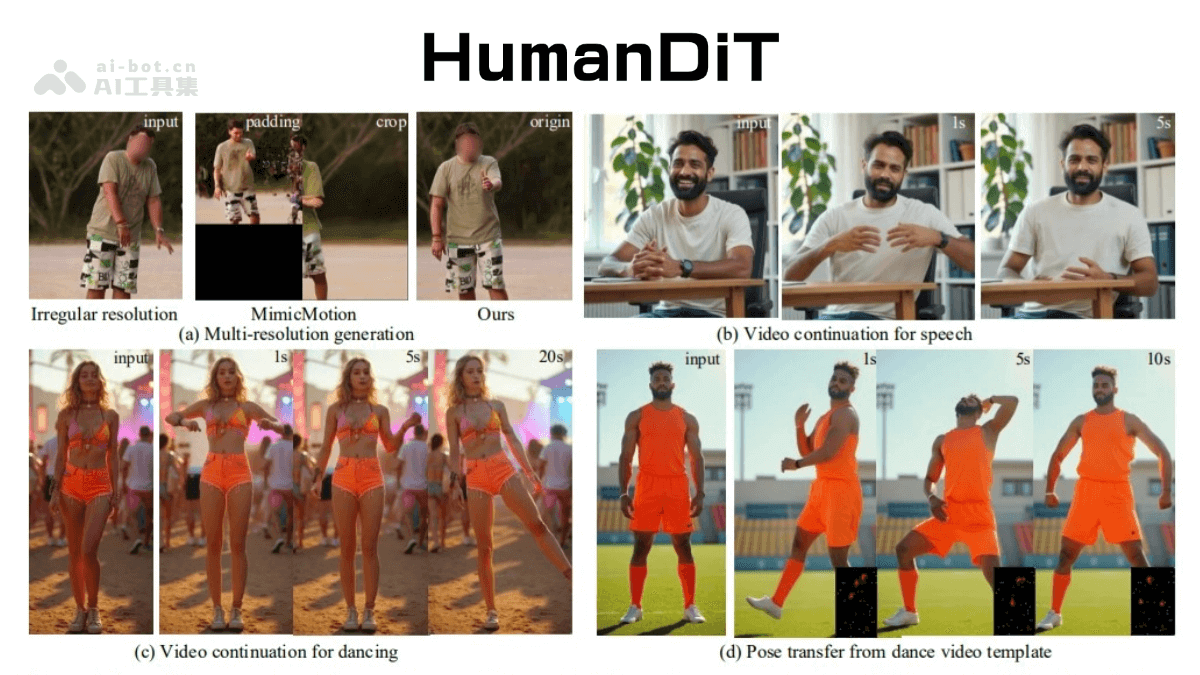
HumanDiT's Main Features
- Pose-Guided Video Generation: HumanDiT generates subsequent pose sequences based on the Keypoint-DiT, ensuring the coherence and naturalness of human movements in the video.
- Long-Sequence Video Generation: Supports multiple video resolutions and variable sequence lengths, making it suitable for generating high-quality long-sequence videos.
- Personalized Feature Preservation: Through the prefix latent reference strategy, personalized features are maintained in long sequences.
- Flexible Input and Output: Can continue generating videos from static images or existing videos, making it suitable for a variety of application scenarios.
- Pose Adaptation and Refinement: Achieves pose transfer for a given sequence based on a pose adapter, and enhances the alignment of facial and hand features with the reference image through a pose refinement module.
HumanDiT's Technical Principles
- Pose Guidance and Diffusion Transformer: HumanDiT generates videos in a pose-guided manner, generating subsequent pose sequences during inference based on the Keypoint-DiT. This ensures the coherence and naturalness of human movements in the video, while the Diffusion Transformer can handle videos of different resolutions and sequence lengths.
- Prefix Latent Reference Strategy: To maintain personalized features in long-sequence video generation, HumanDiT introduces a prefix latent reference strategy. The strategy uses the first frame of the video as a noise-free prefix latent vector for the model to reference during generation, maintaining visual consistency.
- Pose Adapter and Pose Refinement Module: HumanDiT uses a pose adapter to achieve pose transfer for a given sequence, and further optimizes the generated pose sequence through a pose refinement module. This helps improve the generation quality of detailed parts such as the face and hands, ensuring alignment with the reference image.
- Large-Scale Dataset Training: HumanDiT is trained on a large dataset containing 14,000 hours of high-quality videos. The data is collected through a structured data processing pipeline, covering a variety of human action scenarios. This enables the model to learn rich motion priors and demonstrate strong generalization ability during inference.
HumanDiT's Project Address
- Project Website:https://agnjason.github.io/HumanDiT-page/
- arXiv Technical Paper:https://arxiv.org/pdf/2502.04847
HumanDiT's Application Scenarios
- Virtual Humans: HumanDiT can be used to generate dynamic videos of virtual humans, with more natural and smooth movements. In virtual customer service scenarios, the virtual human can generate corresponding movements and expressions in real time based on the user's questions, providing a more vivid and realistic interactive experience.
- Animated Films: HumanDiT can generate high-quality, long-sequence human motion videos, and can be used to generate motion sequences for animated characters, helping animators quickly generate high-quality motion clips and improve production efficiency.
- Immersive Experience: HumanDiT can be used to build virtual characters and motions in immersive experiences. In immersive VR experiences, HumanDiT can generate human motions and expressions that match the scene, allowing participants to feel a more real and vivid experience.
- Video Generation and Continuation: It can generate video from a single image, or continue generating subsequent content from an existing video.