
What is HuatuoGPT-o1
HuatuoGPT-o1 is a complex reasoning model developed for the medical field, jointly launched by The Chinese University of Hong Kong, Shenzhen and the Shenzhen Research Institute of Big Data. It improves performance in solving medical problems based on complex reasoning capabilities. The model is implemented using a two-stage training method: first, a medical verifier is used to guide the search for correct reasoning paths to fine-tune the model; second, reinforcement learning based on verifier feedback is applied to further enhance the model's complex reasoning capabilities. HuatuoGPT-o1 can generate long chains of thought, identify errors, and try different strategies to refine answers. Experimental results show that the model outperforms general and medical-specific baseline models on multiple medical benchmarks and significantly benefits from complex reasoning and reinforcement learning.
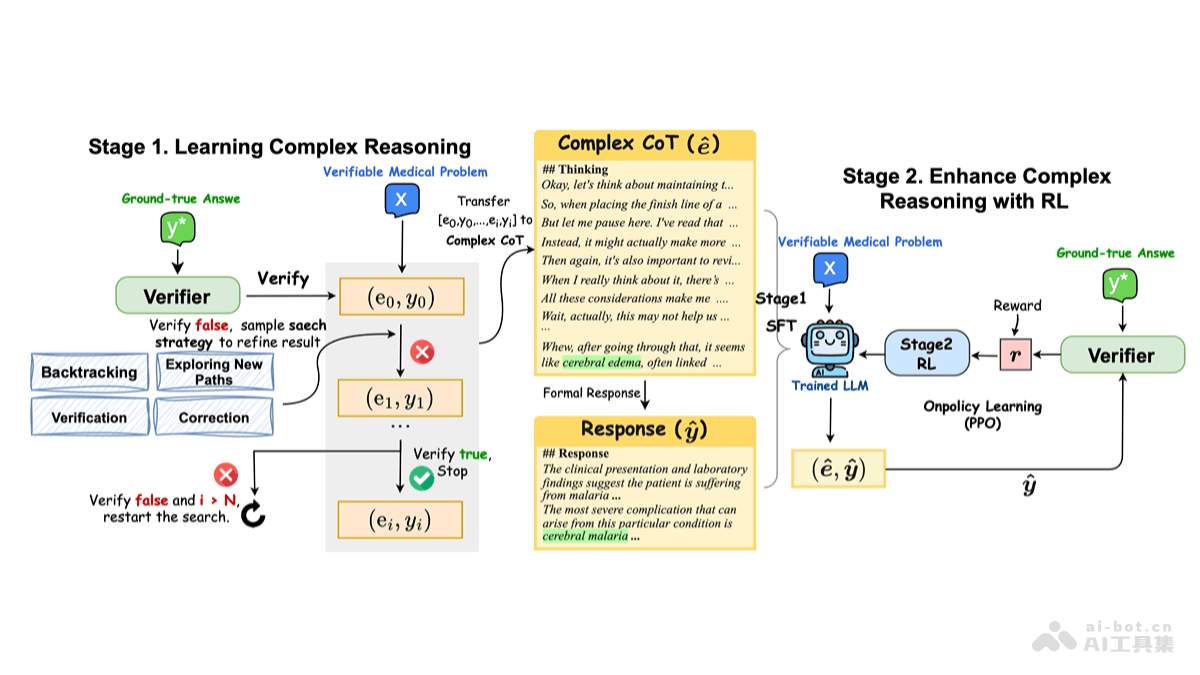
Main Features of HuatuoGPT-o1
- Complex Reasoning: HuatuoGPT-o1 can perform complex reasoning to solve complex problems in the medical field.
- Error Identification and Correction: The model can identify errors in its answers and try different strategies to correct and optimize answers.
- Long Chain of Thought: HuatuoGPT-o1 can generate long chains of thought (Chain-of-Thought, CoT), displaying the reasoning process.
- Self-Improvement: Based on reinforcement learning (Reinforcement Learning, RL), the model can self-improve and further enhance complex reasoning capabilities.
Technical Principles of HuatuoGPT-o1
- Two-Stage Training Method:
- Stage 1: Learning Complex Reasoning: Construct complex reasoning trajectories based on verifier feedback (correct or incorrect) guided by policy search, and fine-tune the LLM.
- Stage 2: Enhancing Complex Reasoning through RL: After acquiring complex reasoning skills in the first stage, further optimize the model using sparse rewards based on the verifier.
- Verifiable Medical Questions: Construct 40K verifiable medical questions with objective, unique correct answers, supporting the model in verifying the correctness of solutions.
- Medical Verifier: Use GPT-4o as a verifier to check whether the model-generated answers (CoT and results) match the true answers, providing binary feedback.
- Reinforcement Learning (RL): Use the Proximal Policy Optimization (PPO) algorithm for RL training, guiding the model's self-improvement based on rewards provided by the verifier, and optimizing complex reasoning paths.
- Chain-of-Thought (CoT): The CoT generated by the model includes three parts: "internal thinking", "final conclusion", and "verification", simulating the way humans solve problems.
HuatuoGPT-o1 Project Address
- GitHub Repository:https://github.com/FreedomIntelligence/HuatuoGPT-o1
- HuggingFace Model Library:https://huggingface.co/collections/FreedomIntelligence/huatuogpt-o1
- arXiv Technical Paper:https://arxiv.org/pdf/2412.18925
Application Scenarios of HuatuoGPT-o1
- Medical Diagnosis Assistance: Assist doctors in disease diagnosis by analyzing patients' symptoms, signs, and laboratory test results to provide possible diagnostic suggestions.
- Treatment Plan Formulation: Help doctors formulate personalized treatment plans, taking into account patients' specific conditions and the latest medical research.
- Medical Education and Training: Serve as a teaching aid in medical education to help students understand complex medical concepts and reasoning processes.
- Medical Research: Supports medical researchers in conducting complex reasoning during literature review and data analysis, accelerating the research process.
- Drug Development Consultation: During the drug development process, provides consultation on drug mechanisms of action, side effects, and clinical trial design.