
What is HelloBench
HelloBench is an open-source benchmark for evaluating the long-text generation capabilities of large language models (LLMs). HelloBench includes five subtasks based on Bloom's taxonomy: open-ended question answering, summarization, chat, text completion, and heuristic text generation. HelloBench uses real-world scenario data, such as Quora and Reddit, to ensure the diversity and practicality of the tasks. It introduces HelloEval, an efficient evaluation method that reduces the burden of human evaluation while maintaining a high correlation with human ratings. Experiments of HelloBench on multiple LLMs show that existing models face challenges in generating long texts exceeding 4,000 words.
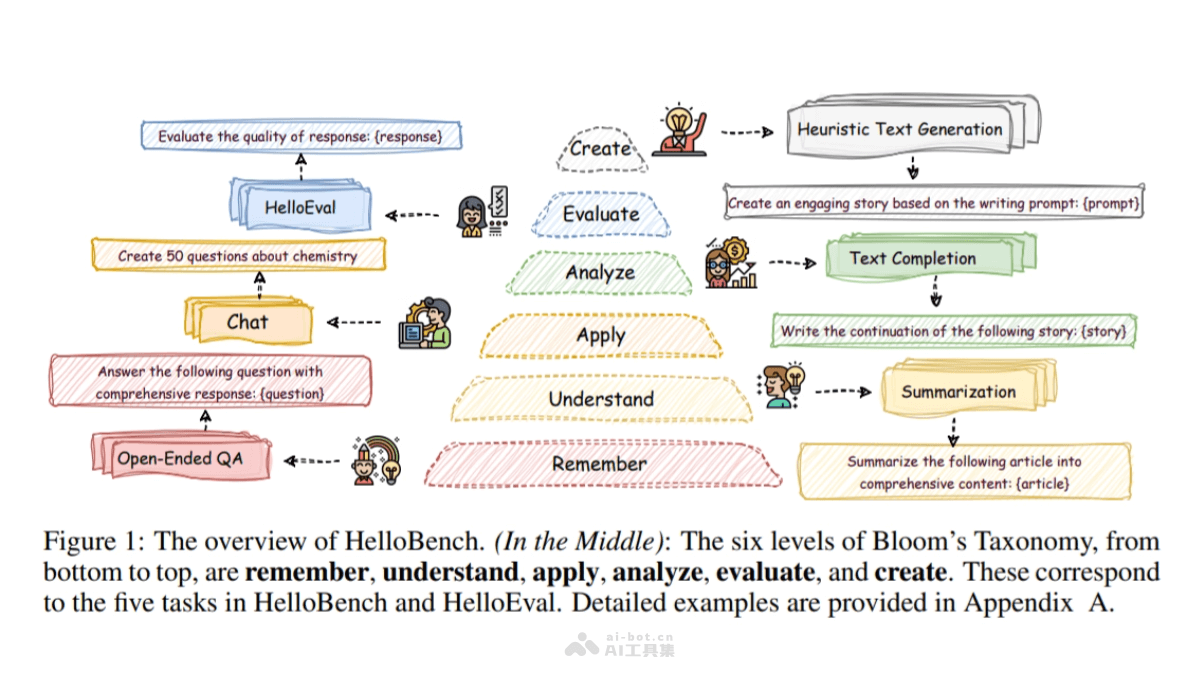
Main Features of HelloBench
- Hierarchical Task Design: HelloBench divides long-text generation tasks into five subtasks according to Bloom's taxonomy, with each subtask targeting different language model capabilities.
- Real-World Datasets: Datasets are built based on real data from platforms such as Quora and Reddit, ensuring the practicality and diversity of the evaluation.
- Automated Evaluation: The HelloEval method is used to automatically evaluate the long-text generation capabilities of LLMs, reducing the time and effort required for human evaluation.
- Comparison of Evaluation Methods: It compares with traditional evaluation metrics (such as ROUGE and BLEU) to demonstrate the correlation between HelloEval and human evaluation.
Technical Principles of HelloBench
- Bloom's Taxonomy: Based on Bloom's taxonomy, long-text generation tasks are divided into different levels corresponding to different levels of cognitive complexity.
- Dataset Construction: Internet data is manually collected and screened to build high-quality and diverse datasets.
- HelloEval Evaluation Method: Checklists are designed and human annotation data is collected, and linear regression analysis is used to determine the weighted scores of the checklists.
- LLM-as-a-Judge: Based on language models as evaluators, it answers checklist questions and evaluates the quality of the generated text.
- Linear Regression Analysis: Linear regression analysis is performed on manually annotated data to obtain weighted scores aligned with human evaluation.
- Error Pattern Analysis: It analyzes common errors of LLMs in long-text generation and identifies the limitations of the models.
Project Address of HelloBench
- GitHub Repository:https://github.com/Quehry/HelloBench
- HuggingFace Model Library:https://huggingface.co/papers/2409.16191
- arXiv Technical Paper:https://arxiv.org/pdf/2409.16191
Application Scenarios of HelloBench
- Language Model Development: Developers use HelloBench to evaluate and compare the performance of different language models on long-text generation tasks.
- Academic Research: Researchers use HelloBench to conduct experiments related to long-text generation, publish academic papers, or carry out further research.
- Product Testing: When developing new AI products or services, enterprises use HelloBench to test and optimize the text generation capabilities of their products.
- Educational Assessment: Educational institutions use HelloBench to evaluate and improve the text generation quality of teaching assistance tools.
- Content Creation: Content creators use HelloBench to evaluate and improve automatic content generation tools, such as automatic writing and blog post generation.
- Dialogue Systems: Evaluate and improve the performance of chatbots or virtual assistants in long conversations.