
What is HappyHorse
HappyHorse is a mysterious AI model that appeared out of nowhere at the top of the Artificial Analysis video generationblind test leaderboard, leading Seedance 2.0 by a wide margin with an Elo score of 1347, taking first place in both text-to-video and image-to-video. The model is suspected to be the work of Alibaba Taotian's Future Life Lab (led by Zhang Di, former head of Kling), adopting a 40-layer single-stream Transformer architecture that can generate high-quality videos in just 8 denoising steps. The model currently remains anonymous and is regarded as a phenomenal dark horse in the AI video field in 2026.
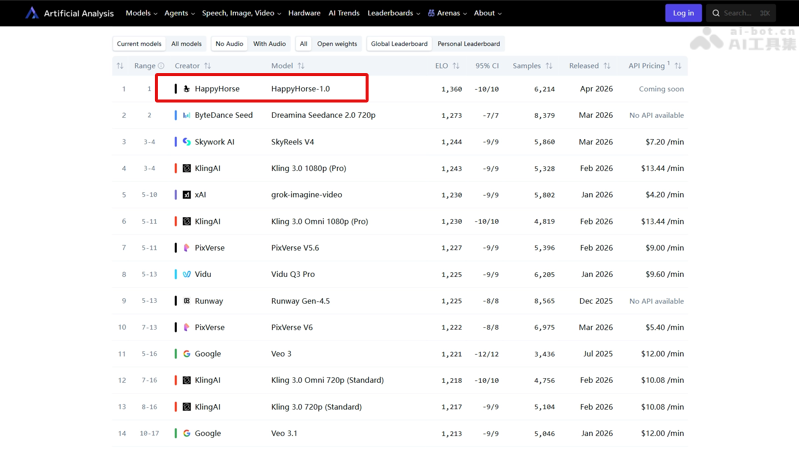
HappyHorse's main features
- Text-to-video: HappyHorse supports generating high-quality cinematic videos from text prompts, ranking first globally on the text-to-video blind test leaderboard with an Elo score of 1347.
- Image-to-video: The model can generate dynamic video content based on reference images, setting a new all-time high score record in the image-to-video category with 1391 points.
- Video-to-video: HappyHorse provides video-to-video editing features, allowing users to perform style transfer or content reconstruction on existing videos.
- Audio-video coordination: The model has native audio generation capabilities, can synchronously output sound effects matching the visuals, and ranks second globally in the combined video + audio ranking.
- HD output: Supports 1080p HD video export, providing watermark-free, commercially usable video generation services.
- Reference image workflow: Users can maintain character or scene consistency through the reference image workflow, achieving more precise video content control.
How to use HappyHorse
- Visit Artificial Analysis: Visit the Artificial Analysis official website https://artificialanalysis.ai/,进入 Video Arena blind test section.
- Participate in blind test voting: The system will randomly display two videos generated by anonymous models (possibly including HappyHorse). Users choose the better work based on image quality, motion smoothness, etc., by clicking "A is better" or "B is better".
- View model identity: After voting, the page will show which model each of the two videos came from. If HappyHorse is among them, you can see its generation results.
Artificial Analysis only provides comparison and evaluation functions; you cannot input custom prompts to generate videos.
- Experience channels:
- VisitDuiyouofficial website; HappyHorse debuts on the Duiyou platform.
- VisitLibTVofficial website to use it first HappyHorse。
- VisitQianwen APP, select the model to use it.
Key information and usage requirements of HappyHorse
- Identity: An anonymous AI video generation model that appeared out of nowhere at the top of both Artificial Analysis leaderboards, suspected to be the work of Alibaba Taotian's "Future Life Lab" (led by Zhang Di, former head of Kling)
- Architecture: Adopts a 40-layer single-stream Transformer, 8-step denoising, and a Transfusion unified multimodal architecture that combines diffusion models and autoregression
- Performance: Text-to-video 1347 points, image-to-video 1391 points (Elo scores), leading Seedance 2.0 by nearly 60-74 points
- Features: Text-to-video, image-to-video, video-to-video, native audio synchronization, excels at character consistency, physical logic, and lip synchronization
HappyHorse's Core Advantages
- Generation quality with a runaway lead on blind test leaderboards: In Artificial Analysis's real-user blind tests, it topped both leaderboards with an Elo score of 1347 for text-to-video and 1391 for image-to-video, leading the runner-up Seedance 2.0 by nearly 60-74 points, equivalent to the sum of the score gaps from second place to nineteenth place.
- Minimalist, brute-force single-stream architecture: It uses a 40-layer single-stream Transformer to uniformly process text, video, and audio tokens, abandoning complex multi-stream structures. Generation can be completed with 8 denoising steps and requires no CFG guidance, significantly reducing inference costs.
- Native audio-video collaborative generation: It supports synchronous generation of native sound effects matching the visuals, ranking second globally in combined video + audio, achieving highly aligned sound and picture.
- Commercial-grade character consistency: It performs outstandingly in facial expressions, lip sync, body movements, and physical logic simulation, making it especially suitable for commercial scenarios with strict character consistency requirements, such as virtual humans and short dramas.
Comparison of HappyHorse with Similar Competitors
| Comparison Dimension | HappyHorse-1.0 | Seedance 2.0(Jimeng) | Kling 3.0(Kling) |
|---|---|---|---|
| Blind Test Ranking | Text-to-video/Image-to-videoFirst on both leaderboards(1347/1391 points) | Text-to-video/Image-to-videoSecond on both leaderboards(1273/1356 points) | Ranked 4th-5th (1241 points) |
| Company | Suspected Alibaba Taotian"Future Life Lab" (Zhang Di's team) | ByteDance(Jimeng/Jianying team) | Kuaishou(Kling AI team) |
| Core Architecture | 40-layer single-stream Transformer,8-step denoising, no CFG | Specific architecture not disclosed; speculated to be multi-stream DiT | Omni multimodal architecture, multi-step denoising |
| Audio Generation | Native audio sync, ranked in audio leaderboardSecond | Native audio sync, ranked in audio leaderboardFirst | Supports audio, but ranks lower |
| Usage Cost | $0.83-$1.24/100 credits (about $0.05/second) | Domestic premium membership 499 yuan/month(after price increase) | $13.44/minute (Pro version) |
| Availability Status | Available on official website, API "Coming soon" | No API, requires queueing, domestic free quota is tight | API available, but relatively expensive |
HappyHorse's Application Scenarios
- Virtual human and digital human production: The model has significant advantages in facial performance, lip sync, and body movements, making it suitable for commercial scenarios requiring high character consistency, such as virtual streamers, digital human short videos, and AI endorsements.
- AI short dramas and film/TV creation: It supports generating continuous footage with a cinematic quality and excels at multi-shot storytelling and character movement continuity, making it suitable for producing film and television content such as AI short dramas, commercials, and trailers.
- Physical logic demonstration and product display: The model can accurately simulate physical interactions (such as a hula hoop rolling, a rubber band ball bouncing, liquid being poured into coffee, etc.), suitable for product feature demonstrations, educational popular science videos, and creative content for physics engines.
- Audio-video synchronized content: The model can create immersive videos with ambient sound effects and character dialogue, suitable for audio-visual collaborative scenarios such as audio stories, ASMR content, and dubbing clips.