
What is GroundingBooth
GroundingBooth is an advanced text-to-image customization framework jointly launched by research teams from Washington University in St. Louis, Adobe, and Purdue University. Based on a text-image alignment module and masked cross-attention layers, it achieves precise spatial alignment of foreground subjects and background objects. The framework can generate images that meet personalized needs in terms of layout, identity preservation, and text-image coherence, supports multi-subject customization, and maintains high accuracy in complex scenes. GroundingBooth is the first work to achieve joint grounding of subject-driven foreground generation and text-driven background generation, making highly customized visual content creation possible.
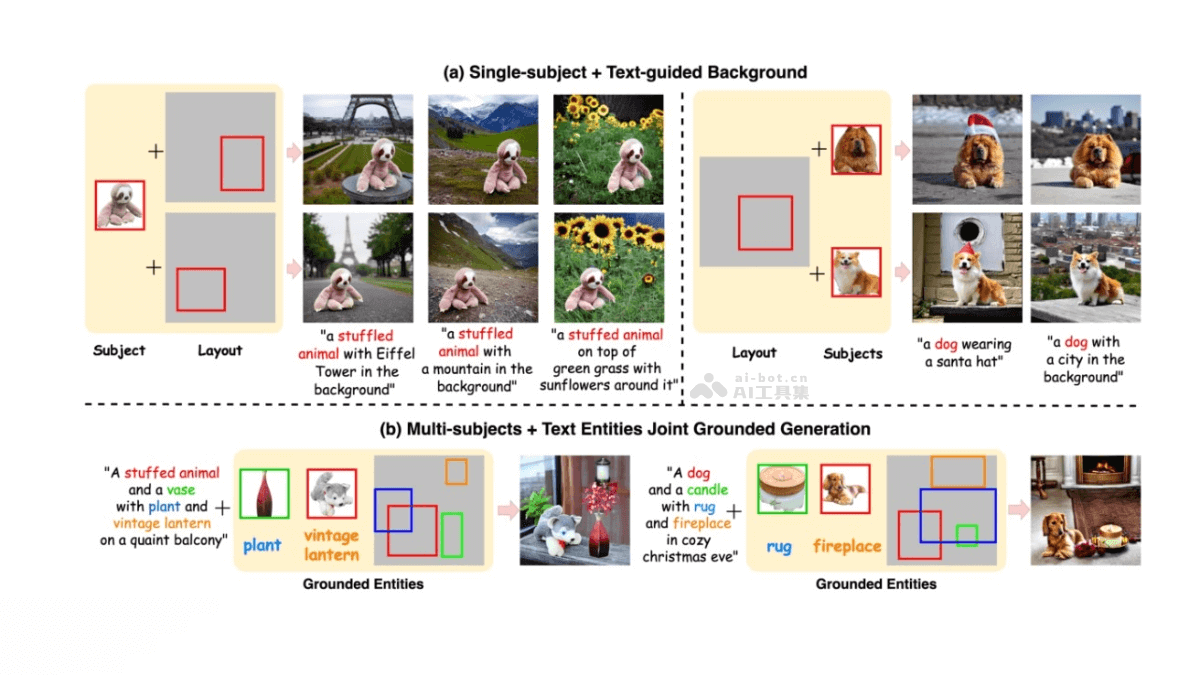
Main Features of GroundingBooth
- Single-subject customization: Generates customized images matching the user-provided text description and a single subject image.
- Joint customization of multiple subjects and text entities: Supports simultaneous customization of multiple subjects and text entities, generating complex images containing multiple objects and text-described content.
- Spatial alignment: Ensures that objects in the generated image are spatially consistent with the input layout information.
- Identity preservation: Preserves the identity features of subjects during image generation.
- Text-image alignment: Ensures that the generated image content is consistent with the text description.
Technical Principles of GroundingBooth
- Feature extraction: Uses the CLIP text encoder and the DINOv2 image encoder to extract feature embeddings for text and images, respectively.
- Grounding module: Combines text and image features with the input layout information through positional encoding to generate grounding tokens.
- Masked cross-attention layers: Uses masked cross-attention layers in each Transformer block of the U-Net to control the combination of foreground and background features, ensuring the accuracy of feature injection.
- Precise layout control: Achieves precise control over the size and position of objects in the generated image through masked cross-attention layers in the training and inference stages.
- Model training: During the training stage, the model learns how to generate accurate image layouts based on text descriptions and reference objects.
- Model inference: During the inference stage, the model processes multiple reference objects and achieves multi-subject customization through duplicated masked cross-attention layers.
- Avoiding context mixing: Distinguishes subject-driven foreground generation from text-driven background generation to avoid context confusion during the generation process.
Project Address of GroundingBooth
- Project website:groundingbooth.github.io
- arXiv technical paper:https://arxiv.org/pdf/2409.08520v1
Application Scenarios of GroundingBooth
- Personalized product customization: Users can generate customized product images according to their preferences, such as customized T-shirts, mugs, phone cases, etc., printed with specific patterns or text.
- Artistic creation: Artists and designers use GroundingBooth to generate artworks with specific styles and elements.
- Game design: Game developers can quickly generate personalized characters, scenes, or items in games based on this framework.
- Advertising and marketing: Marketers create custom images that match ad copy, enhancing the appeal of advertisements.
- Social Media Content Creation: Users share customized images on social media, with the images related to a specific topic or event.
- Educational and Training Materials: Educators generate instructional images with specific information and layouts, improving the appeal and effectiveness of learning materials.