
What is Goku
Goku is the latest jointly released by the University of Hong Kong and ByteDancevideo generationmodel, designed for joint generation of images and videos. Based on an advanced rectified flow Transformer framework, it supportstext-to-video, image-to-video, and text-to-image, among other modes. Goku's core advantages include high-quality video generation capabilities and extremely low advertising video production costs (100 times lower than traditional methods). Goku is based on large-scale high-quality datasets and efficient training facilities. The researchers built a dataset containing about 36 million videos and 160 million images, using multimodal large language models to generate contextually consistent frameworks. Goku adopts advanced parallel strategies and fault-tolerance mechanisms to ensure the efficiency and stability of the training process.
Goku+ is an extended version launched based on the Goku model, focused on advertising video creation. It can quickly generate high-quality advertising videos, supports video generation of more than 20 seconds, and features stable hand movements and rich facial and body expressions. Goku+ can transform product images into attractive videos and supports virtual digital humans interacting with products, enhancing advertising appeal. It is suitable for various scenarios such as e-commerce, brand promotion, short video advertising, and product displays, and can significantly reduce advertising production costs and improve creative efficiency.
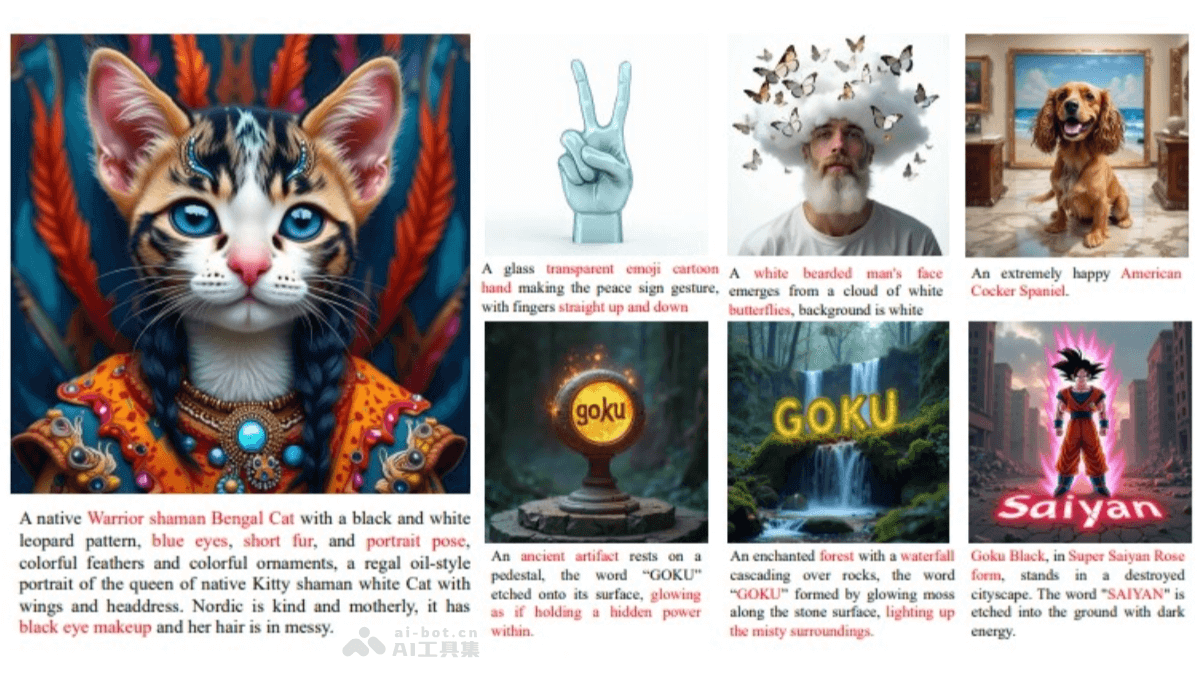
Goku's main features
- Text-to-Image:Generate high-quality images based on text descriptions, capable of generating richly detailed images that are highly consistent with the text descriptions.
- Text-to-Video: Generate coherent videos based on text descriptions, with the generated videos having smooth motion and high-quality visuals.
- Image-to-Video: Generate videos based on images, maintaining the visual style and semantic consistency of the images. It can generate dynamic videos from static images and is suitable for animation and video content creation.
- Advertising video generation (Goku+): Generate high-quality advertising videos and support natural interaction between people and products. It can reduce the production cost of advertising videos by 100 times, and the generated videos have stable hand movements and rich facial expressions.
- Virtual digital human video generation: Generate videos of virtual digital humans with a high degree of realism and natural movements, suitable for scenarios such as virtual anchors and virtual customer service.
- Multimodal generation: Support generation tasks across multiple modalities, including joint generation of images, videos, and text. Through a shared latent space and full attention mechanism, Goku can seamlessly handle the complex spatiotemporal dependencies of images and videos.
Goku's technical principles
- Joint image-video VAE: Goku uses a 3D joint image-video variational autoencoder (VAE) to compress image and video inputs into a shared latent space. This enables the model to handle multiple media formats, including images and videos, and perform representation within a unified framework.
- Transformer architecture: The Goku model family includes Transformer architectures with 2B and 8B parameters. The architecture is based on a full attention mechanism and can effectively handle the complex spatiotemporal dependencies of images and videos, achieving high-quality, coherent output.
- Rectified flow formulation: Based on the Rectified Flow (RF) algorithm, Goku trains between the prior distribution and the target data distribution through linear interpolation. Compared with traditional diffusion models, it shows faster convergence speed and stronger theoretical properties.
- Multi-stage Training Strategy: Goku adopts a multi-stage training strategy, including image-text semantic alignment pre-training, joint image-video training, and fine-tuning for different modalities. It gradually improves the model's generation capabilities and ensures efficient training on large-scale datasets.
- Large-scale High-quality Dataset: The researchers built a large-scale dataset of approximately 36 million videos and 160 million images, using a variety of data filtering and enhancement techniques to improve data quality. The dataset provides rich material for model training.
- Efficient Training Infrastructure: Goku's training infrastructure includes parallel strategies, fine-grained activation checkpointing techniques, fault-tolerance mechanisms, and ByteCheckpoint technology. It significantly improves training efficiency and stability.
Goku's Project Address
- Project Website:https://saiyan-world.github.io/goku/
- Github Repository:https://github.com/Saiyan-World/goku
- HuggingFace Model Library:https://huggingface.co/datasets/saiyan-world/Goku
- arXiv Technical Paper:https://arxiv.org/pdf/2502.04896
Goku's Application Scenarios
- Advertising Video Production: Goku+ can generate high-quality advertising videos based on text descriptions, supporting direct video generation from text, character interaction video generation from product images, and product showcase video generation.
- Virtual Digital Human Video Generation: Goku+ can convert text into surreal human videos, generating videos longer than 20 seconds, with stable hand movements and highly expressive facial and body movements.
- Content Creation: Goku can generate videos of various scenes, including animation, natural scenery, and animal behavior. It can generate a video of a fashionable woman strolling through the streets of Tokyo, or a scene of several giant mammoths walking on snow. It provides art creators with rich inspiration and creative material.
- Education and Training: Goku can be used to produce educational videos and training courses. By generating vivid video content, it improves the effectiveness and fun of education and training.
- Entertainment Industry: In the entertainment industry, such as film, television, and animation, Goku can be used for content production and special effects generation. It can generate high-quality video content, providing creators with more possibilities.