
What is GLM-Image
GLM-Image is a new-generation multimodalimage generationmodel open-sourced by Zhipu in collaboration with Huawei. It is trained on Ascend Atlas 800T A2 devices and the MindSpore framework, making it the first SOTA model trained entirely on domestic chips. The model adopts a hybrid "autoregressive + diffusion decoder" architecture, combining a 9B autoregressive model and a 7B diffusion decoder to balance global semantic understanding and high-frequency detail generation, and it particularly excels at text rendering and knowledge-intensive scenarios. It ranks first among open-source models on the CVTG-2K and LongText-Bench leaderboards, supports image generation at multiple resolutions, and features high cost-effectiveness and fast speed, providing an important reference for the development of domestic open-source image generation models.
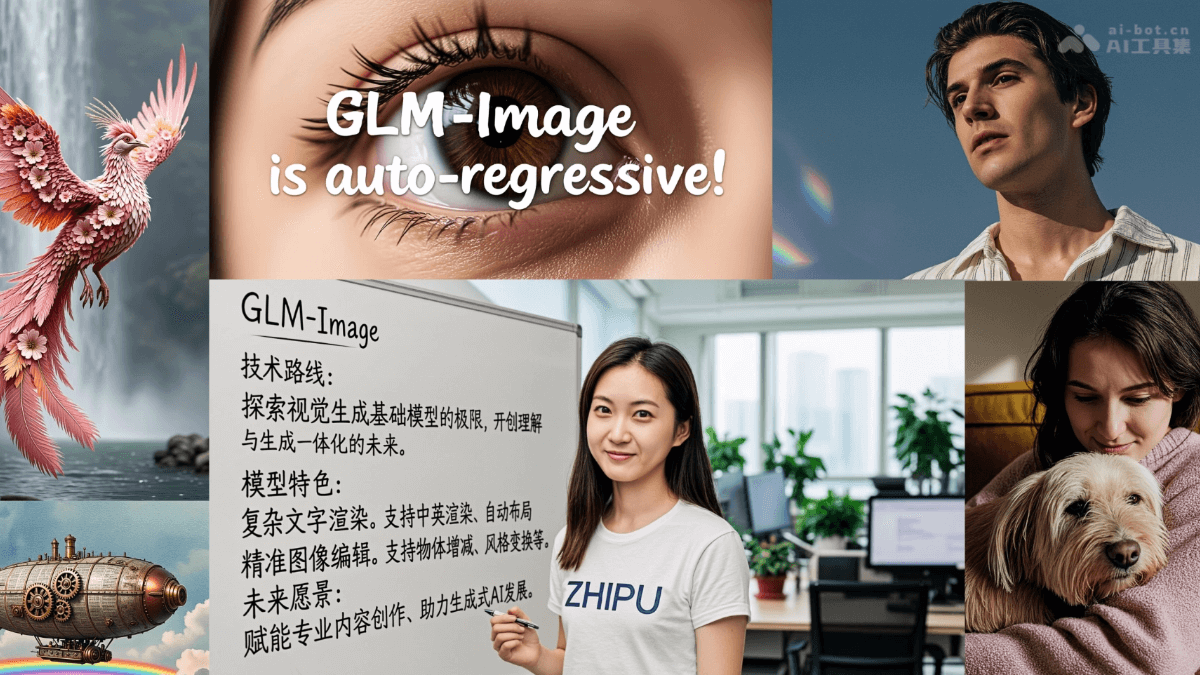
Main Features of GLM-Image
-
High-Quality Image Generation: The model can generate high-resolution images (up to 2048×2048), covering various scenarios such as portraits, landscapes, and still life.
-
Complex Text Rendering: GLM-Image particularly excels at generating complex text content within images, supports multi-region text generation, and is suitable for knowledge-intensive scenarios such as posters, PPTs, and popular science illustrations.
-
Multi-Task Support: GLM-Image supports various image-to-image tasks, including image editing, style transfer, and multi-subject consistent generation.
-
Multi-Resolution Adaptability: The model can adaptively handle image generation tasks at different resolutions without retraining, offering high flexibility.
Technical Principles of GLM-Image
-
Autoregressive Module: The modelis based on a 9B-parameter autoregressive model, responsible for global semantic understanding and low-frequency layout information of images.Through joint training of text-to-image and image-to-image, it enhances the ability to understand complex instructions.The model uses MRoPE (Multi-Dimensional RoPE) as positional embedding, supporting interleaved generation of images and text.
-
Diffusion Decoder: The modelis based on a 7B-parameter DiT (Diffusion Transformer) structure, focusing on the generation of high-frequency details such as text strokes and fine textures in images.It combines semantic VQ (Vector Quantization) Tokens and VAE (Variational Autoencoder) latent representations to achieve the fusion of semantic information and high-frequency details. The modelintroduces the Glyph-byT5 model to perform character-level encoding on text regions, improving the accuracy of text generation.
-
Training and Optimization:The entire process is completed on Ascend Atlas 800T A2 devices based on the MindSpore framework, verifying the feasibility of domestic chips in high-performance model training. The modeladopts dynamic graph multi-level pipeline optimization and multi-stream parallel strategies to improve training efficiency and performance.The reinforcement learning optimization module separately optimizes the autoregressive generator and the diffusion decoder, improving semantic consistency and visual detail quality.
Project Address of GLM-Image
- Project Official Website:https://z.ai/blog/glm-image
- GitHub Repository:https://github.com/zai-org/GLM-Image
- HuggingFace Model Library:https://huggingface.co/zai-org/GLM-Image
Application Scenarios of GLM-Image
-
Popular Science Illustration and Education: GLM-Image can generate popular science illustrations containing complex logic and textual explanations, helping to present educational content intuitively.
-
Multi-Panel Pictures and Comics: The model is suitable for generating multi-panel images such as e-commerce images and comics, maintaining consistent style and accurately generating text in multiple places.
-
Social Media and Content Creation: The model can quickly generate social media covers, creative advertising images, etc., supports complex image-text layouts, and enhances content appeal.
-
Commercial Posters and Promotion: The model can generate commercial posters and holiday promotional images with a strong sense of design and precise text embedding, meeting brand promotion needs.
-
Realistic Photography and Artistic Creation: GLM-Image excels at generating realistic images such as portraits, landscapes, and still lifes, supports artistic style customization, and meets creative needs.