
What is GLM-4V-Plus
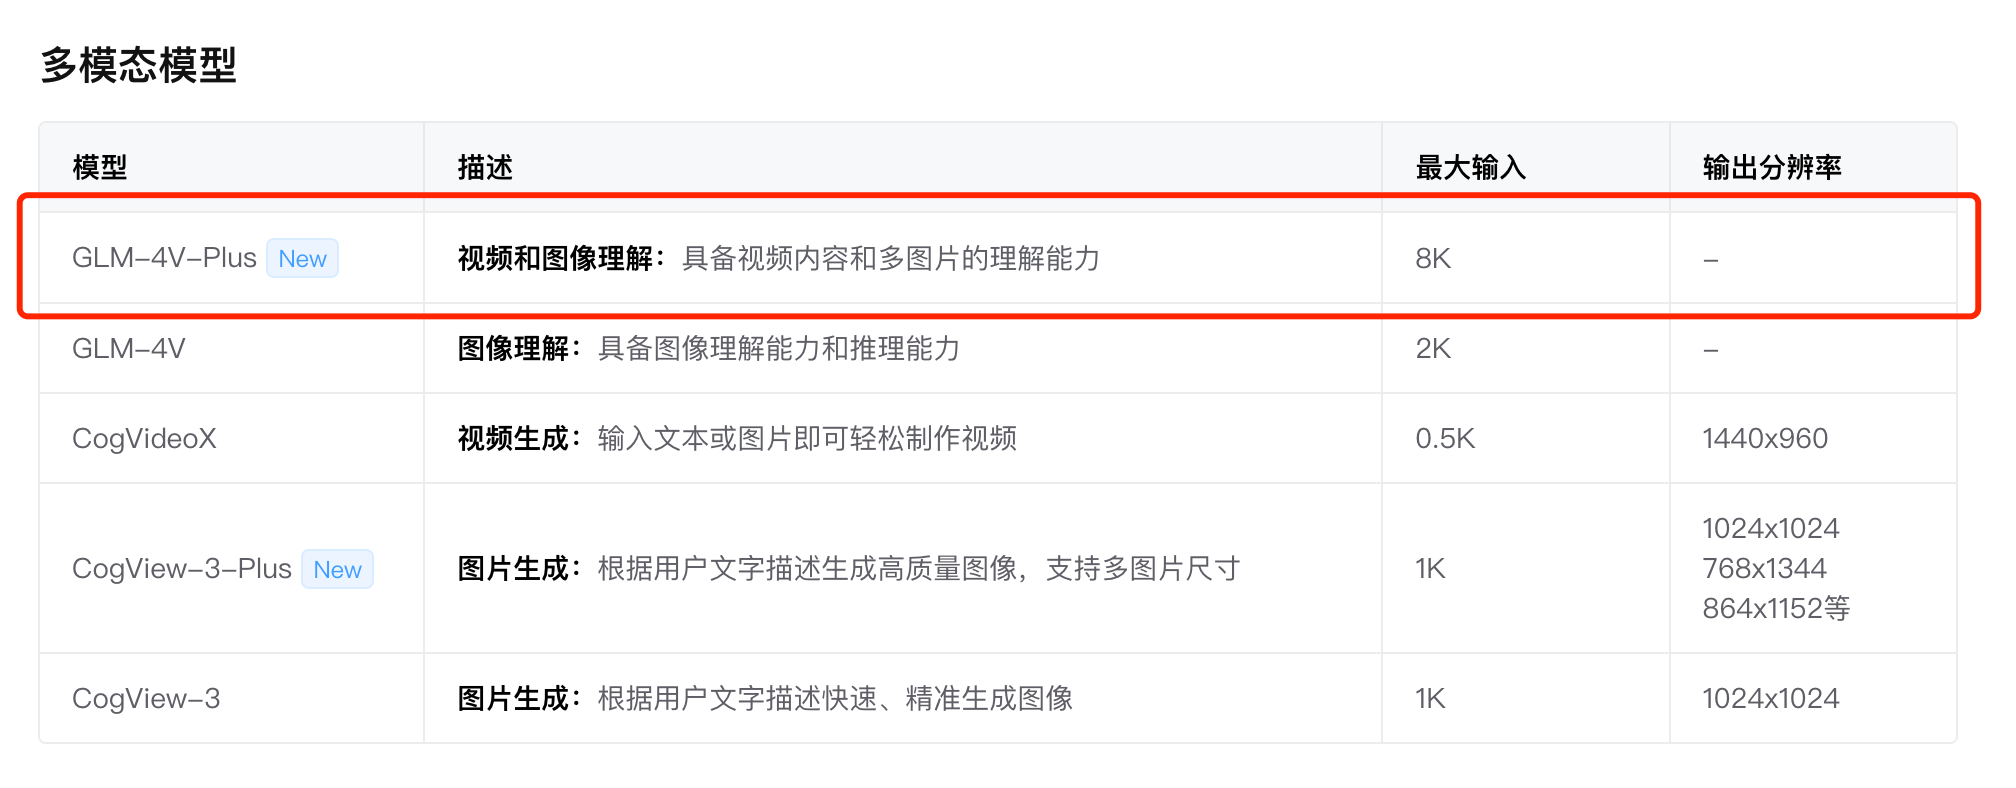
GLM-4V-Plus is Zhipu AI's latest multimodal AI model, focused on image and video understanding. GLM-4V-Plus can not only accurately analyze static images, but also has temporal perception and understanding capabilities for dynamic video content, and can capture key events and actions in videos. As the first model in China to provide a video understanding API, GLM-4V-Plus has been integrated into "Zhipu QingyanAPP", and launched the "Video Call" feature. At the same time, GLM-4V-Plus is on the Zhipu AI Open Platform BigModel and simultaneously opens the API, supporting developers and enterprise users to quickly integrate video analysis capabilities, widely used in security monitoring, content moderation, smart education, and many other scenarios.
Features of GLM-4V-Plus
- Multimodal understanding: Combines image and video understanding capabilities, and can easily process and analyze visual data.
- High-quality image analysis: Has excellent image recognition and analysis capabilities, and can understand image content.
- Video content understanding: Can parse video content and identify objects, actions, and events in videos.
- Temporal perception capability: Has an understanding of the temporal sequence of video content, and can capture information that changes over time in videos.
- API service: As China's first general video understanding model API, GLM-4V-Plus provides open platform services and is easy to integrate.
- Real-time interaction: Supports real-time video analysis and interaction, and is suitable for application scenarios that require rapid response.
How to use GLM-4V-Plus
- Product experience: GLM-4V-Plus has been integrated into Zhipu Qingyan , and can be experienced directly in the Qingyan APP.
- API access: GLM-4V-Plus has opened its API, and it can be accessed through Zhipu AI Open Platform BigModel .
Performance metrics of GLM-4V-Plus
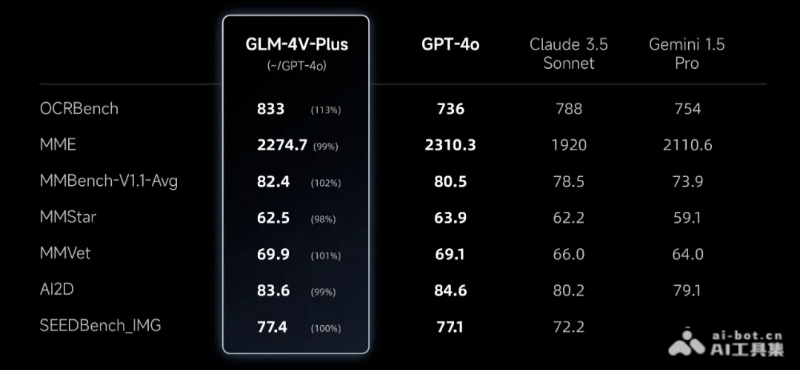
GLM-4V-Plus, a multimodal model with high-quality image understanding and video understanding capabilities, has performance metrics approaching GPT-4o.
Application scenarios of GLM-4V-Plus
- Video content moderation: Automatically detects inappropriate content in videos, such as violence, adult content, or other footage that violates platform regulations.
- Security monitoring analysis: In the field of security monitoring, analyzes video streams in real time to identify abnormal behavior or events and issue timely alerts.
- Smart education assistance: In the field of education, analyzes educational video content and provides feedback and suggestions on students' learning behavior.
- Autonomous vehicles: Provides environmental perception capabilities for autonomous driving systems, analyzing surrounding vehicles, pedestrians, and traffic signals.
- Health and sports analysis: Analyzes sports videos and provides movement technique analysis and improvement suggestions for athletes or fitness enthusiasts.
- Entertainment and media production: In film and television production, automatically tags and searches for key scenes or objects in videos.