
What is General365
General365 is a general reasoning evaluation benchmark open-sourced by Meituan's LongCat team. It includes 365 original seed questions and 1,095 extended variants, covering eight major dimensions of reasoning challenges. The benchmark strictly limits the knowledge scope to the K-12 level, decoupling large models' reasoning ability from professional knowledge dependence, and truly evaluates models' general logical reasoning level in everyday scenarios. Actual tests show that among 26 mainstream large models, only Gemini 3 Pro achieved an accuracy of 62.8%, and the vast majority of models did not pass the 60% passing line.
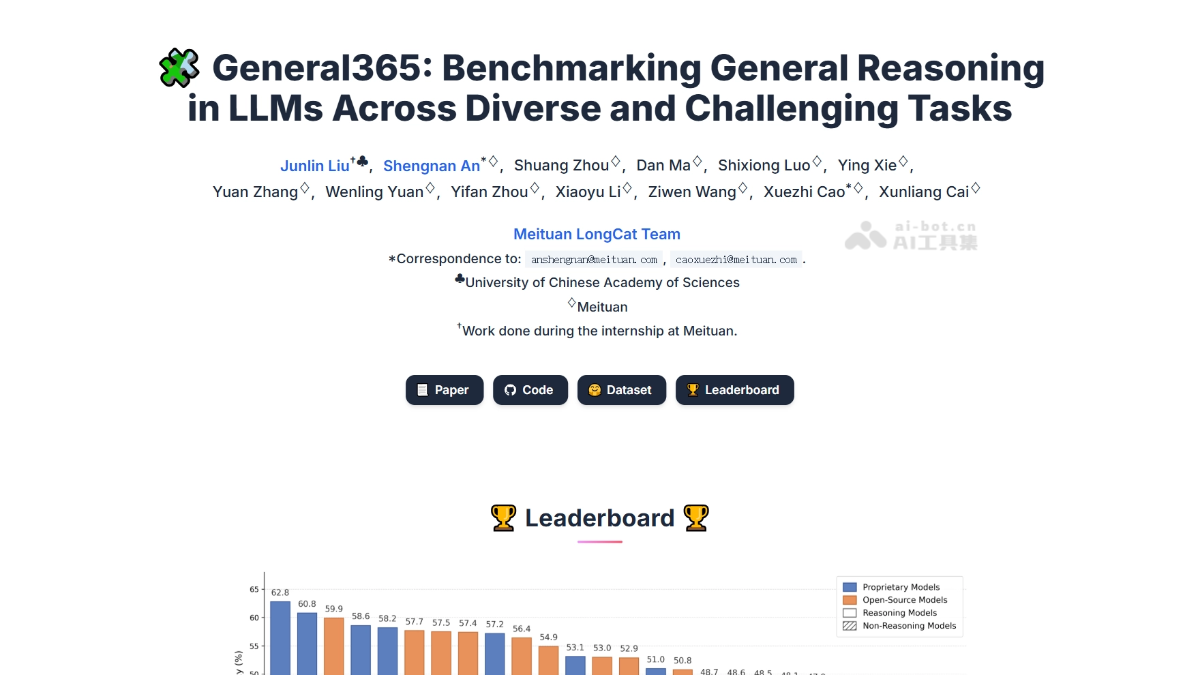
Main Features of General365
-
High-Diversity Evaluation: 365 manually original seed questions + 1,095 variants, covering eight major dimensions: complex constraints, branching enumeration, spatiotemporal reasoning, recursive backtracking, semantic interference, implicit information, optimal strategies, and probabilistic uncertainty.
-
Decoupling Reasoning from Knowledge: Background knowledge is limited to the K-12 range, purely measuring logical reasoning ability rather than knowledge retrieval.
-
Hybrid Scoring System: Combines rule-based scoring with model-based scoring (GPT-4.1), with manually verified scoring accuracy reaching 99.6%.
-
Public Subset and Hidden Test Set: 180 seed questions and variants have been made public (720 questions in total), and the remaining questions serve as a hidden test set to prevent data contamination.
-
Multi-Model Horizontal Evaluation: Supports standardized evaluation of the reasoning capabilities of 26+ models including OpenAI, Gemini, Anthropic, DeepSeek, Qwen, GLM, Kimi, LongCat, and others.
Technical Principles of General365
-
Deconstructing General Reasoning into Eight Dimensions: General reasoning is broken down into 8 core challenge types. Each question corresponds to at least one of them, and nearly 70% of the questions have more than two category labels.
-
Avoiding Templating and Rote Memorization: Through t-SNE semantic distribution validation and Gemini 3 Pro reasoning path similarity scoring, the logical independence of questions is ensured, preventing models from scoring by "memorizing templates".
-
Difficulty Filtering and Manual Review: All questions underwent difficulty filtering, diversity expansion, model-based question expansion, and manual review, forming 1,460 high-quality questions.
-
Hybrid Scoring Framework: Numerical questions are parsed and verified using the math-verify tool; multiple-choice and text questions are scored using GPT-4.1.
Core Advantages of General365
-
Focus on Real Reasoning Ability: Unlike subject competition evaluations such as AIME and IMO, General365 focuses on everyday general logic, exposing the weakness of large models being "high-scoring but low-ability".
-
High Discrimination: Even SOTA models barely pass, avoiding the problem of existing benchmarks (such as BBH and BBEH) having saturated performance and being unable to distinguish models.
-
Diversity That Withstands Scrutiny: The semantic distribution is evenly dispersed, and logical independence is far higher than that of BBH and BBEH.
-
Open Source and Reproducible: The GitHub repository provides complete evaluation code, supporting rapid community integration and reproduction.
Project Address of General365
- Project Official Website:https://general365.github.io/
- GitHub Repository:https://github.com/meituan-longcat/General365
- HuggingFace Model Library:https://huggingface.co/datasets/meituan-longcat/General365_Public
- arXiv Technical Paper:https://arxiv.org/pdf/2604.11778
Comparison of General365 with Similar Competing Products
| Dimension | General365 | BBH (Big-Bench Hard) | BBEH (Big-Bench Extra Hard) |
|---|---|---|---|
| Evaluation Focus | General reasoning (K-12 knowledge) | Comprehensive task reasoning | High-difficulty comprehensive tasks |
| Number of questions | 365 seeds + 1095 variants | 23 tasks | Multi-task extension |
| Diversity | Extremely high (uniform semantic distribution, strong logical independence) | Relatively low (obvious clustering phenomenon) | Relatively low (severe templating) |
| Difficulty discrimination | High (SOTA only 62.8%) | Low (performance has saturated) | Medium |
| Scoring method | Hybrid scoring (rules + model, accuracy 99.6%) | Mainly rule-based scoring | Mainly rule-based scoring |
| Data disclosure strategy | Semi-public (180 questions public + hidden test set) | Fully public | Fully public |
Application scenarios of General365
-
Large model R&D evaluation: Helps model developers identify weaknesses in reasoning ability and optimize in a targeted way weak dimensions such as complex constraints, semantic interference, and optimal strategies.
-
Model selection reference: Provides objective data support for enterprise users choosing commercial or open-source models with stronger reasoning ability.
-
Academic research: Provides a standardized evaluation tool for the field of general reasoning, promoting the evolution of LLMs from "disciplinary experts" to "general reasoners."
-
Reasoning efficiency analysis: Supports analyzing the relationship between model accuracy and the number of output tokens, and evaluating reasoning efficiency.