
What is Gemini 3.5 Flash-Lite
Gemini 3.5 Flash-Lite is the fastest and cheapest model in the Gemini 3.5 series released by Google, designed for high-throughput, low-latency production-grade Agent workflows. The model supports adjustable reasoning levels, achieves an output speed of 350 tokens/s, and is priced at only $0.30/$2.50 per million tokens. It surpasses the previous generation 3 Flash on multiple Agent and coding benchmarks, making it suitable for batch document processing, sub-Agent collaboration, and real-time interaction scenarios.
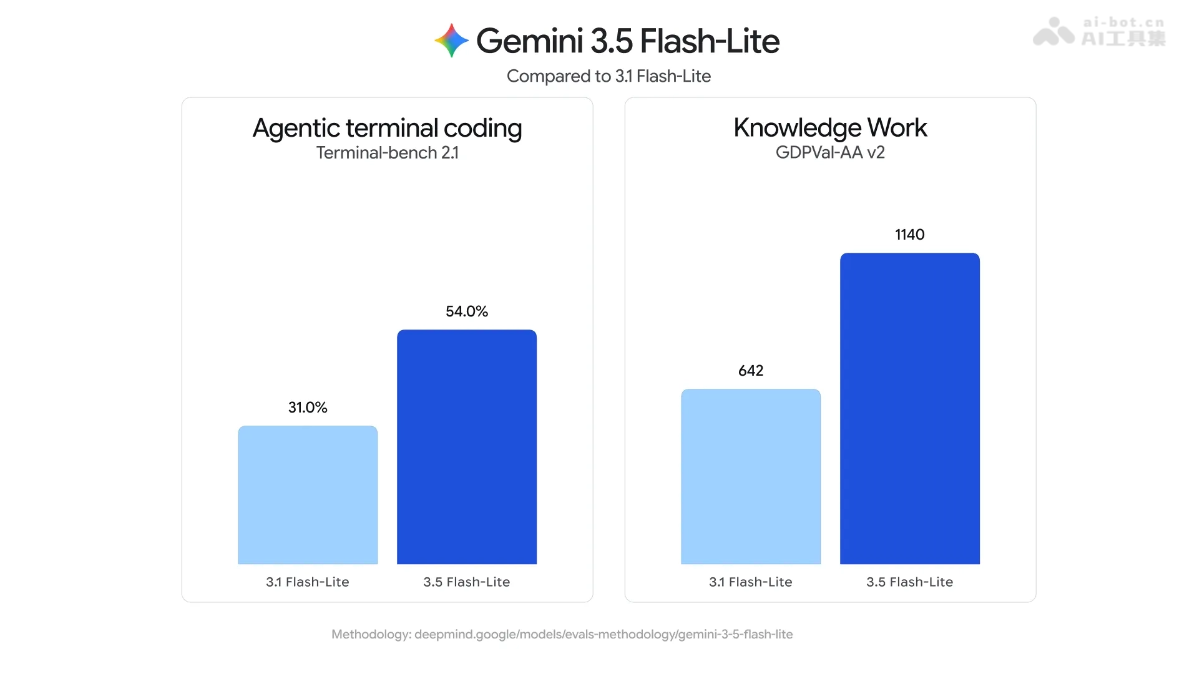
Main features of Gemini 3.5 Flash-Lite
-
Ultra-fast output: The fastest in the 3.5 series, measured by Artificial Analysis at 350 output tokens/second.
-
Adjustable reasoning levels: Supports low/medium/high thinking modes. For simple tasks, use the lowest level to maintain speed; for complex subtasks, use a higher level to maintain quality.
-
Built-in computer operation: Computer Use becomes a built-in tool, ready out of the box to support Agent tasks.
-
Leapfrog quality improvement: Compared with 3.1 Flash-Lite, coding, long-context, and real task execution capabilities have improved significantly.
Technical principles of Gemini 3.5 Flash-Lite
-
Architectural foundation: Streamlined and optimized based on the Gemini 3.5 Flash architecture, retaining core capabilities while extremely compressing inference overhead.
-
Dynamic thinking mode: Through configurable thinking levels, it switches between latency and quality as needed.
-
High-throughput optimization: Optimized for parallel generation efficiency in scenarios such as batch document processing and Agent search, achieving a peak output of 350 tokens/s.
How to use Gemini 3.5 Flash-Lite
-
Developers: Through Google AI Studio, Gemini API calls, supporting flexible configuration of thinking levels.
-
Enterprise users: Integrated into the Gemini Enterprise Agent Platform, suitable for high-concurrency production traffic.
-
General users: Has been gradually rolled out to consumer scenarios such as Google Search.
Core advantages of Gemini 3.5 Flash-Lite
-
Ultimate speed and cost: The generation speed of 350 tokens/s combined with pricing of $0.3/$2.5 makes the cost of large-scale tasks extremely low.
-
Punching above its weight: Surpasses the higher-tier 3 Flash on SWE-Bench Pro and OSWorld-Verified (74.0% vs 65.1%).
-
Flexible thinking levels: Developers can freely switch reasoning depth according to task complexity, without paying unnecessary computational overhead for simple tasks.
-
Agent-native: Built-in Computer Use and multiple thinking modes, designed specifically for scenarios such as sub-Agent collaboration and batch data processing.
Comparison of Gemini 3.5 Flash-Lite with similar competitors
| Comparison dimension | Gemini 3.5 Flash-Lite | Gemini 3.1 Flash-Lite |
|---|---|---|
| Terminal-Bench 2.1 | 54.0% | 31.0% |
| GDPval-AA v2 | 1140 | 642 |
| GDM-MRCR v2 | 72.2% | 60.1% |
| Output speed | 350 token/s | Not disclosed |
| Input price | $0.30/million tokens | Higher |
| Output price | $2.50/million tokens | Higher |
Application scenarios of Gemini 3.5 Flash-Lite
-
High-throughput Agent search: Large-scale web retrieval, information aggregation, and summary generation, responding to user queries with low latency.
-
Batch document processing: Massive data pipelines such as Receipt translation, e-commerce product feature extraction, and batch contract parsing.
-
Sub-agent collaboration: Serving as an assistant to a main Agent (such as 3.6 Flash), rapidly generating multiple versions of solutions (such as 25 web design concepts) for selection.
-
Real-time interactive applications: Scenarios requiring rapid responses, such as customer service chatbots, real-time recommendation systems, and low-latency dialogue interfaces.
-
Lightweight game/creative generation: Rapidly iteratively generating mini-game prototypes and visual assets, with immediate tuning based on human feedback.