
What is GarDiff
GarDiff is an innovative virtual try-on technology that uses CLIP and VAE encoding to extract the appearance prior of clothing, and combines a clothing-focused adapter with a high-frequency detail enhancement algorithm to generate high-fidelity and detail-rich try-on images. It can precisely align clothing with human body poses, preserve the complex patterns and textures of clothing, and provide a realistic online try-on experience. GarDiff outperforms existing technologies on the VITON-HD and DressCode datasets, and the code has been open-sourced for further research and application development.
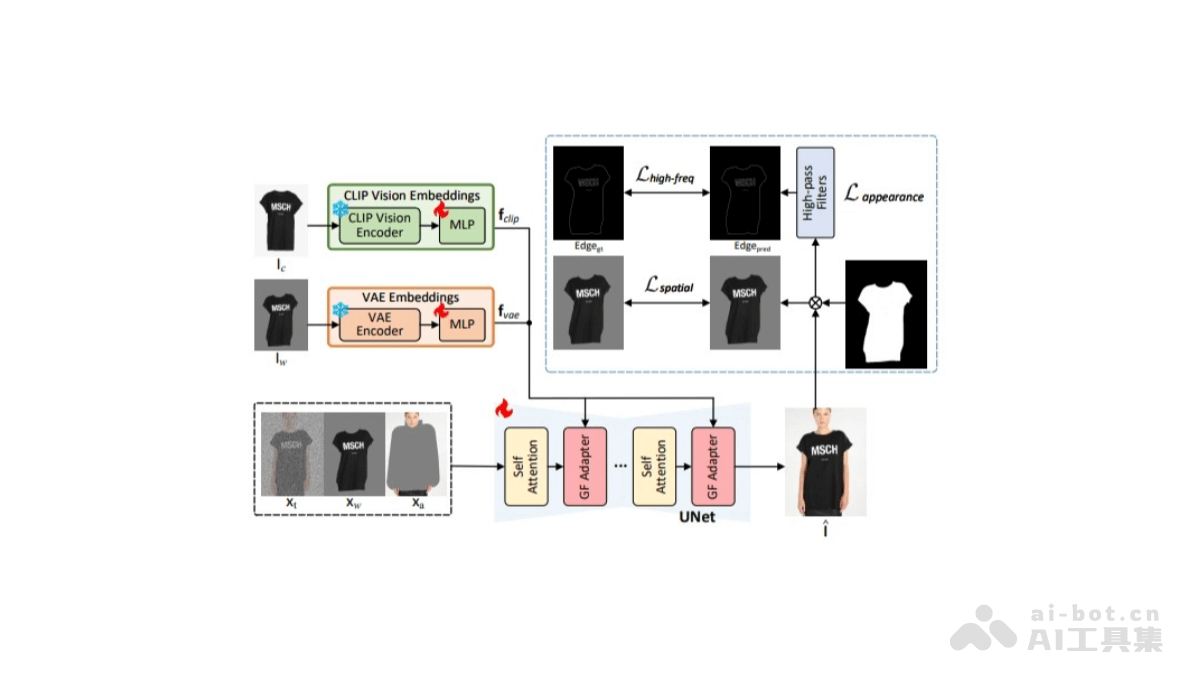
GarDiff's main features
- High-fidelity try-on image generation:GarDiff can generate high-resolution and realistic try-on images, preserving the characteristics of the target person and the details of the clothing.
- Clothing detail preservation:Focuses on preserving every appearance and texture detail of the clothing, including complex patterns and text.
- Alignment of clothing with human body pose:GarDiff uses a special adapter to ensure that the clothing is visually perfectly aligned with the human body pose, regardless of how the body pose changes.
- Clothing-focused diffusion process:With a clothing-centered diffusion process, GarDiff pays special attention to the details of the clothing when generating images.
- Appearance prior guidance:The appearance prior of the reference clothing is extracted through CLIP and VAE encoding, and this prior information serves as an additional condition to guide image generation.
GarDiff's technical principles
- CLIP and VAE encoding: Based on the CLIP visual encoder and VAE encoder, the appearance prior of the reference clothing is extracted, and these priors serve as additional conditions to guide the diffusion process.
- Clothing-focused adapter (GF Adapter): In each Transformer block, the original cross-attention layer is replaced with the proposed clothing-focused visual adapter module. The adapter processes CLIP visual embeddings and VAE embeddings separately through a decoupled cross-attention mechanism.
- Appearance Loss: A new appearance loss is proposed, including Spatial Perceptual Loss and High-Frequency Promoted Loss, strengthening the model's ability to generate high-frequency details.
GarDiff's project address
- Github repository:https://github.com/siqi0905/GarDiff/tree/master
- arXiv technical paper:https://arxiv.org/pdf/2409.08258v1
GarDiff's application scenarios
- E-commerce:Online retailers can use GarDiff to provide virtual try-on functionality, allowing customers to see the effect of clothing on themselves before purchasing, improving the shopping experience and satisfaction.
- Fashion design:Fashion designers can use GarDiff to preview the effect of design sketches on different models, and quickly iterate and adjust designs.
- Personalized recommendations:E-commerce platforms can use GarDiff to generate personalized try-on effects based on users' body types and preferences, and recommend more suitable clothing to users.
- Social media:Users can share their virtual try-on photos on social media, increasing interactivity and entertainment.
- Virtual fashion shows:Fashion brands can use GarDiff to create virtual fashion shows and display the latest collections without physical clothing or live models.
- Games and virtual reality:In virtual worlds or games, players can use GarDiff to customize and preview their avatars, enhancing immersion.