
What is FunAudio-ASR
FunAudio-ASR is an end-to-endspeech recognitionlarge model launched by Alibaba DAMO Academy, designed specifically to solve key problems in enterprise deployment. Through an innovative Context enhancement module, it effectively optimizes issues such as "hallucinations" and "language mixing." The module uses a CTC decoder to quickly generate a first-pass transcription text, which is then fed into the LLM as context information, significantly improving recognition accuracy and stability. FunAudio-ASR performs excellently in complex scenarios such as far-field and noisy backgrounds, and the lightweight version FunAudio-ASR-nano is suitable for resource-constrained deployment environments. The model introduces a RAG mechanism, greatly enhancing personalized customization capabilities through dynamic retrieval and precise injection of custom words.
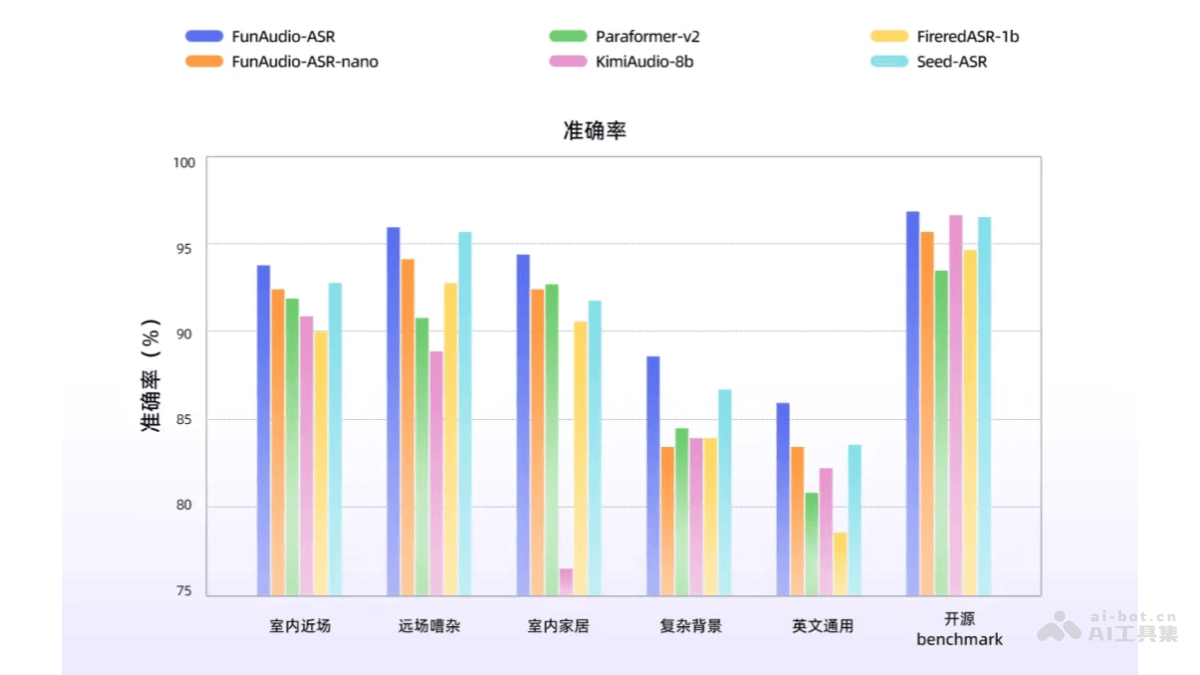
Main features of FunAudio-ASR
-
High-precision speech recognition: Through an innovative Context enhancement module, it significantly optimizes key issues in industrial scenarios such as "hallucinations" and "language mixing," improving recognition accuracy.
-
Lightweight version: Launches FunAudio-ASR-nano, which maintains relatively high recognition accuracy while having lower inference cost, making it suitable for resource-constrained deployment environments.
-
Personalized customization: Introduces a RAG mechanism to dynamically retrieve and precisely inject custom words, enhancing personalized customization capabilities and meeting the professional terminology recognition needs of different fields.
-
Multi-scenario applications: Has been applied in multiple scenarios such as DingTalk's "AI Tingji," video conferencing, and DingTalk A1 hardware, verifying its stability and high-precision recognition capability in real enterprise environments.
-
Knowledge enhancement: Combines contextual information such as contacts and schedules for inference optimization, further improving result reliability and elevating "customization" from the vocabulary level to the enterprise knowledge level.
Technical principles of FunAudio-ASR
-
Context enhancement module: Uses a CTC decoder to quickly generate a first-pass transcription text, then feeds the result into the LLM as context information, helping it understand the audio content more accurately and reducing "hallucinations" and "language mixing" issues.
-
RAG mechanism: Builds a knowledge base and dynamically retrieves related words, precisely injecting them into the LLM prompt to avoid interference from irrelevant information and improve customized recognition performance.
-
Acoustic and text feature alignment: Through high-quality data training, optimizes the alignment of acoustic features and text features, reducing recognition errors caused by feature differences.
-
High-noise environment optimization: Adds a large amount of simulated data to the training data to improve the model's recognition capability in high-noise scenarios.
-
Lightweight design: Adopts a lightweight CTC structure, adding almost no extra inference time, ensuring that the model has efficient inference speed while maintaining high precision.
How to use FunAudio-ASR
-
Alibaba Cloud Bailian platform deployment: VisitAlibaba Cloud BailianThrough the service provided by the platform, enterprises can quickly deploy FunAudio-ASR to implement speech recognition functionality.
-
Local deployment: Through Docker containerized deployment, users can run FunAudio-ASR on local servers to meet data security and privacy requirements.
-
Client integration: Provides clients in multiple programming languages, such as Python, C++, Java, and C#, making it easy for developers to integrate it into different applications.
-
Customization services: Users can personalize FunAudio-ASR according to their own needs through the RAG mechanism and customized vocabulary libraries to improve recognition accuracy for terminology in specific domains.
Application scenarios of FunAudio-ASR
-
Meeting records: Efficiently transcribe meeting audio and generate detailed text records for easy later review and organization.
-
Video conferencing: Recognize speech content in video conferences in real time and provide subtitle support to improve meeting efficiency.
-
Education and training: Transcribe the speech content in educational videos or lectures into text, making it convenient for students to review and organize materials.
-
Customer service: Transcribe customer service call recordings for analyzing customer feedback and optimizing service processes.
-
Industry terminology recognition: In specific industries (such as technology, finance, healthcare, etc.), accurately recognize professional terminology to meet industry-specific needs.
-
Real-time subtitle generation: Provide real-time subtitles for live streams and video content to enhance content accessibility.