
What is Free Video-LLM
Free Video-LLM is an innovative, efficient video language model without training, based on prompt-guided visual perception technology, achieving efficient understanding of video content. The model uses pre-trained image LLMs, and can adapt to video tasks without additional training, reducing the number of visual tokens generated from video frames and lowering computational cost. Free Video-LLM demonstrates performance comparable to state-of-the-art video LLMs on multiple video question answering benchmarks, significantly reducing the use of visual tokens, and providing an ideal balance between accuracy and computational efficiency for video understanding tasks.
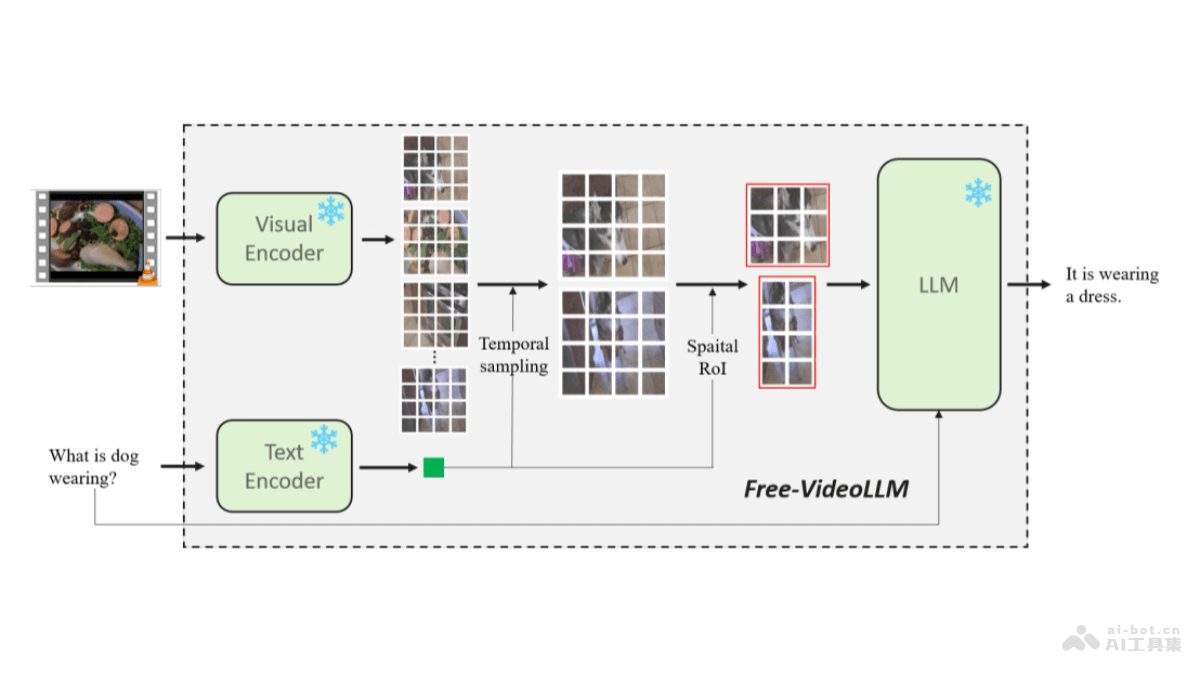
Main features of Free Video-LLM
- Efficient video understanding: Free Video-LLM directly understands and reasons about video content without additional training, and is suitable for multimodal tasks such as video question answering.
- Prompt-guided visual perception: Based on analyzing the input prompt, the model can identify the spatiotemporal information in the video most relevant to the task, reducing unnecessary computation.
- Spatiotemporal sampling optimization: The model uses temporal frame sampling and spatial region of interest (RoI) cropping techniques to reduce the amount of video data processed by the model and improve inference efficiency.
- Maintaining high performance: Although the number of visual tokens is reduced, the model still maintains performance competitive with existing technologies on multiple video question answering benchmark tests.
Technical principles of Free Video-LLM
- Prompt-guided temporal sampling:Extract prompt features based on a text encoder that matches the visual encoder.Compute similarity scores between video frame features and prompt features.Sample video frames according to the scores, selecting the frames most relevant to the task.
- Prompt-guided spatial sampling (RoI cropping):Reshape the visual tokens of video frames into spatial dimensions.Compute similarity scores between the feature vector of each spatial position and the prompt features.Select the most relevant regions as RoIs and crop out these regions.
- Reduce visual tokens:Based on spatiotemporal sampling methods, reduce the number of visual tokens the model needs to process and lower computational complexity.
- Maintain performance:Although visual tokens are reduced, based on a carefully designed sampling strategy, the model can maintain or improve performance on video understanding tasks.
Project address of Free Video-LLM
- GitHub repository:https://github.com/contrastive/FreeVideoLLM
- arXiv technical paper:https://arxiv.org/pdf/2410.10441
Application scenarios of Free Video-LLM
- Video question answering system: Provide automatic question answering services for video content, such as video tutoring on educational platforms or understanding corporate training videos.
- Video content analysis: In the media and entertainment industry, automatically extract semantic information from video content to facilitate content management and retrieval.
- Security monitoring: In the security field, conduct real-time analysis of surveillance video to identify specific events or behaviors.
- Autonomous driving: In autonomous vehicles, understand and interpret video streams of road conditions to assist decision-making.
- Intelligent assistant: Integrate into intelligent assistants to provide interactive question answering functions based on video content.