
What is Follow Your Pose
Follow Your Pose is an open-source framework based on text-to-video generation, developed by researchers from Tsinghua University, the Hong Kong University of Science and Technology, Tencent AI Lab, and the Chinese Academy of Sciences. It allows users to generate videos through text descriptions and specified human poses. The framework adopts a two-stage training strategy, capable of generating videos highly consistent with text descriptions and pose sequences, while maintaining the realism and coherence of human actions in the videos.
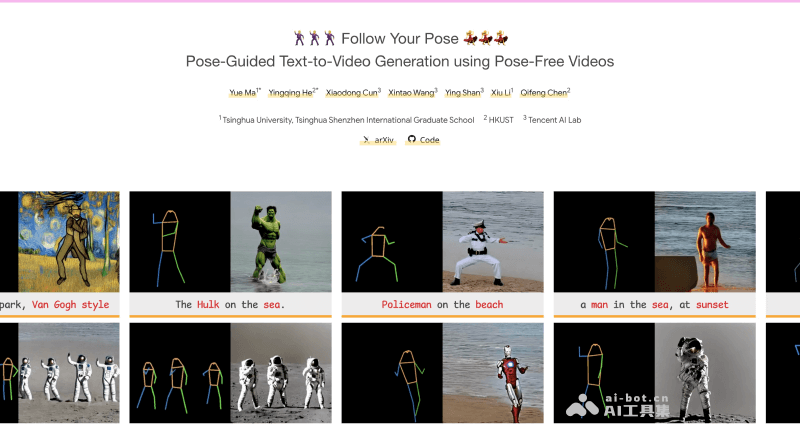
Follow Your Pose Official Website Entry
- Official Project Homepage:https://follow-your-pose.github.io/
- GitHub Repository:https://github.com/mayuelala/FollowYourPose
- Arxiv Research Paper:https://arxiv.org/abs/2304.01186
- Hugging Face Run Address:https://huggingface.co/spaces/YueMafighting/FollowYourPose
- OpenXLab Run Address:https://openxlab.org.cn/apps/detail/houshaowei/FollowYourPose
- Google Colab Run Address:https://colab.research.google.com/github/mayuelala/FollowYourPose/blob/main/quick_demo.ipynb
Follow Your Pose Features
- Text-to-Video Generation: Users can input text descriptions, and the framework will generate corresponding video content based on these descriptions, such as character actions, scene backgrounds, and overall visual style.
- Pose Control: Users can control the actions of characters in the video by specifying human pose sequences, allowing precise control over every action detail of the character in the video.
- Temporal Coherence: The framework can generate temporally coherent videos, ensuring that actions and scene changes in the video are natural and smooth, without abrupt jumps or flickering.
- Diverse Character and Background Generation: The framework can generate videos with different appearances, styles, and backgrounds, including but not limited to realistic style, cartoon style, cyberpunk style, etc.
- Multi-Character Video Generation: The framework supports the generation of multi-character videos, can display multiple characters in the same video, and can specify the identity and actions of each character based on text descriptions.
- Stylized Video Generation: Users can generate videos with specific artistic styles by adding style descriptions (such as "cartoon style", "cyberpunk style", etc.).
How Follow Your Pose Works
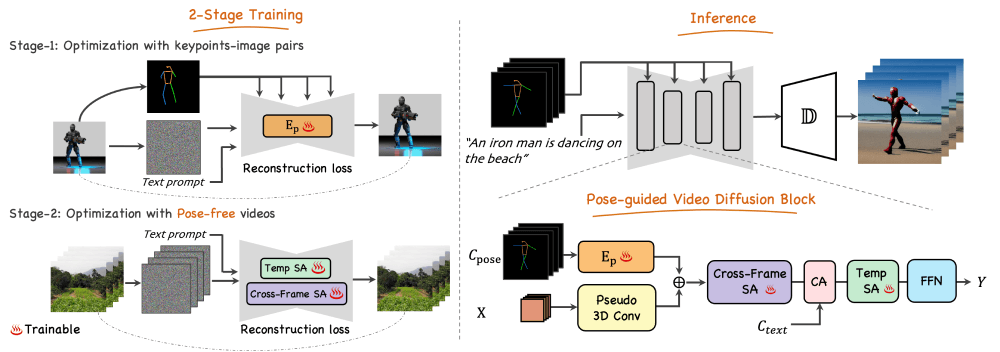
The working principle of Follow Your Pose is mainly based on a two-stage training process, aimed at combining text descriptions and pose information to generate videos. The following are the detailed steps of its working principle:
- Stage One: Pose-Controlled Text-to-Image Generation
- Pose Encoder: First, the framework uses a zero-initialized convolutional encoder to learn pose information. This encoder extracts keypoint features from the input pose sequence.
- Feature Injection: The extracted pose features are downsampled to different resolutions and injected into the U-Net structure of a pre-trained text-to-image (T2I) model via residual connections. This introduces pose control while maintaining the original model's image generation capability.
- Training: In this stage, the model is trained only on pose-image pairs, with the goal of learning how to generate images based on text descriptions and pose information.
- Stage Two: Video Generation
- Video Dataset: To learn temporal coherence, the framework uses a video dataset without pose annotations (such as HDVLIA) for training in the second stage.
- 3D Network Structure: Extend the pretrained U-Net model to a 3D network so that it can process video input. This involves extending the first convolutional layer to a pseudo-3D convolution and adding a temporal self-attention module to model the temporal sequence.
- Cross-frame self-attention: To further improve video coherence, the framework introduces a cross-frame self-attention module, which helps maintain content consistency across video frames.
- Fine-tuning: At this stage, only the parameters related to temporal coherence (such as temporal self-attention and cross-frame self-attention) are updated, while other parameters (such as the pseudo-3D convolutional layers and the feedforward network FFN) remain unchanged.
- Generation process
- Text and pose input: During inference, the user inputs text describing the target character's appearance and motion, as well as a pose sequence representing the motion sequence.
- Video generation: The model generates video based on these inputs. During the generation process, most pretrained Stable Diffusion model parameters are frozen, and only the modules related to temporal coherence participate in computation.
Through this two-stage training strategy, Follow Your Pose can effectively learn from easily obtainable datasets and generate videos with a high degree of controllability and temporal coherence.