
What is Fluid
Fluid is an autoregressive text-to-image generation model jointly launched by Google DeepMind and MIT. Based on continuous tokens and a random generation order approach, it has achieved breakthrough progress in visual quality and evaluation performance. When scaling up the model size, the model can effectively improve the visual quality of image generation and address the limitations of traditional autoregressive models. At a scale of 1.05 billion parameters, Fluid achieves a zero-shot FID score of 6.16 on the MS-COCO dataset and a score of 0.69 on the GenEval benchmark, setting a new record in the text-to-image field. Fluid's innovation lies in its random-order generation mechanism and the use of continuous tokens, which enable it to better capture global structure when generating images, especially performing well in multi-object scenes.
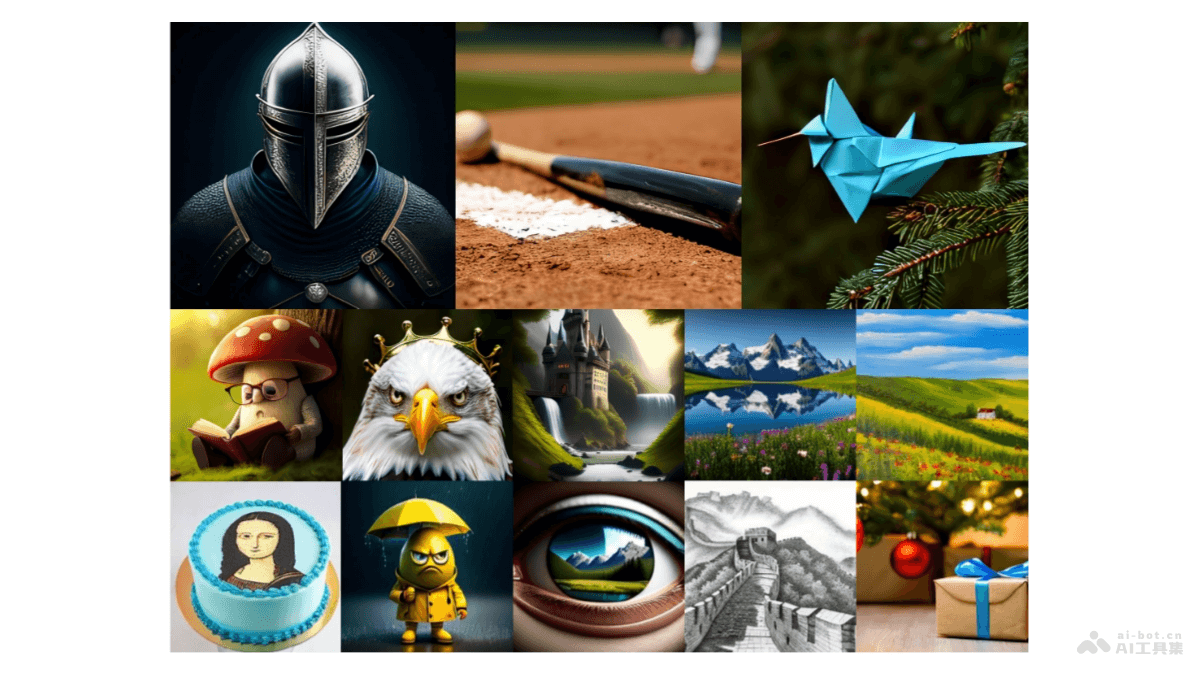
Fluid's main features
- Text-to-image generation: Generates corresponding images based on given text prompts.
- Use of continuous tokens: Uses continuous tokens instead of discrete tokens, reducing information loss and improving image quality.
- Random-order generation: Does not generate images in a fixed order; instead, it randomly selects the generation order, better capturing global structure.
- Autoregressive modeling: Predicts the next element in the sequence step by step, constructing images that match text prompts.
- Transformer-based architecture: Uses Transformer models to process sequence data and capture long-range dependencies.
Fluid's technical principles
- Continuous Tokens: Unlike traditional discrete tokens, Fluid uses continuous token representations, enabling the model to capture and reconstruct image details and textures more finely and reducing information loss.
- Random-Order Generation: Fluid does not generate images in a fixed order but randomly selects the generation order, which helps the model better consider global structure and contextual information during generation.
- Autoregressive Architecture: Fluid uses an autoregressive model, in which the model predicts the next element in the sequence step by step to construct the output and generate images. This helps the model learn the complex mapping relationship between text and images.
- Transformer Models: Fluid is based on the Transformer architecture, which has achieved great success in the field of natural language processing due to its effectiveness in processing sequence data. Transformer models can capture long-range dependencies and use attention mechanisms in image generation to strengthen connections between different parts.
Fluid's project address
- arXiv technical paper:https://arxiv.org/pdf/2410.13863v1
Fluid's application scenarios
- Artistic creation: Artists and designers use Fluid to generate unique images and artworks, accelerating the creative process and exploring new visual styles.
- Media and entertainment: In film, game, and animation production, Fluid quickly generates concept art, background scenes, or character designs, improving pre-production efficiency.
- Advertising and marketing: Marketers use Fluid to design advertising images and marketing materials, quickly realizing creative ideas and producing eye-catching visual content.
- Education and research: In education, Fluid serves as a teaching tool to help students understand complex concepts; in scientific research, it helps researchers visualize abstract data and theoretical models.
- Content creation automation: Automatically generate image content for social media, blogs, and online publications, improving the efficiency and appeal of content production.