
What is FlowAct-R1
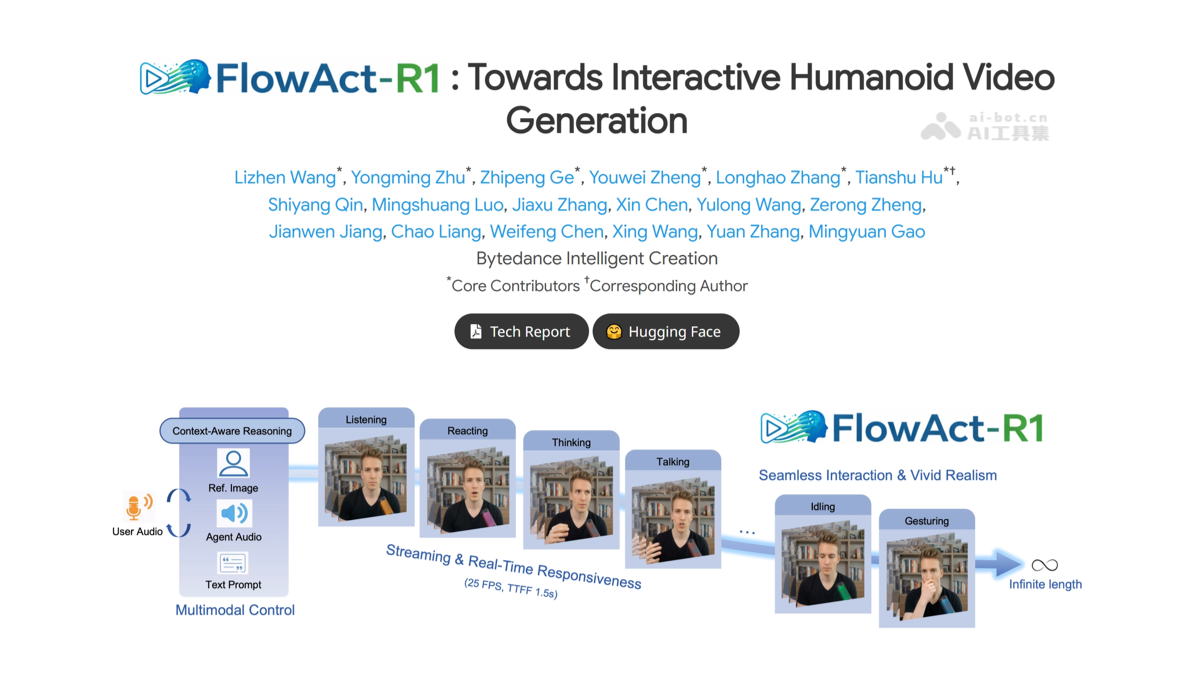
FlowAct-R1 is a real-time interactivedigital humanvideo generation framework launched by ByteDance. It requires only a single reference image and audio, and supports streaming generation of full-body dynamic videos of unlimited duration. The framework achieves low latency (1.5-second first frame) and stable real-time response at 25fps through chunked diffusion forcing strategy and a multimodal large language model. It can finely control the digital human's facial expressions and body movements, making it suitable for scenarios such as video conferencing, virtual companionship, and live interactive streaming. It has strong generalization ability and can drive characters in various styles.
Main features of FlowAct-R1
-
Real-time interaction and unlimited duration generation: The framework requires only a single reference image and audio input, and can stream-generate full-body dynamic videos of unlimited duration. It supports long-term stable operation without common issues such as face collapse.
-
Low latency and high frame rate: The framework can achieve 1.5-second first-frame low latency and stable real-time response at 25fps, ensuring a smooth and natural interaction process, suitable for scenarios such as video conferencing and live interactive streaming.
-
Full-body motion and expression control: Through multimodal instructions, it finely controls the digital human's facial expressions and body movements, such as listening, thinking, gestures, etc., making interactions more vivid and realistic.
-
Strong generalization ability: The framework is not limited to specific individuals and can drive characters in various styles from a single reference image, including realistic photos, anime, artistic painting styles, etc.
Technical principles of FlowAct-R1
-
Streaming generation and unlimited duration: The frameworkadopts a chunked diffusion forcing strategy, dividing the video into small chunks and generating them chunk by chunk, and uses a structured memory bank to ensure visual continuity, achieving theoretically unlimited duration generation.
-
Real-time performance optimization: The frameworkcombines multi-stage distillation technology to compress the denoising steps of the diffusion model to 3 steps.Combined with FP8 quantization and operator fusion, it greatly reduces memory read/write overhead, ultimately achieving real-time generation capability at 25fps and 480p.
-
Full-body control and behavior planning: The frameworkintroduces a multimodal large language model as the "brain" to determine the actions the digital human should perform based on speech and context, achieving fine-grained natural motion planning and eliminating mechanical feel.
-
High-fidelity visual effects: The frameworkmaintains high-fidelity visual effects during the generation process. Through optimized model architecture and training strategies, it ensures high-quality performance of generated videos in different styles and scenarios.
Project address of FlowAct-R1
- Project official website:https://grisoon.github.io/FlowAct-R1/
- arXiv technical paper:https://arxiv.org/pdf/2601.10103
Application scenarios of FlowAct-R1
-
AI live streaming: The framework can achieve 24-hour uninterrupted, real-time interactive live streaming, supporting multilingual and style switching, enhancing audience participation.
-
Video conferencing: As a virtual participant, it provides natural body language and interaction, enhancing the realism of meetings and supporting multilingual translation.
-
Virtual companionship: Generates personalized virtual companions, providing emotional support and interactive entertainment to meet users' companionship needs.
-
Online education: As a virtual teacher, it provides vivid teaching and personalized tutoring, supporting multilingual teaching.
-
Customer service: As a virtual customer service agent, answer customer questions in real time, provide multilingual support, and improve customer satisfaction.