
What is FlexiAct
FlexiAct is a novel motion transfer model jointly launched by Tsinghua University and Tencent ARC Lab. Given a target image, FlexiAct can transfer the motion from a reference video to the target subject, achieving precise motion adaptation and appearance consistency in heterogeneous scenarios with large spatial structural differences or cross-domain settings. The model introduces a lightweight RefAdapter module and a Frequency-Aware Motion Extraction (FAE) module to address the limitations of existing methods in terms of differences in layout, viewpoint, and skeleton structure, while maintaining identity consistency. FlexiAct performs excellently in motion transfer for both humans and animals, with broad application prospects.
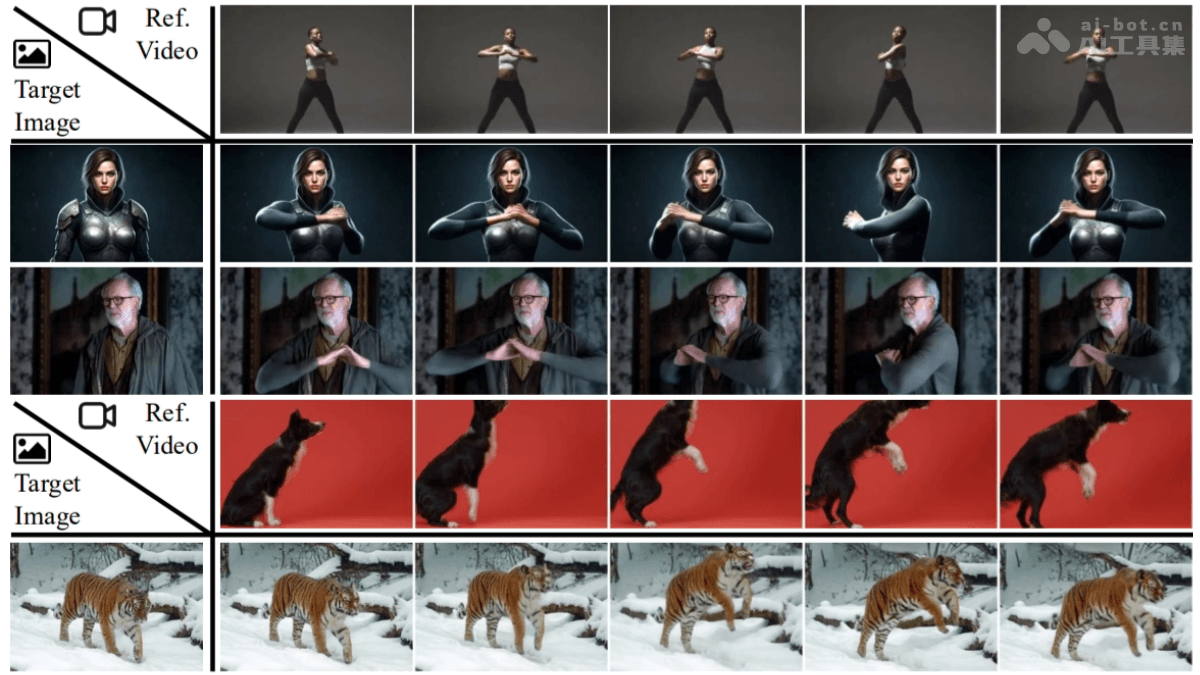
FlexiAct's Main Features
- Cross-Subject Motion Transfer: Supports transferring motion from one person to another, or from a person to an animal.
- Maintaining Appearance Consistency: While transferring motion, ensures that the target subject's appearance (such as clothing, hairstyle, etc.) remains consistent with the original target image.
- Flexible Spatial Structure Adaptation: Can achieve natural motion transfer even when there are differences in layout, viewpoint, and skeleton structure between the reference video and the target image.
FlexiAct's Technical Principles
- RefAdapter (Spatial Structure Adapter): RefAdapter is a lightweight image condition adapter, mainly used to address the spatial structure differences between the reference video and the target image. During training, video frames are randomly selected as condition images to maximize spatial structure diversity. This allows the model to adapt to different poses, layouts, and viewpoints while maintaining appearance consistency. A small number of trainable parameters (such as LoRA modules) are injected to achieve flexible spatial adaptation in the MMDiT layers of CogVideoX-I2V, avoiding the strict constraints in traditional methods.
- Frequency-Aware Motion Extraction: FAE is an innovative motion extraction module that performs motion extraction directly during the denoising process, without relying on an independent spatiotemporal architecture. FAE observes that at different timesteps of denoising, the model focuses differently on motion (low frequency) and appearance details (high frequency). In early timesteps, the model focuses more on motion information; in later timesteps, the model focuses more on appearance details. Based on dynamically adjusted attention weights, FAE prioritizes extracting motion information in early timesteps and focuses on appearance details in later timesteps, achieving precise motion extraction and control.
FlexiAct's Project Address
- Project Website:https://shiyi-zh0408.github.io/projectpages/FlexiAct/
- GitHub Repository:https://github.com/shiyi-zh0408/FlexiAct
- HuggingFace Model Library:https://huggingface.co/shiyi0408/FlexiAct
- arXiv Technical Paper:https://arxiv.org/pdf/2505.03730
FlexiAct's Application Scenarios
- Film and Television Production: Quickly generate realistic character motions, reducing filming costs.
- Game Development: Generate diverse motions for game characters, enhancing the gaming experience.
- Advertising and Marketing: Generate virtual spokesperson motions, enhancing advertising appeal.
- Education and Training: Generate teaching and rehabilitation training motions, assisting learning and recovery.
- Entertainment and Interaction: Support users in creating interesting videos, enhancing the entertainment experience.