
What is Flex.2-preview
Flex.2-preview is an 8-billion-parameter text-to-image diffusion model open-sourced by Ostris, supporting general control inputs (such as lines, pose, depth) and built-in inpainting. The model meets multiple creative needs with a single model, supports long text input (512 tokens), and can be easily used based on ComfyUI or the Diffusers library. Flex.2-preview is currently in an early preview stage, demonstrating strong flexibility and potential, suitable for creative generation and experimental development.
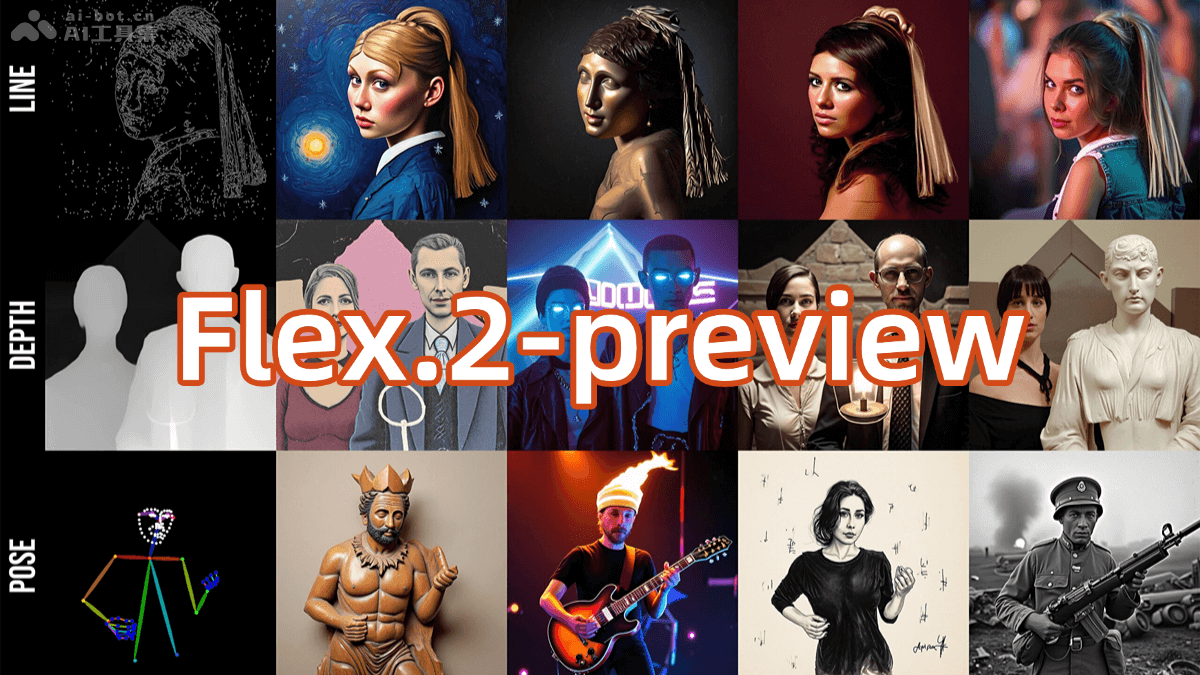
Main Features of Flex.2-preview
- Text-to-Image Generation: Generates high-quality images based on input text descriptions, supports text input of up to 512 tokens, and can understand complex descriptions to generate corresponding image content.
- Built-in Inpainting: Supports repairing or replacing specific areas of an image. The user provides the image to be repaired and an inpainting mask, and the model generates new image content in the specified areas.
- General Control Inputs: Supports various control inputs, such as line art, pose maps, and depth maps, to guide the direction of image generation.
- Flexible Fine-Tuning Capability: Users can fine-tune the model based on techniques such as LoRA (Low-Rank Adaptation) to adapt to specific styles or task requirements.
Technical Principles of Flex.2-preview
- Diffusion Model Framework: Generates images by gradually removing noise. The model starts from random noise and gradually learns how to transform it into an image that matches the text description.
- Multi-Channel Inputs:
- Text Embedding: Converts text descriptions into embedding vectors that the model can understand.
- Control Inputs: Guides the direction of image generation based on additional inputs (such as pose maps and depth maps).
- Inpainting Inputs: Combines the inpainting image and the inpainting mask, and the model generates new content in the specified areas.
- 16-Channel Latent Space: The model uses a 16-channel latent space, and the channels can be used for noise input, inpainting image, inpainting mask, and control inputs.
- Optimized Inference Algorithm: Based on efficient inference algorithms, such as the "Guidance Embedder", it significantly improves generation speed while maintaining high-quality output.
Project Address of Flex.2-preview
- HuggingFace Model Repository:https://huggingface.co/ostris/Flex.2-preview
Application Scenarios of Flex.2-preview
- Creative Design: Quickly generates concept art and illustrations, helping artists and designers realize their creativity.
- Image Restoration: Repairs photo defects and fills in missing parts, suitable for image editing.
- Content Creation: Generates advertising, video, and game assets, improving content production efficiency.
- Education and Research: Generates teaching materials and provides an experimental platform for AI research.
- Personalized Customization: Fine-tunes the model to generate images that match personal styles and meet specific needs.