
What is FireRedASR
FireRedASR is an industrial-grade automaticspeech recognition(ASR) model family open-sourced by Xiaohongshu, supporting Mandarin, Chinese dialects, and English, achieving a new state-of-the-art (SOTA) level on Mandarin ASR benchmarks, and performing excellently in lyrics recognition. The model family includes two main versions:
FireRedASR-LLM: Adopts the Encoder-Adapter-LLM framework, based on the capabilities of large language models (LLM), achieving SOTA performance and supporting seamless end-to-end speech interaction. On Mandarin benchmarks, the average character error rate (CER) is 3.05%, an 8.4% reduction compared to the previous SOTA model (3.33%).
FireRedASR-AED: Adopts an attention-based encoder-decoder (AED) architecture, balancing high performance and computational efficiency, and can serve as an effective speech representation module in LLM-based speech models. On Mandarin benchmarks, the average CER is 3.18%, outperforming Seed-ASR, which has over 12B parameters.
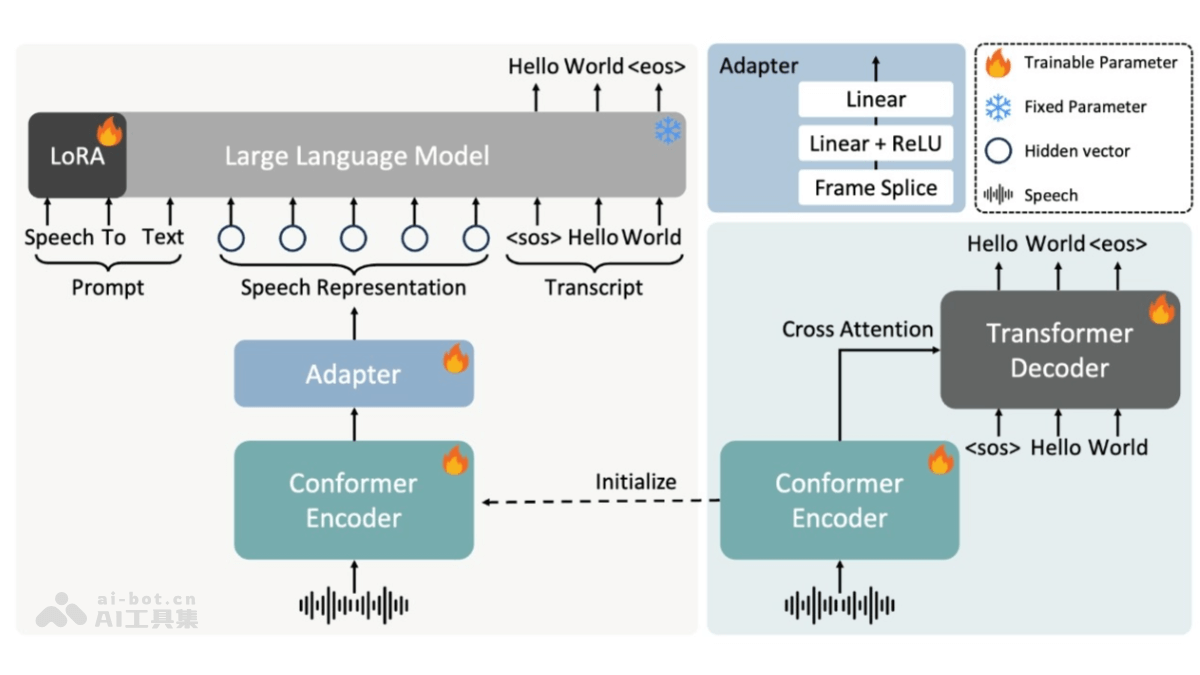
Main Features of FireRedASR
- High-Precision Speech Recognition: FireRedASR includes two versions, FireRedASR-LLM and FireRedASR-AED. Among them, FireRedASR-LLM adopts the Encoder-Adapter-LLM framework, focusing on ultimate speech recognition accuracy.
- Efficient Inference: FireRedASR-AED is based on the classic Attention-based Encoder-Decoder architecture, with 1.1B parameters, balancing high accuracy and inference efficiency.
- Multi-Scenario Adaptability: FireRedASR performs excellently in various daily scenarios, including short videos, live streaming, voice input, and intelligent assistants. Compared with industry-leading ASR service providers and Paraformer-Large, FireRedASR-LLM achieves a relative CER reduction of 23.7%~40.0%.
- Lyrics Recognition Capability: In lyrics recognition scenarios, FireRedASR-LLM achieves a relative CER reduction of 50.2%~66.7%, demonstrating extremely strong adaptability.
- Multilingual Support: FireRedASR supports Mandarin and performs excellently in Chinese dialect and English speech recognition, further broadening its application scope.
- Open Source and Community Support: FireRedASR's models and inference code are both open-sourced, promoting community-driven improvements and academic research in speech recognition technology.
Technical Principles of FireRedASR
- FireRedASR-LLM: FireRedASR-LLM adopts the Encoder-Adapter-LLM framework, combining the capabilities of large language models (LLM) to achieve ultimate speech recognition accuracy. It includes three core components:
- Conformer-based Encoder: Responsible for extracting speech features and generating continuous speech representations.
- Lightweight Adapter: Converts the encoder's output into representations that match the LLM's semantic space.
- Pretrained Text LLM: Initialized based on Qwen2-7B-Instruct, used to generate the final text output.
- Training Strategy: During training, the encoder and adapter are trainable, while most parameters of the LLM remain fixed and are fine-tuned only through Low-Rank Adaptation (LoRA). This ensures that the encoder and adapter can effectively map speech features to the LLM's semantic space while preserving the LLM's pretrained capabilities.
- Input and Inference: During inference, the input includes a prompt and speech, and the LLM performs next-token-prediction to generate the recognized text.
- FireRedASR-AED: FireRedASR-AED is based on the classic attention-based encoder-decoder (AED) architecture, balancing high performance and computational efficiency. It consists of the following parts:
- Conformer encoder: Processes speech features based on the Conformer model, capable of capturing both local and global dependencies.
- Transformer decoder: Uses the Transformer architecture for sequence transformation, including a multi-head self-attention module and a feed-forward module.
- Input features: The input features are 80-dimensional log Mel filterbanks, processed with global mean and variance normalization.
- Training data: The training data contains approximately 70,000 hours of high-quality Mandarin audio data, as well as approximately 11,000 hours of English audio data.
FireRedASR project address
- Github repository:https://github.com/FireRedTeam/FireRedASR
- HuggingFace model library:https://huggingface.co/FireRedTeam/FireRedASR-AED-L
- arXiv technical paper:https://arxiv.org/pdf/2501.14350
FireRedASR application scenarios
- Intelligent voice assistant: FireRedASR can be used to develop intelligent voice assistants, such as smart home control, intelligent customer service, etc. Its high-precision speech recognition capability can accurately understand users' voice commands and provide a smooth interaction experience.
- Video and live streaming: In the fields of short videos and live streaming, FireRedASR can generate subtitles in real time, helping viewers better understand the content.
- Lyrics recognition: FireRedASR performs particularly well in lyrics recognition scenarios and can be widely used in scenarios such as music platforms and karaoke.
- Voice input: FireRedASR can be used in voice input scenarios, such as voice typing and voice notes. Its efficient inference capability and high-precision recognition performance can significantly improve users' input efficiency.