
What is FantasyTalking
FantasyTalking is a novel framework jointly proposed by Alibaba's AMAP team and Beijing University of Posts and Telecommunications for generating realistic animatable virtual avatars from a single static portrait. Based on a pre-trained video diffusion transformer model, it adopts a two-stage audio-visual alignment strategy. The first stage establishes coherent global motion through a clip-level training scheme, and the second stage refines lip motion at the frame level through a lip tracking mask to ensure precise synchronization with the audio signal. The framework introduces a face-focused cross-attention module to maintain facial consistency, and achieves control over the intensity of expressions and body motion through a motion intensity modulation module.
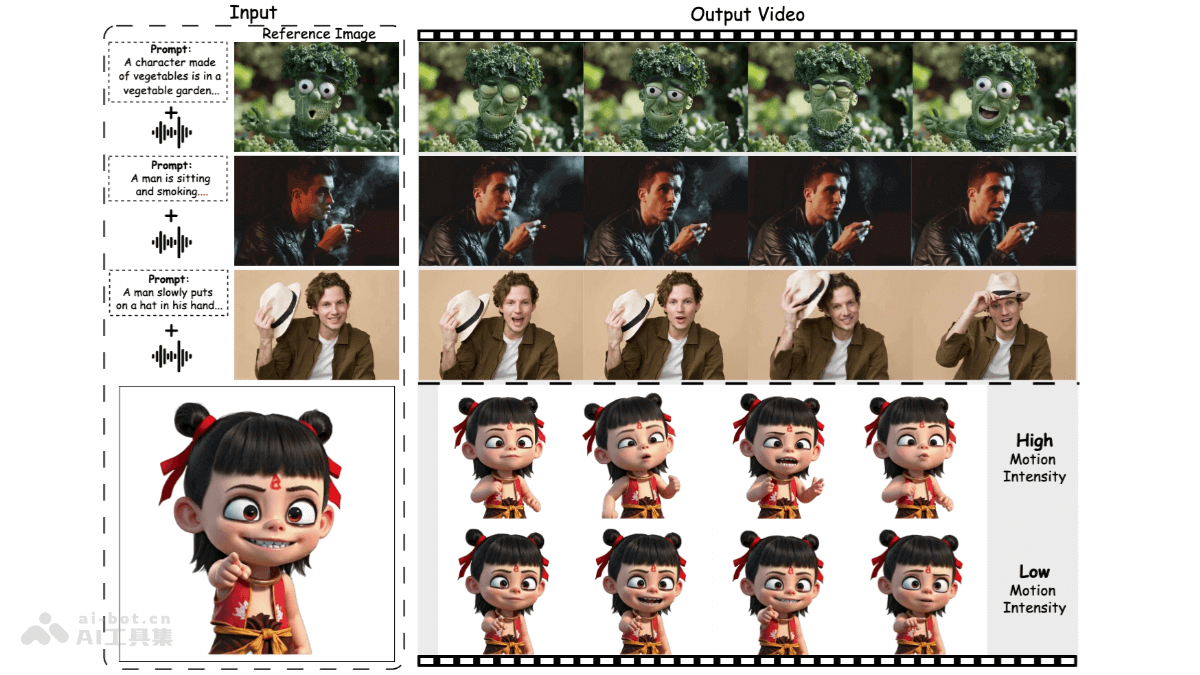
Main features of FantasyTalking
- Lip synchronization: It can accurately recognize and synchronize the lip movements of a virtual character with the input speech, making the character's lip movements when speaking completely consistent with the speech content, enhancing the character's realism and credibility.
- Facial motion generation: Based on speech content and emotional information, it generates corresponding facial movements such as blinking, frowning, and smiling, making the virtual character's expressions richer and more vivid.
- Full-body motion generation: It can generate full-body movements and postures such as walking, running, and jumping according to scene and plot requirements, making the virtual character more natural and fluid in animation.
- Motion intensity control: Through the motion intensity modulation module, users can explicitly control the intensity of facial expressions and body movements, achieving controllable manipulation of portrait motion, not limited to lip movement.
- Support for multiple styles: It supports virtual avatars in multiple styles, including realistic style and cartoon style, and can generate high-quality talking videos.
- Support for multiple poses: It supports the generation of realistic talking videos with various body ranges and orientations, including close-up portraits, half-body, full-body, as well as frontal and profile poses.
Technical principles of FantasyTalking
- Two-stage audio-visual alignment strategy
- Clip-level training: In the first stage, through a clip-level training scheme, the model captures weak correlations between the audio and the entire scene (including the reference portrait, context objects, and background), establishes global audio-visual dependencies, and achieves overall feature fusion. This enables the model to learn non-verbal cues related to the audio (such as eyebrow movements and shoulder movements) and lip dynamics strongly synchronized with the audio.
- Frame-level training: In the second stage, the model focuses on refining visual features at the frame level that are highly related to the audio, especially lip movements. By using a lip tracking mask, the model can ensure precise alignment between lip movement and the audio signal, improving the quality of the generated video.
- Identity preservation: Traditional reference network methods usually restrict large-scale natural changes in the person and background in the video. FantasyTalking adopts a face-focused cross-attention module, concentrating on modeling facial regions and decoupling identity preservation from motion generation through the cross-attention mechanism. It is more lightweight and can free the restrictions on the background and the person's natural movement, ensuring that the character's identity features are maintained throughout the generated video sequence.
- Motion intensity adjustment: FantasyTalking introduces a motion intensity modulation module that can explicitly control the intensity of facial expressions and body movements. This allows users to perform controllable manipulation of portrait motion, not limited to lip movement. By adjusting the motion intensity, more natural and diverse animations can be generated.
- Based on a pretrained video diffusion transformer model: FantasyTalking is based on the Wan2.1 video diffusion transformer model and, leveraging spatiotemporal modeling capabilities, generates high-fidelity, coherent talking portrait videos. The model can effectively capture the relationship between audio signals and lip movements, facial expressions, and body motions, generating high-quality dynamic portraits.
FantasyTalking's project address
- Project website:https://fantasy-amap.github.io/fantasy-talking/
- Github repository:https://github.com/Fantasy-AMAP/fantasy-talking
- arXiv technical paper:https://arxiv.org/pdf/2504.04842
FantasyTalking's application scenarios
- Game development: In game development, FantasyTalking can be used to generate dialogue animations and combat animations for game characters. It can generate precise lip synchronization, rich facial expressions, and natural full-body movements based on speech content, making game characters more vivid and realistic, and enhancing the game's visual effects and players' immersion.
- Film and television production: In film and television production, it can be used to generate performance animations and special effects animations for virtual characters. Through FantasyTalking, virtual characters with complex expressions and movements can be quickly generated, reducing the manpower and time costs in traditional animation production, and adding more creativity and imagination to film and television works.
- Virtual reality and augmented reality: In virtual reality (VR) and augmented reality (AR) applications, FantasyTalking can generate interactive animations and guidance animations for virtual characters.
- Virtual streamers: FantasyTalking can be used to generate animated videos of virtual streamers. It supports virtual avatars in multiple styles, and virtual streamers can be used in various scenarios such as news broadcasting, livestream e-commerce, and online education, with high practicality and flexibility.
- Intelligent education: In the field of intelligent education, FantasyTalking can generate animated videos of virtual teachers or virtual teaching assistants.